SDE 級聯
用一個兩階段的結構化資料抽取級聯(mini → verify → reasoning),以一小部分成本拿到大推理模型的大部分質量。
- 概覽
- 大推理模型能很好地抽取結構化資料,但慢且貴
- 小模型便宜,但會犯錯
- 一個級聯能以一小部分成本拿到大部分質量
- 我們用的模型及其價格($ / 每 100 萬 token,輸入 / 輸出;標準費率,2026 年 9 月 15 日查詢):
- 第 0 級(mini):
gpt-5.4-mini,$0.75 / $4.50 - 第 1 級(reasoning):
gpt-5.5,$5.00 / $30.00(約為 mini 的 7 倍) - 校驗器:TypeSafe
jev-1.12,$0.042 / $0.00(輸出 token 免費;見已釋出的 Jev 價格)
- 第 0 級(mini):
- 演算法
- 用便宜 / 小的模型抽取。
- 用 TypeSafe 原語校驗:每個欄位一個是非(「Noul 問題」)問題
- (例如「這個值在源文本中缺失嗎?」「它是從無關文本里搬來的嗎?」),各返回 P(有錯)。
- 如果某個校驗訊號觸發,就升級到昂貴的推理模型;否則保留便宜答案。
- 本 Cookbook
- 端到端走一個真例項子,然後展示跨 100 條提示詞的權衡
- 注意:兩個抽取級別都用文本模式的 OpenAI
- 我們不使用結構化輸出、工具呼叫或 json 模式,因為:
- schema 遵循類的錯誤不是我們預期 LLM 會犯的錯誤(為它造合成數據很容易)
- 如果 LLM 確實沒遵循 schema,它幾乎總是非常困惑,所以約束解碼並不能解決根本問題
- 不過我們鼓勵你試試它們!
環境準備
- 安裝依賴(TypeSafe 校驗器客戶端由 TypeSafe 的包索引提供):
pip install openai datasets jsonschema ipython 'cooksafe>=0.2.0,<0.3.0'- 然後在環境裡設定
OPENAI_API_KEY和TYPESAFE_API_KEY
import json
import os
from pathlib import Path

import jsonschema
from cooksafe import JsonCache, make_playground_link
from datasets import load_dataset
from IPython.display import Markdown, display
from openai import OpenAI
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

MINI = "gpt-5.4-mini"  # rung 0: cheap + fast
REASONING = "gpt-5.5"  # rung 1: strong, run with reasoning_effort="high"
TS_MODEL = "jev-1.12"  # the TypeSafe verifier model
FIRE_T = 0.7  # escalate if any per-field P(wrong) exceeds this; also the "<== FIRES" display marker

oai = OpenAI()

ts = TypeSafeClient(api_key=os.environ["TYPESAFE_API_KEY"], timeout=30.0)
第 1 步:資料
我們選一個叫 scrapegraphai 的 HuggingFace 資料集
SCRAPEGRAPHAI_REVISION = "4bb9fba1dff9181c5acdb60a5a26fea62fa54fe9"
row = load_dataset(
    "scrapegraphai/scrapegraphai-100k",
    revision=SCRAPEGRAPHAI_REVISION,
    split="train",
)[516]
schema = json.loads(row["schema"])
prompt = row["prompt"]
content = row["content"]

print(
    f"""
PROMPT
===========
{prompt}

SCHEMA
===========
{json.dumps(schema, indent=2)}

CONTENT
===========
{content}
""".strip()
)
PROMPT
===========
Find registration open date fall semester for New York University in New York, NY for the 2024-2025 school year.
SCHEMA
===========
{
"properties": {
"registration_open_date": {
"description": "The date that registration opens for the fall semester. MUST be in the format mm/dd/yyyy. For example, for a college in the 2024-2025 school year, it might be something like 09/05/2024. Return a blank string if you are unsure.",
"title": "Registration Open Date",
"type": "string"
},
"description": {
"description": "A brief description of the registration open date. For example, 'Registration opens for the fall semester'.",
"title": "Description",
"type": "string"
}
},
"required": [
"registration_open_date",
"description"
],
"title": "RegistrationOpen",
"type": "object"
}
CONTENT
===========
Skip to content Skip to current page navigation
[ ](https://www.nyu.edu/)
Search Site
[ ](https://www.nyu.edu/)
* [ Academics](https://www.nyu.edu/academics.html)
* [ Admissions](https://www.nyu.edu/admissions.html)
* [ Research](https://www.nyu.edu/research.html)
* [ University Life](https://www.nyu.edu/life.html)
* [ About](https://www.nyu.edu/about.html)
All NYU
# Mobile Navigation
[ ](https://www.nyu.edu/)
Search Site
* [Academics](https://www.nyu.edu/academics.html)
* [Admissions](https://www.nyu.edu/admissions.html)
* [Research](https://www.nyu.edu/research.html)
* [University Life](https://www.nyu.edu/life.html)
* [About](https://www.nyu.edu/about.html)
All NYU
Info for
* Back to main menu
* Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](http://home.nyu.edu/)
Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](https://home.nyu.edu/)
Search Site Search
# Events Calendar
Search Events
Apply Reset
* [About the Events Calendar ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar.html)
* [Events Calendar Tutorial ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar/tutorials.html)
* [Report issue or provide feedback ](https://nyu.service-now.com/sp?id=sc_cat_item&sys_id=7698dd2a98bcf4004c8c03063d84e274)
Search Filters Calendar
New York University
Equal Opportunity and Non-Discrimination at NYU - New York University is committed to maintaining an environment that encourages and fosters respect for individual values and appropriate conduct among all persons. In all University spaces--physical and digital--programming, activities, and events are carried out in accordance with applicable law as well as University policy, which includes but is not limited to its Non-Discrimination and Anti-Harassment Policy.
Unless otherwise noted, all content copyright New York University. All rights reserved.
* [Search](https://search.nyu.edu/)
* [Campus Map](https://www.nyu.edu/map.html)
* [Events](https://events.nyu.edu/)
* [Contact Us](https://www.nyu.edu/contact-us.html)
* [Give](https://www.nyu.edu/about/giving.html)
* [Copyright & Fair Use](https://www.nyu.edu/copyright-and-fair-use.html)
* [Privacy](https://www.nyu.edu/privacy.html)
* [Accessibility](https://www.nyu.edu/accessibility.html)
* [Feedback](https://www.nyu.edu/#feedback.html)
* [New York Campus](https://www.nyu.edu/)
* [Abu Dhabi Campus](https://nyuad.nyu.edu/)
* [Shanghai Campus](https://shanghai.nyu.edu/)
* [](https://facebook.com/)
* [](https://linkedin.com/)
* [](https://x.com/)
* [](https://instagram.com/)
* [](https://youtube.com/)- 這一行是一個 NYU 活動日曆頁面(「Fall 2024 Census Date」):
- schema 只要求兩個欄位:
registration_open_date和description - 抓取到的內容只有日曆導航和樣板文字:既沒有註冊日期,也沒有描述
- 注意 schema 的
description欄位甚至在自己的欄位描述裡給了一個示例值(「Registration opens for the fall semester」)
- schema 只要求兩個欄位:
- 所以一個規矩的抽取器應該拒絕去編造頁面裡沒有的欄位
- 我們來看看小模型會不會做對!
第 2 步:用 mini 模型抽取(文本模式)
- 注意:
gpt-5.4-mini在這個輸入上非常隨機——即便temperature=0,它幾乎每次執行都會編造出不同的description。為了得到可復現的走查,我們硬編碼了本 notebook 餘下部分要講的那一個典型編造(校驗器把它標為 P(wrong) > 0.8)。真實的流水線會直接呼叫extract(MINI, prompt, schema, content, temperature=0)。
EXTRACT_SYSTEM = (
    "You extract structured data from documents. Return only values supported by the text. "
    "Follow any value format specified by the schema or its field descriptions."
)

# LLM and TypeSafe calls are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published results with no API spend; delete the file to re-run live.
json_cache = JsonCache(Path("json_cache.json"))

@json_cache
def extract(
    model: str,
    prompt: str,
    schema: dict,
    content: str,
    *,
    reasoning_effort: str | None = None,
    temperature: float | None = None,
) -> dict:
    user = (
        f"{prompt}\n\nReturn ONLY a JSON object matching this JSON Schema:\n"
        f"{json.dumps(schema, indent=2)}\n\nDocument:\n{content}"
    )
    kwargs = {
        "model": model,
        "messages": [
            {"role": "system", "content": EXTRACT_SYSTEM},
            {"role": "user", "content": user},
        ],
    }
    if reasoning_effort:
        kwargs["reasoning_effort"] = reasoning_effort
    if temperature is not None:
        kwargs["temperature"] = temperature
    text = oai.chat.completions.create(**kwargs).choices[0].message.content
    # The prompt asks for ONLY a JSON object, so parse the reply as-is -- no regex fishing a
    # substring out of a malformed reply. If ``json.loads`` fails, treat it as an empty extraction
    # (the record-level analog of NaN): every field reads as absent, which the verifier flags and the
    # gate escalates -- the safe direction. Schema-following errors are rare here (see the overview).
    try:
        return json.loads(text)
    except (ValueError, json.JSONDecodeError):
        return {}

# Hard-coded canonical fabrication (see note above); a real pipeline would use extract(MINI, prompt, schema, content, temperature=0).
mini_record = {
    "registration_open_date": "",
    "description": "Registration opens for the fall semester",
}
print("mini extraction:\n", json.dumps(mini_record, indent=2))

# The record is a perfect fit for the JSON Schema -- and still wrong. Schema validation is necessary
# but not sufficient: it catches structural errors, never semantic ones. That gap is the whole point.
print("\nschema-valid:", jsonschema.Draft202012Validator(schema).is_valid(mini_record))
mini extraction:
{
"registration_open_date": "",
"description": "Registration opens for the fall semester"
}
schema-valid: True- 這條記錄通過了 schema 校驗(上面那行列印
True),但它是錯的:registration_open_date留空,這與頁面一致:頁面沒有給出日期- 但
description是編造的:頁面從未描述註冊日期,於是 mini 編了一個看似合理的。它可能照搬 schema 自帶的示例「Registration opens for the fall semester」,或者敘述「…was not found in the document」 - JSON-Schema 檢檢視不到這一點。便宜的模型會產生這種自信、滿足 schema 的編造,而抓出它們是語義校驗器的職責
第 3 步:用 TypeSafe 校驗
- 校驗器是 TypeSafe;我們為每個欄位構建一個
Noul問題:- 一個狹窄的是非問題,措辭讓
true= 有錯(要升級)
- 一個狹窄的是非問題,措辭讓
- TypeSafe 在一次 system_one 呼叫裡為每個問題返回校準過的
noul=P(true) - 問題集:
- 一個整體性的
__overall__::judge頭問題(「這條記錄該升級嗎?」)。我們計算並展示它,是為了把「整條記錄的判斷」與各欄位的頭問題做對比,但第 4 步的門控並不使用它——升級由逐欄位的問題組驅動。 - 一個逐欄位的問題組
- 非空欄位拿到全部頭問題
- 空欄位(null / “” / [])只拿
absence_wrong這一個頭問題
- (完整流水線對整體容器還有一個
spurious頭問題,以及一個總體的difficultyscore;為把這次走查收斂到兩個門控頭問題,這裡不展示)
- 一個整體性的
- TypeSafe 的方式:分解
- 注意一切都經過程式化分解,這就是 TypeSafe 的方式。
- 分解把每個提示詞的智慧最大化,並讓演算法可調、可解釋。
-
# metric -> (question, NoulCriteria)
MAIN_QUESTIONS = {
    "name_desc_mismatch": (
        "Does the `extracted_field` fail to match the field at `path` or the `description` in the "
        "`field_spec`? If the `description` is empty, judge against the `path` alone.",
        NoulCriteria(
            true="the `extracted_field` does not match the field name or its `description`",
            false="the `extracted_field` matches the field name and `description`",
        ),
    ),
    "type_mismatch": (
        "Does the `extracted_field` violate the `type` declared in the `field_spec`?",
        NoulCriteria(
            true="the `extracted_field` violates the declared `type`",
            false="the `extracted_field` conforms to the declared `type`",
        ),
    ),
    "unreasonable": (
        "Is the `extracted_field` one that a reasonable person would not have extracted for this "
        "`field_spec`?",
        NoulCriteria(
            true="a reasonable person would not have extracted this value",
            false="the extraction is reasonable",
        ),
    ),
    "hallucinated": (
        "Is the `extracted_field` unsupported by, or absent from, the source text?",
        NoulCriteria(
            true="the `extracted_field` is a hallucination -- not supported by, or absent "
            "from, the source text",
            false="the `extracted_field` is supported by the source text",
        ),
    ),
    "off_target": (
        "Does the source text fail to genuinely report the thing the `field_spec` describes, so the "
        "value was pulled from incidental text?",
        NoulCriteria(
            true="the source does not genuinely provide this field -- the value was pulled "
            "from incidental text",
            false="the source genuinely reports this field",
        ),
    ),
    "incomplete": (
        "Does the `extracted_field` fail to capture a value the source supports (note whether the "
        "`field_spec` is `required`)?",
        NoulCriteria(
            true="the field is wrongly empty, null, or missing a value the source supports",
            false="the field captures the value the source supports",
        ),
    ),
    "format_violation": (
        "Does the `extracted_field` violate the format or constraints implied by the `description`, "
        "the schema `type`, and the extraction instructions (e.g. date format, units, enum membership)?",
        NoulCriteria(
            true="the `extracted_field` violates the implied format or constraints",
            false="the `extracted_field` satisfies the format and constraints",
        ),
    ),
}
ABSENCE_QUESTION = (
    "The `extracted_field` is empty, null, or an empty collection. Does the source text contain the "
    "information the `field_spec` describes, making the empty result wrong?"
)
ABSENCE_CRITERIA = NoulCriteria(
    true="a value was wrongly omitted", false="returning nothing is correct"
)

# The pipeline also asks one holistic, whole-record head: "should this be escalated?"
OVERALL_JUDGE = (
    "Is this extracted record an incorrect extraction -- some value unsupported by the source or "
    "not conforming to the schema, required information missing or wrong, or some field hallucinated -- "
    "so it should be escalated to a smarter model?"
)
OVERALL_JUDGE_CRITERIA = NoulCriteria(
    true="the record is an incorrect extraction",
    false="the record is a correct extraction",
)

def is_empty(v) -> bool:
    return v is None or (isinstance(v, (str, list, dict)) and len(v) == 0)

def field_spec(name: str) -> dict:
    """Minimal spec pulled from the schema (unwrapping anyOf/null for optional fields)."""
    p = schema["properties"][name]
    branches = p.get("anyOf") or []
    typ = p.get("type") or next(
        (b["type"] for b in branches if b.get("type") != "null"), "unknown"
    )
    return {
        "path": name,
        "type": typ,
        "description": p.get("description", ""),
        "required": name in schema.get("required", []),
    }

def build_questions(record: dict) -> dict[str, Noul]:
    """The verify question set: one holistic ``__overall__::judge`` head plus a per-field battery,
    keyed ``field::metric`` (mirrors build_verify_prompts)."""
    questions: dict[str, Noul] = {
        "__overall__::judge": Noul(
            instructions=OVERALL_JUDGE, criteria=OVERALL_JUDGE_CRITERIA
        ),
    }
    for name, value in record.items():
        spec = field_spec(name)
        if is_empty(value):
            questions[f"{name}::absence_wrong"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": ABSENCE_QUESTION,
                },
                criteria=ABSENCE_CRITERIA,
            )
            continue
        for metric, (question, criteria) in MAIN_QUESTIONS.items():
            if metric == "type_mismatch" and spec["type"] == "unknown":
                continue
            questions[f"{name}::{metric}"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": question,
                },
                criteria=criteria,
            )
    return questions

@json_cache
def verify(record: dict) -> dict[str, float | str]:
    """Run the whole Noul battery over a record in one TypeSafe call; return ``{field::metric: P(true)}``."""
    state = {
        "system_message": EXTRACT_SYSTEM,
        "instruction": "Extract the structured record from this document",
        "source_text": row["content"],
        "schema": schema,
        "extraction": record,
    }
    questions = build_questions(record)
    answers = ts.system_one(state=state, questions=questions, model=TS_MODEL).answers
    return {qid: ans.noul for qid, ans in answers.items()} | {
        "playground_link": make_playground_link(state, questions)
    }
對 mini 抽取結果跑完整個問題組
checks = verify(mini_record)
playground_link = checks.pop("playground_link")
display(
    Markdown(
        f"🔗 [Open this verification in the TypeSafe playground]({playground_link})"
    )
)

print(f"{'qid':<40}{'P(wrong)':>9}")
print("-" * 50)
for fld, p in sorted(checks.items(), key=lambda c: -c[-1]):
    flag = "  <== FIRES" if p > FIRE_T else ""
    print(f"{fld:<40}{p:>9.2f}{flag}")
qid P(wrong)
--------------------------------------------------
description::hallucinated 0.95 <== FIRES
description::off_target 0.85 <== FIRES
description::unreasonable 0.58
__overall__::judge 0.56
description::incomplete 0.16
registration_open_date::absence_wrong 0.14
description::format_violation 0.10
description::name_desc_mismatch 0.08
description::type_mismatch 0.02- TypeSafe 把訊號集中到真正出錯的欄位上。
- 我們的結果是校準過的:出錯的欄位高,正確的欄位低,看起來不對但沒有明顯錯誤的欄位居中
- 這就是一個 typesafe 校驗器比起一個粗糙的「整體好不好?」判斷器能帶給你的
第 4 步:升級門控
- 現在我們按
any_flag門控:只要有任何欄位的標記超過FIRE_T(0.7,在上面設定,與第 3 步的<== FIRES標記共用)就升級 - 這是一個
max式的門控(只要任何欄位觸發就升級),不是均值,所以一個自信的紅旗就夠,而不會被平均到無聲
# any_flag is a per-field gate: the holistic __overall__ head is shown above but not part of it
fired = {
    qid: p
    for qid, p in checks.items()
    if not qid.startswith("__overall__") and p > FIRE_T
}
escalate = bool(fired)

print(
    f"any_flag gate (threshold {FIRE_T}): {'ESCALATE' if escalate else 'ACCEPT cheap result'}"
)
for qid, p in sorted(fired.items(), key=lambda c: -c[1]):
    print(f"  fired: {qid}  (P={p:.2f})")
any_flag gate (threshold 0.7): ESCALATE
fired: description::hallucinated (P=0.95)
fired: description::off_target (P=0.85)第 5 步:升級到推理模型
既然有訊號觸發,我們就掏錢用強模型(gpt-5.5,reasoning_effort="high")
final_record = (
    extract(REASONING, prompt, schema, content, reasoning_effort="high")
    if escalate
    else mini_record
)

print("mini      :", json.dumps(mini_record))
print("reasoning :", json.dumps(final_record))
print("\nfield-level diff (mini -> final):")
for name in mini_record:
    if mini_record[name] != final_record.get(name):
        print(f"  {name}: {mini_record[name]!r}  ->  {final_record.get(name)!r}")
mini : {"registration_open_date": "", "description": "Registration opens for the fall semester"}
reasoning : {"description": "", "registration_open_date": ""}
field-level diff (mini -> final):
description: 'Registration opens for the fall semester' -> ''- 改進之處
- 推理模型丟掉了編造的
description,返回"" - 它識別出頁面從未描述註冊日期,於是拒絕編造一個
- 級聯把一個自信、通過 schema 校驗的編造,變成了一個誠實的空欄位
- 而且它只在這一項上花了推理模型的錢,因為校驗器讓它這麼做
- 推理模型丟掉了編造的
第 6 步:100 條提示詞上的表現
- 這些是 TypeSafe 的內部結果,用上面那套通用方法產生:
- 同一個
extract → verify → escalate迴圈,gpt-5.4-mini → gpt-5.5-reasoning,對逐欄位頭問題做any_flag門控,在 100 條 scrapegraphai 提示詞上執行 - 每一項的便宜級抽取由 TypeSafe 打分;門控閾值(「cut」)從 0 掃到 1,每個得到的配置都畫在(成本,質量)空間裡
- 這張圖是歷史快照;其中的成本沒有按上面列出的當前 Jev 費率重新計算
- 同一個
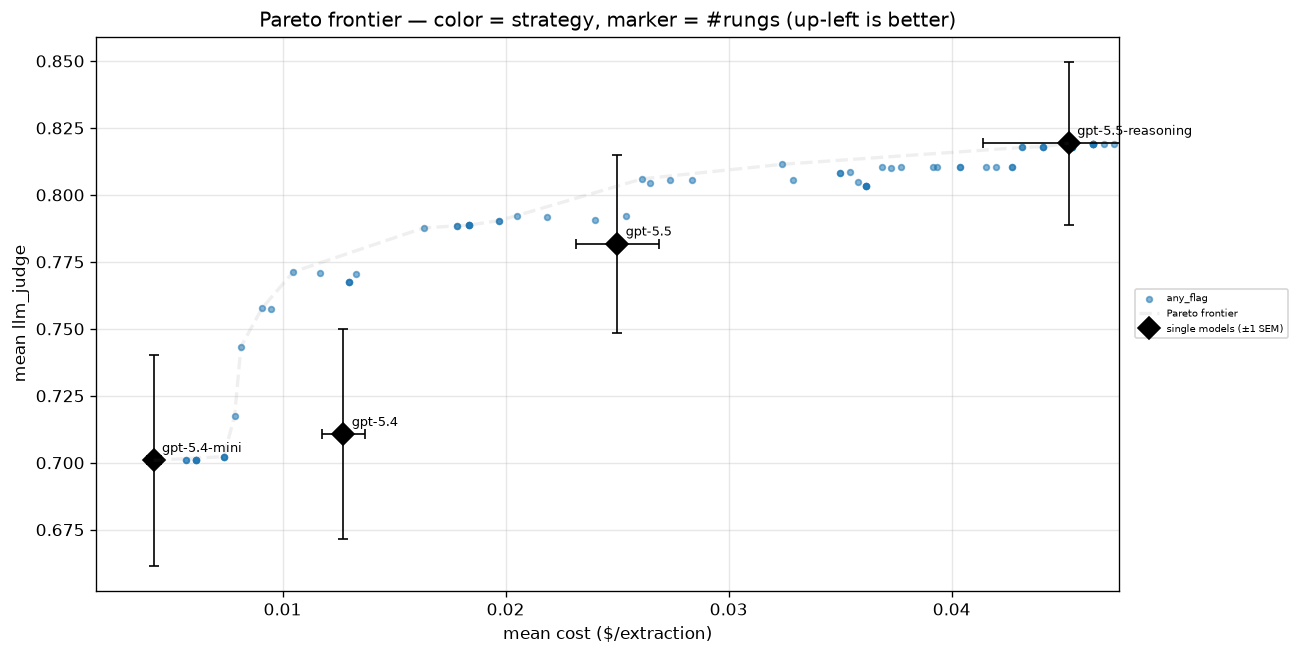
- 怎麼讀它:
- 黑色菱形 = 四個模型各自單獨執行(成本隨能力上升;最強的
gpt-5.5-reasoning位於右上角,約 0.81 質量,約 $0.10 / 次抽取) - 藍色點 = 級聯在不同門控閾值下的表現;虛線是 pareto 前沿
- 級聯的前沿位於每個單獨模型的左上方:掃一遍門控閾值,你就能以一小部分成本拿到最強模型的大部分質量
- 便宜那一級幾乎免費地處理簡單項,只有被標記的項才為推理模型付費
- 黑色菱形 = 四個模型各自單獨執行(成本隨能力上升;最強的
附錄 A:什麼構成好的校驗器訊號
- 級聯的好壞取決於它的校驗器;有用的訊號與無用的訊號差別在哪:
- 狹窄且有據可依。
- 針對一個欄位、對照源文本的一個可檢查的是非問題(例如「這個值在源文本中缺失嗎?」),而不是含糊的「這次抽取好嗎?」
- 含糊的問題給出糊里糊塗、未經校準的分數
- Bad = TRUE,且 criteria 明確。
- 把每個問題都設計成:升級的情形對應
true,並說明true/false的含義
- 把每個問題都設計成:升級的情形對應
- 逐欄位,然後用
max聚合。- 逐欄位的標記能定位錯誤,並保持稀疏而強
max(「任何標記觸發」)保證一個自信的紅旗就升級,而不是被平均到無聲
- 獨立且便宜。
- 一個專門的校驗器(這裡是 TypeSafe)來評判輸出,能抓出抽取器自身的盲點
- 它必須便宜,否則就沒有可省的錢了
- 有區分度 / 校準過。
- 好的訊號在真實錯誤上高、在正確結果上低,因此單一閾值就能幹淨地劃分「接受」與「升級」
- 正是這種區分度把 pareto 曲線推向左上方
- 狹窄且有據可依。