預解析取值抽取
用正則找出候選的郵箱、電話號碼和金額,再讓 TypeSafe 選出問題所要的那一段,好讓程式碼把原樣的值歸一化。
正則找出候選值,TypeSafe 挑出問題所要的那一個,程式碼原樣複製。
這裡的 find 和 pick 這對搭檔,可以直接指向你自己的文件;三個完整的例子演示了它的用法:發件人希望把發票發去的地址、格式為 +14155550177 的電話號碼,以及一條被標記為扣款的、金額為 1315.50 USD 的發票總額。
TypeSafe 只能在你交給它的選項裡挑一個,所以候選必須先被找出來。整個過程分三步:正則找到候選,TypeSafe 挑一個,程式碼再複製挑中的結果:
- 用正則從文本里找出候選值。把正則調得寧可多找。
- TypeSafe 挑出問題問的是哪個候選,並讀出程式碼下游需要的屬性(貨幣、國家、一筆金額是貸記還是扣款)。
- 程式碼複製挑中的值並歸一化。
因為 TypeSafe 只在正則找到的那些片段裡做選擇,你拿回的值必然是其中之一,原樣未改。它不可能憑空編出一個值,也不會把數字的順序調轉。
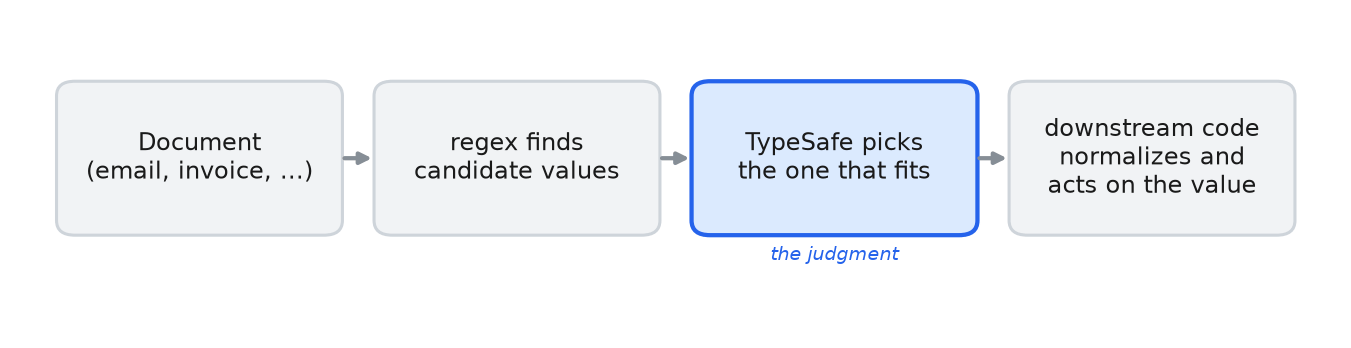
正則在文件裡找到候選值,TypeSafe 挑中一個,下游程式碼再把它歸一化並據此行動。
準備工作
pip install ipython phonenumbers 'cooksafe>=0.2.0,<0.3.0'然後設定 TYPESAFE_API_KEY。
import os
import re
from decimal import Decimal
from pathlib import Path

import phonenumbers
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Choice, Noul, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
NONE = "none"  # the escape hatch on every selection: "none of the candidates fits"

# base_url defaults to https://api.typesafe.ai/ ; the env override points at another deployment.
ts = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # cached re-renders need no key
    base_url=os.environ.get("TYPESAFE_BASE_URL"),
    timeout=30.0,
)
json_cache = JsonCache(Path("json_cache.json"))
輔助函式
find 跑一個調成寧多勿缺的正則,並對匹配去重。pick 是一個 Choice 問題,它的選項就是 find 返回的那些片段,所以它的答案要麼是其中某個片段的精確複製,要麼是沒有候選合適時的 none。classify 是一個在一組固定標籤上做選擇的 Choice 問題,這裡用來判斷貨幣和國家。is_true 是一個 Noul,這裡用來問一筆金額是不是貸記。
每次呼叫都快取到 json_cache.json,所以重新渲染不會發出任何 API 呼叫。
EMAIL_RE = re.compile(r"[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+\.[A-Za-z]{2,}")
PHONE_RE = re.compile(r"\(?\+?\d[\d\s()\-.]{6,}\d")
MONEY_RE = re.compile(r"[$€£¥]\s?\d[\d,]*(?:\.\d{2})?")

def find(pattern: re.Pattern, text: str) -> list[str]:
    """Code-side candidate finder: recall-tuned regex, deduped, in document order."""
    seen: set[str] = set()
    out: list[str] = []
    for match in pattern.findall(text):
        span = match.strip()
        if span and span not in seen:
            seen.add(span)
            out.append(span)
    return out

@json_cache
def pick(document: str, candidates: list[str], question: str) -> dict:
    """TypeSafe selects which found span plays the role. Returns {choice, confidence}.

    The options ARE the candidate spans, so ``choice`` is a verbatim copy of one of them (or the
    ``none`` hatch) - the model chooses, code owns the string."""
    criteria = {c: None for c in candidates} | {
        NONE: "None of these is the requested value."
    }
    answer = ts.system_one(
        state=document,
        questions={"pick": Choice(instructions=question, criteria=criteria)},
        model=TYPESAFE_MODEL,
    ).answers["pick"]
    return {"choice": answer.choice, "confidence": answer.confidence}

@json_cache
def classify(document: str, question: str, options: list[str]) -> dict:
    """A small Choice over a fixed label set (currency, country, ...). Returns {choice, confidence}."""
    answer = ts.system_one(
        state=document,
        questions={
            "q": Choice(instructions=question, criteria={o: None for o in options})
        },
        model=TYPESAFE_MODEL,
    ).answers["q"]
    return {"choice": answer.choice, "confidence": answer.confidence}

@json_cache
def is_true(document: str, question: str) -> float:
    """A yes/no Noul. Returns P(yes)."""
    return (
        ts.system_one(
            state=document,
            questions={"q": Noul(instructions=question)},
            model=TYPESAFE_MODEL,
        )
        .answers["q"]
        .noul
    )
郵箱:按角色挑出正確的地址
郵件頭裡有 4 個地址。正文要求把發票發到一個個人地址,而不是 To: 那個賬單別名,所以答案取決於正文怎麼讀。這裡問兩個問題:發票發給哪個地址,以及這條訊息是從哪個地址發出的。
EMAIL_DOC = """From: Dana Whit <dana.whit@acme-corp.com>
To: billing@acme-corp.com
Cc: orders@acme-corp.com
Reply-To: dana.personal@gmail.com

Hi team - please don't use the billing alias for this one. Send my receipt to my
personal address instead. Thanks, Dana."""

emails = find(EMAIL_RE, EMAIL_DOC)
receipt = pick(
    EMAIL_DOC, emails, "Which email address does the sender want their receipt sent to?"
)
sender = pick(
    EMAIL_DOC, emails, "Which email address did this message come from (the From line)?"
)

print("candidates :", emails)
# code copies the picked value verbatim and normalizes (lowercase); it never re-types it
print(
    f"receipt -> : {receipt['choice'].lower():<28} (conf {receipt['confidence']:.2f})"
)
print(f"sender  -> : {sender['choice'].lower():<28} (conf {sender['confidence']:.2f})")
candidates : ['dana.whit@acme-corp.com', 'billing@acme-corp.com', 'orders@acme-corp.com', 'dana.personal@gmail.com']
receipt -> : dana.personal@gmail.com (conf 0.98)
sender -> : dana.whit@acme-corp.com (conf 1.00)receipt 是 Reply-To: 那一行的個人 Gmail 地址,正是正文要求的;sender 是 From 那一行的地址。兩者都是正則匹配結果的複製,在程式碼裡轉成了小寫。
電話:挑出手機號,歸一化為 E.164
3 個號碼,都沒有國家區號。TypeSafe 挑出手機號,並從文本里讀出國家;phonenumbers 把這兩個答案合成為 E.164 —— 以 + 和國家區號開頭的國際格式。
PHONE_DOC = """Reach our San Francisco office at these numbers: main desk (415) 555-0199,
billing fax (415) 555-0142, and my direct cell (415) 555-0177. Call the cell if it's urgent."""

phones = find(PHONE_RE, PHONE_DOC)
mobile = pick(PHONE_DOC, phones, "Which of these is the direct mobile / cell number?")
region = classify(
    PHONE_DOC,
    "In what country is this office located?",
    ["US", "GB", "DE", "FR", "CA", "AU"],
)

# code copies the picked value and normalizes it with the model-supplied country
parsed = phonenumbers.parse(mobile["choice"], region["choice"])
e164 = phonenumbers.format_number(parsed, phonenumbers.PhoneNumberFormat.E164)

print("candidates :", phones)
print(f"mobile  -> : {mobile['choice']}  (conf {mobile['confidence']:.2f})")
print(f"country -> : {region['choice']}  (conf {region['confidence']:.2f})")
print(f"E.164   -> : {e164}")
candidates : ['(415) 555-0199', '(415) 555-0142', '(415) 555-0177']
mobile -> : (415) 555-0177 (conf 1.00)
country -> : US (conf 0.90)
E.164 -> : +14155550177這些數字本身說明不了哪個是手機號、號碼在哪個國家;說明這些的是它們周圍的文字。TypeSafe 讀那些文字,phonenumbers 再把挑中的號碼格式化成 +14155550177。
金額:挑出金額、判斷貨幣、標記貸記還是扣款
一張發票上有 4 筆金額。TypeSafe 挑出應付總額和那筆貸記,讀出貨幣,並把每一筆挑中的金額標記為扣款或貸記。程式碼複製每個挑中的字串,解析成 Decimal。
MONEY_DOC = """Invoice INV-2087.
Subtotal: $1,200.00
Sales tax: $115.50
Total due: $1,315.50
A $50.00 courtesy credit from last month has already been applied."""

amounts = find(MONEY_RE, MONEY_DOC)
currency = classify(
    MONEY_DOC,
    "What currency are these amounts in?",
    ["USD", "EUR", "GBP", "JPY", "CAD"],
)
total = pick(MONEY_DOC, amounts, "Which amount is the total the customer must pay?")
credit = pick(
    MONEY_DOC, amounts, "Which amount is the courtesy credit that was applied?"
)

def to_decimal(value: str) -> Decimal:
    """Copy the picked value and parse the number in code (US grouping/decimal here)."""
    return Decimal(re.sub(r"[^\d.]", "", value))

for label, chosen in [("total due", total), ("credit", credit)]:
    is_credit = is_true(
        MONEY_DOC,
        f"Is the amount {chosen['choice']} a credit or refund to the customer, not a charge?",
    )
    kind = "credit" if is_credit > 0.5 else "charge"
    print(
        f"{label:<10}: {chosen['choice']:<10} -> {to_decimal(chosen['choice'])} {currency['choice']} "
        f"({kind}, P(credit)={is_credit:.2f})"
    )
print("\ncandidates :", amounts)
total due : $1,315.50 -> 1315.50 USD (charge, P(credit)=0.01)
credit : $50.00 -> 50.00 USD (credit, P(credit)=0.99)
candidates : ['$1,200.00', '$115.50', '$1,315.50', '$50.00']應付總額是 $1,315.50,貸記是 $50.00,都以 USD 計。判斷貸記還是扣款的 Noul 在總額上給出 0.01,在貸記上給出 0.99,於是程式碼知道自己解析的每個 Decimal 是什麼符號。
to_decimal假定逗號是千位分隔符,點是小數點。對$1,315.50如此;而在€1.315,50里正好相反。可以用一個Noul問題問文件用的是哪種約定,再在程式碼裡據此分支。
在 TypeSafe Playground 裡開啟
一個分享連結,在瀏覽器裡開啟這段郵件對話,帶上發票那個問題,選項裡包含正則找到的那 4 個地址。
receipt_criteria = {e: None for e in emails} | {
    NONE: "None of these is the requested value."
}
playground_link = make_playground_link(
    EMAIL_DOC,
    {
        "receipt": Choice(
            instructions="Which email address does the sender want their receipt sent to?",
            criteria=receipt_criteria,
        )
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this thread + selection in the TypeSafe playground]({playground_link})"
    )
)兩個限制
- 一個
Choice問題最多允許 255 個選項。候選比這還多時,就分兩步收窄:先挑出是哪一段,再挑出這一段的哪個片段。 - 找候選才是真正費功夫的部分。郵箱、電話號碼和金額都有現成的正則覆蓋;人名沒有,它的候選只能來自你手上已有的名冊,或者來自一個能提出候選的命名實體識別器或 LLM。然後由 TypeSafe 挑出問題所要的那一個。