自動研究式特徵發現
執行一個自動研究迴圈:由它提出 TypeSafe 問題,把自由文本轉成數值特徵,並用模型誤差改進一個有監督的 CatBoost 迴歸器。
TypeSafe 問題把自由文本變成有監督 CatBoost 模型的數值特徵;用自動研究迴圈去發現它們。
CatBoost 需要一張數字表,而一條品酒筆記不是。這份 cookbook 用關於筆記的問題把這張表搭出來,而且這些問題沒有一個是手寫的。LLM 提出這些問題,TypeSafe 為每一行作答,CatBoost 拿答案來訓練。自動研究的部分在後面:CatBoost 報告它用了哪些問題、哪些行它仍然預測錯,下一輪提議呼叫讀取這份報告,迴圈再次執行。
讀到最後,你會得到一個可以指向你自己帶標註文本的迴圈、一條每輪留出誤差的曲線,以及一張最終模型用得最多的問題表。
tasting note
    |
    v
38 TypeSafe answers
    |-- 29 score questions x 2 columns = 58
    |     expected rubric level + answer uncertainty
    `--  9 noul questions  x 1 column  =  9
          probability true
    |
    v
67 numeric columns --> CatBoost --> predicted critic score
                                     held-out RMSE: 1.77 points
一個 score 答案會變成兩列:答案指向的平均檔位,以及它在那個平均值周圍有多分散。一個 noul 答案是一個機率,所以是一列。
資料是 2,000 條葡萄酒評論:輸入一條品酒筆記,輸出這位評論家 80-100 分的評分。RMSE 用評論分點數衡量預測誤差,錯得越多權重越大,越低越好。下面表裡的每個數字都來自模型和迴圈都沒見過的 800 條評論。
| 筆記如何變成評分 | RMSE |
|---|---|
| 預測訓練行的平均分 | 3.09 |
| 同一個 CatBoost,把筆記當作詞頻來讀 | 2.47 |
| 直接讓 TypeSafe 給出評分,再縮放和平移 | 2.15 |
| 一次提議呼叫給出的 18 個問題,不跑迴圈 | 1.87 |
| 跑五輪迴圈後的 38 個問題 | 1.77 |
最後兩行就是迴圈。一次提議呼叫,當時還無跡可循,就到了 1.87。再讀四輪它自己最差的預測,到了 1.77。大部分收益都在第一次呼叫裡;後面那四輪又加了多少,在下面測量。
from __future__ import annotations
import json
import os
import random
import textwrap
import urllib.request
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from time import perf_counter
from typing import NamedTuple
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from catboost import CatBoostRegressor
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from typesafe_sdk import Noul, NoulCriteria, Score, TypeSafeClient
matplotlib.use("Agg") # headless render
TYPESAFE_MODEL = "jev-1.12"
FOLDS, REPEATS = 5, 3 # repeats steady the error at this sample size
CATBOOST = dict(
iterations=400,
depth=4,
learning_rate=0.05,
loss_function="RMSE",
verbose=0,
random_seed=0,
thread_count=1,
allow_writing_files=False,
)
client = TypeSafeClient(
# keyless kernels replay the cache
api_key=os.environ.get("TYPESAFE_API_KEY", "cache-only"),
base_url=os.environ.get("TYPESAFE_ENDPOINT"),
timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
# ----------------------------------------------------------------- the specification
INTENSITY_LEVELS = [
"Not present in this note at all",
"Barely present - mentioned once, in passing",
"Present at a moderate level",
"Present strongly - the note dwells on it",
"Dominant - the note is largely about this",
]
PRESENCE_CRITERIA = NoulCriteria(
true="The note states this or clearly implies it",
false="The note gives no indication of this",
)
# Asking for the score outright: ten quality bands, rescaled onto the 80-100 critic scale.
SCORE_LEVELS = [
"Faulty or unpleasant - the note is mostly criticism",
"Barely acceptable - drinkable, with nothing to recommend it",
"Simple and sound - correct, plain, forgettable",
"Pleasant everyday wine - some appeal, little depth",
"Good - clear varietal character, well made",
"Very good - balanced, with something to say",
"Excellent - complex and structured",
"Outstanding - depth and length, built to age",
"Superb - among the best of its type",
"Profound - the note treats it as exceptional",
]
# Structured output requires every property in `required`, so unused fields come back empty.
PROPOSAL_SCHEMA = {
"type": "object",
"properties": {
"actions": {
"type": "array",
"items": {
"type": "object",
"properties": {
"op": {"type": "string", "enum": ["add", "revise", "drop"]},
"target": {"type": "string"},
"name": {"type": "string"},
"kind": {"type": "string", "enum": ["intensity", "presence"]},
"question": {"type": "string"},
},
"required": ["op", "target", "name", "kind", "question"],
"additionalProperties": False,
},
}
},
"required": ["actions"],
"additionalProperties": False,
}
PROPOSALS = 18 # actions the proposer may return per round
# The one string that knows this is about wine. Point it at your own label and text.
PROPOSER_TASK = f"""You are designing numeric features for a gradient-boosting model that
predicts the score a wine critic gave (an integer from 80 to 100) from the tasting note alone.
The model sees nothing but the features you design.
Return up to {PROPOSALS} actions. Each action is one of:
- {{"op": "add", "target": "", "name": ..., "kind": ..., "question": ...}}
A new feature.
- {{"op": "revise", "target": <name of an existing feature>, "name": ..., "kind": ...,
"question": ...}}
Replace that feature's question with better wording. Use this when a feature measures the
right thing badly: too narrow, too vague, or worded so nearly every note answers the same.
- {{"op": "drop", "target": <name of an existing feature>, "name": "", "kind": "intensity",
"question": ""}}
Remove a feature that is not earning its place.
`kind` is "intensity" for something with a degree, or "presence" for a yes/no fact.
`question` is what gets asked about one tasting note.
An "intensity" question is graded against this fixed five-level rubric, so word it so that the
levels make sense:
{chr(10).join(f" {i}. {level}" for i, level in enumerate(INTENSITY_LEVELS))}
A "presence" question is answered as the probability that it is true of the note.
Good features can be judged from the note's own words, vary from note to note, and carry
information about quality that the other features do not. Reviewers describe structure, fruit,
oak, length, complexity, and drinkability, and they also signal quality through word choice."""
class Split(NamedTuple):
"""The rows, their labels, and which half the loop is allowed to read."""
notes: list[str]
scores: np.ndarray
dev: np.ndarray
test: np.ndarray
# ----------------------------------------------------------------- the data
WINEMAG_CSV = (
"https://huggingface.co/datasets/GroNLP/ik-nlp-22_winemag/resolve/"
"90eb39f35fc64e556fc17f06d4137a4a69ec3297/train.csv"
)
@json_cache
def load_slice(n_dev: int, n_test: int, seed: int) -> dict:
"""Fetch the pinned CSV and take a seeded sample of note + score, one row per note."""
import csv
import io
request = urllib.request.Request(
WINEMAG_CSV, headers={"User-Agent": "typesafe-cookbook/1.0"}
)
with urllib.request.urlopen(request, timeout=300) as response:
text = response.read().decode()
rows, seen = [], set()
for row in csv.DictReader(io.StringIO(text)): # a few notes repeat verbatim
if not row["description"] or not row["points"] or row["description"] in seen:
continue
seen.add(row["description"])
rows.append((row["description"], float(row["points"])))
random.Random(seed).shuffle(rows)
picked = rows[: n_dev + n_test]
return {"notes": [r[0] for r in picked], "points": [r[1] for r in picked]}
def example_rows(split: Split, out_of_fold: np.ndarray | None, n: int) -> list[int]:
"""Select representative dev rows for a proposer round."""
dev = split.dev
if out_of_fold is None:
ranked = dev[np.argsort(split.scores[dev], kind="stable")]
return [int(ranked[round(q * (len(ranked) - 1))]) for q in np.linspace(0, 1, n)]
error = np.abs(split.scores[dev] - out_of_fold)
order = np.argsort(-error, kind="stable")
worst = [int(dev[i]) for i in order[: n // 2]]
best = [int(dev[i]) for i in order[len(order) - (n - n // 2) :]]
return worst + best
def example_block(
rows: list[int],
split: Split,
out_of_fold: np.ndarray | None,
previous: np.ndarray | None = None,
) -> str:
"""Format selected rows for the proposer."""
if out_of_fold is None:
head = "Example notes, with the score each one was given:"
body = [f"- scored {split.scores[r]:.0f}: {split.notes[r]}" for r in rows]
return head + "\n" + "\n".join(body)
head = (
"Dev notes, worst-predicted first. The first half is where your current questions "
"miss by the most and the second half is where they are already right, so what "
"separates the halves is what the questions have not captured."
)
if previous is not None:
head += (
" Each line also carries what the previous round predicted, so you can see which "
"notes your last batch of questions moved."
)
body = []
for r in rows:
line = f"- scored {split.scores[r]:.0f}, predicted {out_of_fold[r]:.1f}"
if previous is not None:
line += f" (last round {previous[r]:.1f})"
body.append(f"{line}: {split.notes[r]}")
return head + "\n" + "\n".join(body)
def load_split(n_dev: int, n_test: int, seed: int = 0) -> Split:
# keyword, because the cache key is the function name plus how each argument was spelled
data = load_slice(n_dev, n_test, seed=seed)
return Split(
notes=data["notes"],
scores=np.array(data["points"]),
dev=np.arange(n_dev),
test=np.arange(n_dev, n_dev + n_test),
)
# ----------------------------------------------------------------- step 1: propose
def proposal_prompt(examples: str, feedback: str, accepted: list[dict]) -> str:
parts = [PROPOSER_TASK, "\n" + examples]
if accepted:
parts.append(
"\nThe features you have now. `add` must not duplicate one of these; `revise` and "
"`drop` refer to one by name:\n"
+ "\n".join(
f"- {f['name']} ({f['kind']}): {f['question']}" for f in accepted
)
)
if feedback:
parts.append("\nHow the model did with those features:\n" + feedback)
return "\n".join(parts)
@json_cache
def propose(model: str, round_index: int, prompt: str) -> dict:
"""One proposal call. Every number in `prompt` is rounded so a replay hits the cache."""
if model.startswith("claude"):
import anthropic
response = anthropic.Anthropic(
api_key=os.environ.get("ANTHROPIC_API_KEY", "cache-only")
).messages.create(
model=model,
max_tokens=16000,
output_config={
"effort": "medium",
"format": {"type": "json_schema", "schema": PROPOSAL_SCHEMA},
},
messages=[{"role": "user", "content": prompt}],
)
body = next(block.text for block in response.content if block.type == "text")
usage = [response.usage.input_tokens or 0, response.usage.output_tokens or 0]
else:
from openai import OpenAI
response = OpenAI(
api_key=os.environ.get("OPENAI_API_KEY", "cache-only")
).chat.completions.create(
model=model,
reasoning_effort="high",
max_completion_tokens=16000,
response_format={"type": "json_object"},
messages=[
{
"role": "user",
"content": prompt
+ "\n\nReply with JSON matching this schema:\n"
+ json.dumps(PROPOSAL_SCHEMA),
}
],
)
body = response.choices[0].message.content
usage = [response.usage.prompt_tokens, response.usage.completion_tokens]
return {"actions": json.loads(body)["actions"][:PROPOSALS], "usage": usage}
def slug(name: str, taken: set[str]) -> str:
"""Names become question ids and column labels, so keep them plain and unique."""
base = (
"".join(c if c.isalnum() else "_" for c in name.lower()).strip("_") or "feature"
)
candidate, n = base, 2
while candidate in taken:
candidate, n = f"{base}_{n}", n + 1
return candidate
def to_candidates(actions: list[dict], accepted: list[dict], round_index: int) -> tuple:
"""Split a round's actions into screenable candidates and a list of names to drop."""
live = {f["name"] for f in accepted}
drops = [a["target"] for a in actions if a["op"] == "drop" and a["target"] in live]
replacing = {
a["target"] for a in actions if a["op"] == "revise" and a["target"] in live
}
# a revision may keep the name it replaces, since that feature is on its way out
taken, candidates = live - replacing, []
for action in actions:
if action["op"] == "drop":
continue
if action["op"] == "revise" and action["target"] not in live:
continue # a revision of something that is not there
name = slug(action["name"], taken)
taken.add(name)
candidates.append(
{
"id": f"{name}@{round_index}", # unique, so earlier rounds keep their columns
"name": name,
"kind": action["kind"],
"question": action["question"],
"replaces": action["target"] if action["op"] == "revise" else "",
}
)
return candidates, drops
# ----------------------------------------------------------------- step 2: answer
def feature_questions(features: list[dict]) -> dict:
questions = {}
for feature in features:
if feature["kind"] == "intensity":
questions[feature["name"]] = Score(
instructions=feature["question"], criteria=INTENSITY_LEVELS
)
else:
questions[feature["name"]] = Noul(
instructions=feature["question"], criteria=PRESENCE_CRITERIA
)
return questions
@json_cache
def answer(model: str, note: str, features_json: str) -> dict:
"""One request per note; every question of the round rides it. Keeps every probability."""
features = json.loads(features_json)
started = perf_counter()
response = client.system_one(
state=note, questions=feature_questions(features), model=model
)
raw = {}
for feature in features:
got = response.answers[feature["name"]]
if feature["kind"] == "intensity":
raw[feature["name"]] = [
got.probabilities.get(i, 0.0) for i in range(len(INTENSITY_LEVELS))
]
else:
raw[feature["name"]] = [got.noul]
return {
"raw": raw,
"seconds": round(perf_counter() - started, 2),
"input_tokens": response.usage.input_tokens or 0,
"output_tokens": response.usage.output_tokens or 0,
}
def featurize(notes: list[str], features: list[dict]) -> dict:
"""Answer one question set for many notes: one request each, eight in flight."""
payload = json.dumps(features, sort_keys=True)
with ThreadPoolExecutor(max_workers=8) as pool:
results = list(
pool.map(lambda note: answer(TYPESAFE_MODEL, note, payload), notes)
)
return {
f["name"]: np.array([r["raw"][f["name"]] for r in results], dtype=float)
for f in features
}
def encode(feature: dict, probabilities: np.ndarray, mode: str) -> list[tuple]:
"""Turn one question's probabilities into named columns."""
name = feature["name"]
if feature["kind"] == "presence":
return [(name, probabilities[:, 0])] # one number is all there is
levels = np.arange(probabilities.shape[1])
mean = probabilities @ levels
if mode == "mean":
return [(name, mean)]
if mode == "mean_spread":
variance = probabilities @ (levels**2) - mean**2
return [(name, mean), (f"{name}_sd", np.sqrt(np.clip(variance, 0, None)))]
return [(f"{name}_p{i}", probabilities[:, i]) for i in levels]
def design(features: list[dict], answers_for: dict, mode: str) -> tuple:
"""Stack every feature's columns into one matrix, plus a label per column."""
columns, labels = [], []
for feature in features:
for label, column in encode(feature, answers_for[feature["id"]], mode):
columns.append(column)
labels.append(label)
return np.column_stack(columns), labels
def plain(features: list[dict]) -> list[dict]:
"""What goes on the wire and into the cache key: no id, no bookkeeping."""
return [
{"name": f["name"], "kind": f["kind"], "question": f["question"]}
for f in features
]
# ----------------------------------------------------------------- step 3: fit
def rmse(y: np.ndarray, p: np.ndarray) -> float:
return float(np.sqrt(np.mean((y - p) ** 2)))
def spearman(a: np.ndarray, b: np.ndarray) -> float:
"""Rank correlation: does the model order the wines the way the critic did?"""
ranks = (
np.argsort(np.argsort(a)).astype(float),
np.argsort(np.argsort(b)).astype(float),
)
return float(np.corrcoef(*ranks)[0, 1])
def folds(y: np.ndarray, k: int, seed: int) -> list[np.ndarray]:
"""Label-stratified k-fold: sort by the label with a seeded tiebreak, then deal off the top."""
rng = np.random.default_rng(seed)
order = np.lexsort((rng.random(len(y)), y))
return [np.sort(order[i::k]) for i in range(k)]
def cross_validate(X: np.ndarray, y: np.ndarray) -> tuple[np.ndarray, float]:
out_of_fold = np.zeros((REPEATS, len(y)))
for repeat in range(REPEATS):
for fold in folds(y, FOLDS, seed=repeat):
train = np.setdiff1d(np.arange(len(y)), fold)
model = CatBoostRegressor(**CATBOOST).fit(X[train], y[train])
out_of_fold[repeat, fold] = model.predict(X[fold])
scores = [rmse(y, out_of_fold[repeat]) for repeat in range(REPEATS)]
return out_of_fold.mean(axis=0), float(np.mean(scores))
def importances(X: np.ndarray, y: np.ndarray) -> np.ndarray:
return CatBoostRegressor(**CATBOOST).fit(X, y).get_feature_importance()
def paired_gain(y: np.ndarray, before: np.ndarray, after: np.ndarray) -> tuple:
"""Bootstrap the paired held-out RMSE change."""
squared = ((y - before) ** 2, (y - after) ** 2)
rng = np.random.default_rng(0)
drawn = []
for _ in range(2000):
rows = rng.integers(0, len(y), len(y))
drawn.append(
np.sqrt(squared[1][rows].mean()) - np.sqrt(squared[0][rows].mean())
)
drawn = np.array(drawn)
return (
rmse(y, after) - rmse(y, before),
float(np.percentile(drawn, 2.5)),
float(np.percentile(drawn, 97.5)),
)
def fit_predict(X: np.ndarray, split: Split) -> np.ndarray:
model = CatBoostRegressor(**CATBOOST).fit(X[split.dev], split.scores[split.dev])
return model.predict(X[split.test])
def fit_predict_text(split: Split) -> np.ndarray:
"""The reference arm: the same model, handed the note instead of the columns."""
from catboost import Pool
raw = np.array([[note] for note in split.notes], dtype=object)
model = CatBoostRegressor(**CATBOOST).fit(
Pool(raw[split.dev], split.scores[split.dev], text_features=[0])
)
return model.predict(Pool(raw[split.test], text_features=[0]))
def evaluate(
features: list[dict], answers_for: dict, split: Split, mode: str
) -> tuple[np.ndarray, float]:
"""Cross-validated error on the dev rows for one candidate question set."""
X, _ = design(features, answers_for, mode)
return cross_validate(X[split.dev], split.scores[split.dev])
def swap_in(accepted: list[dict], feature: dict) -> list[dict] | None:
"""The accepted set with `feature` in place of the one it revises, or None if it is gone."""
at = next(
(i for i, f in enumerate(accepted) if f["name"] == feature["replaces"]), None
)
if at is None:
return None
trial = list(accepted)
trial[at] = {k: feature[k] for k in ("id", "name", "kind", "question")}
return trial
def try_change(
trial: list[dict],
accepted: list[dict],
cv: float,
answers_for: dict,
split: Split,
mode: str,
tolerance: float,
) -> tuple[list[dict], float, str, bool]:
"""Refit with the change and keep it only if the dev error improves. No API calls."""
_, cv_trial = evaluate(trial, answers_for, split, mode)
if cv_trial <= cv + tolerance:
return trial, cv_trial, f"CV {cv:.3f} -> {cv_trial:.3f}", True
return accepted, cv, f"would cost {cv_trial - cv:+.3f}", False
def owner_of(label: str, features: list[dict]) -> dict:
"""Which feature a column label belongs to - encodings suffix the name."""
exact = next((f for f in features if f["name"] == label), None)
if exact:
return exact
return next(f for f in features if label.startswith(f["name"] + "_"))
def importance_per_feature(
features: list[dict], labels: list[str], column_importances: np.ndarray
) -> dict:
"""Sum each question's CatBoost column importances.
Intensity questions can produce multiple model columns. Combining their normalized
importances gives one percentage share per question.
"""
total = {f["name"]: 0.0 for f in features}
for label, column_importance in zip(labels, column_importances):
total[owner_of(label, features)["name"]] += float(column_importance)
return total
def feedback_for(
history: list[float],
accepted: list[dict],
answers_for: dict,
split: Split,
mode: str,
out_of_fold: np.ndarray,
previous: np.ndarray | None,
) -> str:
"""The scoreboard the next proposal call reads. The notes themselves arrive separately,
through `example_block`. Numbers are rounded before they enter the prompt."""
X, labels = design(accepted, answers_for, mode)
dev, scores = split.dev, split.scores
by_name = importance_per_feature(accepted, labels, importances(X[dev], scores[dev]))
lines = ["Cross-validated RMSE in points so far, lower is better:"]
lines += [f" round {i + 1}: {v:.2f}" for i, v in enumerate(history)]
if previous is not None:
now, before = np.abs(scores[dev] - out_of_fold), np.abs(scores[dev] - previous)
better, worse = int((now < before - 0.1).sum()), int((now > before + 0.1).sum())
lines.append(
f"\nAgainst the previous round, {better} of the {len(dev)} dev notes are now "
f"predicted better by more than 0.1 points and {worse} are predicted worse."
)
lines.append(
"\nYour features, with importance as a percentage of the total and the spread of the "
"column across the dev rows. Low importance or low spread means the question is not "
"doing much; revise or drop it."
)
for feature in sorted(accepted, key=lambda f: -by_name.get(f["name"], 0.0)):
column = encode(feature, answers_for[feature["id"]], mode)[0][1]
lines.append(
f" {feature['name']} ({feature['kind']}): "
f"{by_name.get(feature['name'], 0.0):.1f}% importance, "
f"spread {column[dev].std():.2f}"
)
return "\n".join(lines)
# ----------------------------------------------------------------- the loop itself
class Discovery(NamedTuple):
"""Artifacts returned by the discovery loop."""
accepted: list[dict] # the question set it ended with
answers_for: dict # feature id -> (rows x levels) probabilities
snapshots: list[list[dict]] # the set as it stood at the end of each round
history: list[float] # dev CV error after each round
batches: list[tuple] # what each round sent, for the request table
journal: list[tuple] # every action and what became of it
def run_loop(
split: Split,
proposer: str,
rounds: int,
examples: int,
mode: str,
min_spread: float,
tolerance: float,
) -> Discovery:
"""Run the propose, answer, fit, and feedback loop."""
shown = example_rows(split, None, examples) # round 1 has nothing predicted yet
out_of_fold = previous = None
got_from = Discovery([], {}, [], [], [], [])
accepted, answers_for = got_from.accepted, got_from.answers_for
snapshots, history = got_from.snapshots, got_from.history
batches, journal = got_from.batches, got_from.journal
feedback = ""
for round_index in range(1, rounds + 1):
block = example_block(shown, split, out_of_fold, previous)
actions = propose(
proposer, round_index, proposal_prompt(block, feedback, accepted)
)["actions"]
keep, drops = to_candidates(actions, accepted, round_index)
if keep: # one request per row, carrying every question this round proposed
batches.append((round_index, plain(keep)))
answers = featurize(split.notes, plain(keep))
for feature in keep:
answers_for[feature["id"]] = answers[feature["name"]]
for (
feature
) in keep: # an add goes in; importance says later whether it earned it
if feature["replaces"]:
continue
column = encode(feature, answers_for[feature["id"]], mode)[0][1]
flat = float(column[split.dev].std()) < min_spread
journal.append(
(round_index, "flat" if flat else "add", feature["name"], "")
)
if not flat:
accepted.append(
{k: feature[k] for k in ("id", "name", "kind", "question")}
)
_, cv = evaluate(accepted, answers_for, split, mode)
trial_args = (answers_for, split, mode, tolerance)
for feature in [f for f in keep if f["replaces"]]: # every revision is tried
trial = swap_in(accepted, feature)
if trial is None: # it revises something an earlier round already dropped
journal.append(
(round_index, "stale", feature["name"], "target is gone")
)
continue
accepted[:], cv, note, took = try_change(trial, accepted, cv, *trial_args)
what = "revise" if took else "reject"
journal.append(
(
round_index,
what,
feature["name"],
f"was {feature['replaces']}, {note}",
)
)
for name in drops: # and so is every drop
trial = [f for f in accepted if f["name"] != name]
if not trial:
continue
accepted[:], cv, note, took = try_change(trial, accepted, cv, *trial_args)
journal.append((round_index, "drop" if took else "keep", name, note))
previous, (out_of_fold, cv) = (
out_of_fold,
evaluate(accepted, answers_for, split, mode),
)
history.append(cv)
snapshots.append(list(accepted))
feedback = feedback_for(
history, accepted, answers_for, split, mode, out_of_fold, previous
)
# next round reads the rows these questions get most wrong, and as many they get right
shown = example_rows(split, out_of_fold, examples)
report(round_index, keep, drops, journal, accepted, cv)
return got_from
def report(
round_index: int,
keep: list[dict],
drops: list[str],
journal: list[tuple],
accepted: list[dict],
cv: float,
) -> None:
"""One block per round: the counts, the names it added, then everything with a number."""
revised = sum(1 for f in keep if f["replaces"])
print(
f"round {round_index}: {len(keep) - revised} add, {revised} revise, "
f"{len(drops)} drop"
)
this_round = [j for j in journal if j[0] == round_index]
added = [name for _, what, name, _ in this_round if what == "add"]
if added:
print(
textwrap.fill(
", ".join(added),
88,
initial_indent=" added ",
subsequent_indent=" " * 10,
)
)
for _, what, name, note in this_round: # everything carrying a number of its own
if what != "add":
print(f" {what:<7}{name:<34}{note}")
print(f" -> {len(accepted)} features, dev CV RMSE {cv:.3f}\n")
# ----------------------------------------------------------------- asking for the score
@json_cache
def ask_score(model: str, note: str) -> dict:
"""One `Score` over ten quality bands, read as a level and rescaled to 80-100."""
response = client.system_one(
state=note,
questions={
"quality": Score(
instructions=(
"Judging only by what this tasting note says, how good is the wine?"
),
criteria=SCORE_LEVELS,
)
},
model=model,
)
got = response.answers["quality"]
top = len(SCORE_LEVELS) - 1
expected = sum(k * v for k, v in got.probabilities.items())
return {
# level 0 is the bottom of the critic's scale, level 9 the top
"expected": 80.0 + 20.0 * expected / top,
"picked": 80.0 + 20.0 * got.score / top,
"input_tokens": response.usage.input_tokens or 0,
"output_tokens": response.usage.output_tokens or 0,
}
# ----------------------------------------------------------------- charts
SURFACE, INK, INK2, MUTED = "#fcfcfb", "#0b0b0b", "#52514e", "#898781"
GRID, AXIS, BLUE, ORANGE = "#e1e0d9", "#c3c2b7", "#2a78d6", "#eb6834"
def style(ax) -> None:
ax.set_facecolor(SURFACE)
for side in ("top", "right"):
ax.spines[side].set_visible(False)
for side in ("left", "bottom"):
ax.spines[side].set_color(AXIS)
ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
ax.set_axisbelow(True)
def polarity(feature: dict, answers_for: dict, split: Split) -> float:
"""Rank correlation between a question's answer and the critic score, on the dev rows.
Positive means a higher answer goes with a better review, negative the opposite. It is
what orders the rows of the feature map, so the map reads as a gradient that flips.
"""
column = encode(feature, answers_for[feature["id"]], "mean")[0][1]
return spearman(column[split.dev], split.scores[split.dev])
def reviews_heatmap(
plt,
questions: list[dict],
answers_for: dict,
split: Split,
rows: tuple,
):
"""Compare held-out reviews across the discovered questions, best-signal first.
Rows arrive sorted from the questions that rise with the score to the ones that fall with
it, so a row above the divider shades left to right and a row below it shades right to
left.
"""
def value_of(feature: dict, row: int) -> float:
return float(encode(feature, answers_for[feature["id"]], "mean")[0][1][row])
signs = [polarity(question, answers_for, split) for question in questions]
flip = next((i for i, s in enumerate(signs) if s < 0), len(questions))
raw = np.array(
[[value_of(question, row) for row in rows] for question in questions]
)
normalized = np.array(
[
values / (4 if question["kind"] == "intensity" else 1)
for question, values in zip(questions, raw)
]
)
cmap = matplotlib.colors.LinearSegmentedColormap.from_list(
"typesafe_heat", [SURFACE, "#f7c7ad", ORANGE]
)
fig, ax = plt.subplots(
figsize=(9.5, 1.8 + 0.58 * len(questions)), facecolor=SURFACE
)
image = ax.imshow(normalized, aspect="auto", cmap=cmap, vmin=0, vmax=1)
row_labels = []
for question, sign in zip(questions, signs):
kind = "score" if question["kind"] == "intensity" else "noul"
prefix = f"{sign:+.2f} ({kind}) "
lines = textwrap.wrap(
" ".join(question["question"].split()),
width=52,
max_lines=2,
placeholder="...",
break_long_words=False,
break_on_hyphens=False,
)
row_labels.append(prefix + (f"\n{' ' * len(prefix)}").join(lines))
column_labels = [
f"#{i}\n{split.scores[row]:.0f} points\n{' '.join(split.notes[row].split())[:15]}..."
for i, row in enumerate(rows, 1)
]
ax.set_yticks(np.arange(len(questions)), row_labels)
ax.set_xticks(np.arange(len(rows)), column_labels)
ax.tick_params(
axis="x", top=True, labeltop=True, bottom=False, labelbottom=False, pad=8
)
ax.tick_params(axis="y", labelsize=8.5)
for side in ax.spines.values():
side.set_visible(False)
ax.set_xticks(np.arange(-0.5, len(rows), 1), minor=True)
ax.set_yticks(np.arange(-0.5, len(questions), 1), minor=True)
ax.grid(which="minor", color=SURFACE, linewidth=2)
ax.tick_params(which="minor", bottom=False, left=False)
for i, question in enumerate(questions):
for j, value in enumerate(raw[i]):
label = (
f"{value:.1f}" if question["kind"] == "intensity" else f"{value:.2f}"
)
color = SURFACE if normalized[i, j] > 0.58 else INK2
ax.text(j, i, label, ha="center", va="center", color=color, fontsize=8)
# the line where the questions stop rising with the score and start falling with it
if 0 < flip < len(questions):
ax.axhline(flip - 0.5, color=INK, linewidth=1.2)
ax.annotate(
"a higher answer means a worse review, below this line",
(len(rows) - 0.5, flip - 0.5),
xytext=(-4, 5),
textcoords="offset points",
va="bottom",
ha="right",
color=INK2,
fontsize=8.5,
)
colorbar = fig.colorbar(image, ax=ax, fraction=0.025, pad=0.025)
colorbar.set_ticks([0, 0.5, 1])
colorbar.set_label("normalized answer", color=INK2, fontsize=8.5)
colorbar.ax.tick_params(labelsize=8, colors=INK2)
fig.suptitle(
"Every question, on five held-out reviews from worst to best",
x=0.01,
y=0.995,
ha="left",
color=INK,
fontsize=11,
)
fig.text(
0.01,
0.972,
"sorted by how the answer moves with the score, so each row above the line shades "
"left to right and each row below it shades the other way",
color=MUTED,
fontsize=9,
)
fig.text(
0.01,
0.005,
"Row labels lead with the rank correlation between that question's answer and the "
"critic score. Cell text is each question's native scale: score 0-4, noul 0-1.",
color=MUTED,
fontsize=8.5,
)
return fig
def rounds_chart(
plt, curve: list[tuple], history: list[float], n_test: int, gain: tuple
):
"""Dev error and held-out error per round. The trend is the point, not the gap."""
rounds = list(range(1, len(curve) + 1))
values = [v for _, v in curve]
fig, ax = plt.subplots(figsize=(7, 3.9), facecolor=SURFACE)
style(ax)
ax.grid(axis="y", color=GRID, linewidth=0.8)
# each dev fold trains on four fifths of the rows, so the dev line sits the higher of the two
ax.fill_between(rounds, history, values, color=GRID, alpha=0.75, linewidth=0)
ax.plot(
rounds,
history,
marker="o",
color=BLUE,
linewidth=2,
linestyle="--",
label="dev, cross-validated - what the loop optimises",
)
ax.plot(
rounds,
values,
marker="o",
color=ORANGE,
linewidth=2,
label="held out - what that actually buys",
)
# label each point on the outside of the pair, so neither line crowds its own numbers
for x, dev_value, test_value in zip(rounds, history, values):
for value, other in ((dev_value, test_value), (test_value, dev_value)):
ax.annotate(
f"{value:.2f}",
(x, value),
textcoords="offset points",
xytext=(0, 8 if value >= other else -16),
ha="center",
color=INK2,
fontsize=8.5,
)
ax.set_xticks(
rounds, [f"round {x}\n{n} features" for x, (n, _) in zip(rounds, curve)]
)
ax.set_ylabel("RMSE in points (lower is better)", color=INK2, fontsize=9)
# tight around the two lines: the whole finding lives inside 0.15 of a point
low, high = min(values + history), max(values + history)
ax.set_ylim(low - 0.10, high + 0.05)
difference, low_ci, high_ci = gain
ax.set_title(
f"{len(rounds)} rounds of the loop, scored on {n_test} held-out reviews",
loc="left",
color=INK,
fontsize=11,
pad=20,
)
# the number the chart is really about: is the held-out move bigger than the noise?
ax.text(
0,
1.015,
f"round 1 to round {len(rounds)}, held out: {difference:+.3f} points, "
f"95% CI [{low_ci:+.3f}, {high_ci:+.3f}]",
transform=ax.transAxes,
color=MUTED,
fontsize=9,
)
ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="lower left")
return fig準備
pip install anthropic openai catboost numpy matplotlib ipython 'cooksafe>=0.2.0,<0.3.0'然後設定 TYPESAFE_API_KEY 和 ANTHROPIC_API_KEY。每次 API 呼叫都快取到 json_cache.json,它隨 cookbook 一起釋出,所以重新渲染會重放這些數字,而不用呼叫任何介面。把它刪掉就能重跑即時。這些數字來自 2026-08-03 的 TypeSafe jev-1.12 和 claude-sonnet-5。propose() 還有一條針對 gpt-5.6-luna 的分支,沒有跑過。
第一個程式碼單元就是全部實現:API 呼叫、編碼方式、指標、圖表樣式。放在這兒是為了這個檔案能獨立執行,文件站會把它摺疊起來。第一遍讀的時候跳過它 —— 配方從它下面開始。
N_DEV, N_TEST = 1200, 800  # the loop reads dev labels only; test is scored once
ROUNDS = 5  # a round answers questions for all 2,000 rows: 2,000 requests
PROPOSER = "claude-sonnet-5"  # or "gpt-5.6-luna"; the cache holds the Anthropic run
EXAMPLES = 60  # dev notes the proposer reads per round, half of them its worst misses
MIN_SPREAD = 0.05  # a column this flat cannot separate anything, so it is not kept
CHANGE_TOLERANCE = 0.0  # a revision or drop has to improve dev error, not just not hurt
ENCODING = "mean_spread"  # a score answer becomes two columns: its mean and spread

split = load_split(N_DEV, N_TEST, seed=0)
NOTES, SCORES, DEV, TEST = split.notes, split.scores, split.dev, split.test

print(
    f"{len(DEV)} dev rows, {len(TEST)} held out; scores run "
    f"{SCORES.min():.0f}-{SCORES.max():.0f}, mean {SCORES.mean():.2f}, sd {SCORES.std():.2f}"
)
print(f"\none of the notes:\n{NOTES[0]}")
1200 dev rows, 800 held out; scores run 80-98, mean 88.73, sd 3.17
one of the notes:
A Champagne that is very much wine. The structure and the richness are just right for a food wine, showing ripe acidity, flavors of plums and apricots, and balancing these primary fruits with a dense, complex structure that takes in yeast, maturity and a tight apple skin finish.迴圈反覆讀取 2,000 行裡的同樣 1,200 行(dev 行),只要一個問題有助於預測這 1,200 個分數就保留它。在同樣的行上評分,多半隻會衡量迴圈把自己擬合到這些行上的程度,所以另外 800 行被留出,最後只評一次。
兩類問題
被提出的問題屬於兩類之一,類別決定返回什麼數字。
intensity會變成一個Score,用於任何有程度之分的東西。它的五個檔位在下面打印出來,列取的是平均檔位,所以一條介於「moderate」和「strongly」之間的筆記會落在兩者之間。presence會變成一個Noul,用於像「有沒有點名某個缺陷」這樣的是非事實。列就是那一個機率。
方法
questions <- {}
repeat for each round:
    notes  <- round 1 ? 60 dev notes across the score range
                      : the 30 worst-predicted dev notes + the 30 best,
                        each with its score, this prediction and the last
    actions <- LLM(brief, questions, notes, importance and error so far)
    answers[q] <- TypeSafe(note, all new questions of this round) for every row
    for each added q:      keep it unless its column is flat
    for each revised q:    refit; keep the change only if dev error drops
    for each dropped q:    refit; drop it only if dev error drops
    out_of_fold <- k-fold CatBoost on the columns   # judges, and picks next round's notes
沒有任何問題會在被回答之前先被篩掉。一輪裡的所有問題都在同一個請求裡發出,所以多問一個問題不會多花一個請求。一個只適用於十分之一行的問題,在提議者讀到的那 60 條筆記裡會顯得沒用,卻仍可能是這套特徵裡最有用的一列。
k 折就是把 dev 行切成 k 份,用訓練於其餘部分的模型來預測每一份。這些預測幹三件事:評判每一次修改和刪除,挑選下一輪要讀的筆記,並告訴提議者它哪些問題起了作用 —— 依據是它們自上一輪以來移動了多少。
print("every intensity question is graded on these five levels:\n")
for i, level in enumerate(INTENSITY_LEVELS):
    print(f"  {i}. {level}")
print("\nevery presence question is judged true or false against these:\n")
print(f"  true:  {PRESENCE_CRITERIA['true']}")
print(f"  false: {PRESENCE_CRITERIA['false']}")
print("\nthe brief the proposer works from:\n")
print("\n".join(PROPOSER_TASK.splitlines()[:6]) + "\n  ...")
every intensity question is graded on these five levels:
0. Not present in this note at all
1. Barely present - mentioned once, in passing
2. Present at a moderate level
3. Present strongly - the note dwells on it
4. Dominant - the note is largely about this
every presence question is judged true or false against these:
true: The note states this or clearly implies it
false: The note gives no indication of this
the brief the proposer works from:
You are designing numeric features for a gradient-boosting model that
predicts the score a wine critic gave (an integer from 80 to 100) from the tasting note alone.
The model sees nothing but the features you design.
Return up to 18 actions. Each action is one of:
...自動研究迴圈
run_loop 跑完五輪,每輪列印一個塊。新增的問題直接進入:它的答案已經取回,它的重要程度稍後會顯示它值不值得問。修改或刪除會拿走模型已經在用的一列,所以每一個都先試一試:帶上改動重新擬合,只有 dev 誤差下降才保留。重新擬合不花 API 呼叫,所以試一個改動再否決它是免費的。
run = run_loop(
    split, PROPOSER, ROUNDS, EXAMPLES, ENCODING, MIN_SPREAD, CHANGE_TOLERANCE
)
accepted, answers_for = run.accepted, run.answers_for
snapshots, history = run.snapshots, run.history
round 1: 18 add, 0 revise, 0 drop
added complexity, fruit_intensity, tannin_structure, acidity_intensity,
oak_intensity, finish_length, balance_harmony, aging_potential,
positive_superlative_language, negative_critical_language,
drinkability_easiness, body_richness, sweetness_level, texture_descriptors,
earthy_savory_notes, flaw_or_defect_mentioned,
single_vineyard_or_prestige_signal, varietal_blend_detail
-> 18 features, dev CV RMSE 1.903
round 2: 5 add, 3 revise, 3 drop
added power_concentration_language, flavor_distinctiveness, generic_fruit_language,
candied_artificial_flavor, rustic_authentic_character
reject oak_dominance was oak_intensity, would cost +0.005
revise negative_critical_language was negative_critical_language, CV 1.897 -> 1.894
revise single_vineyard_or_prestige_signalwas single_vineyard_or_prestige_signal, CV 1.894 -> 1.881
keep finish_length would cost +0.009
keep texture_descriptors would cost +0.001
keep varietal_blend_detail would cost +0.023
-> 23 features, dev CV RMSE 1.881
round 3: 7 add, 2 revise, 1 drop
added elegance_finesse_language, minerality_precision_language,
hedged_qualified_praise, underripe_green_character,
reviewer_overall_verdict_strength, unusual_or_funky_descriptor_valence,
botrytis_or_special_winemaking_signal
revise negative_critical_language was negative_critical_language, CV 1.868 -> 1.864
revise finish_quality was finish_length, CV 1.864 -> 1.861
keep candied_artificial_flavor would cost +0.014
-> 30 features, dev CV RMSE 1.861
round 4: 5 add, 2 revise, 3 drop
added excess_or_imbalance_signal, descriptive_detail_density,
critic_enthusiasm_confidence, savory_food_wine_seriousness,
note_overall_tone_positivity
revise rustic_authentic_character was rustic_authentic_character, CV 1.843 -> 1.838
reject hedged_qualified_praise was hedged_qualified_praise, would cost +0.014
keep botrytis_or_special_winemaking_signalwould cost +0.011
keep candied_artificial_flavor would cost +0.009
keep unusual_or_funky_descriptor_valencewould cost +0.010
-> 35 features, dev CV RMSE 1.838
round 5: 4 add, 2 revise, 8 drop
added structural_seriousness, youthful_tension_signal, surface_prettiness_vs_depth,
price_value_signal
reject unconventional_character_as_virtuewas rustic_authentic_character, would cost +0.010
revise flavor_distinctiveness was flavor_distinctiveness, CV 1.849 -> 1.843
keep candied_artificial_flavor would cost +0.002
keep botrytis_or_special_winemaking_signalwould cost +0.003
keep hedged_qualified_praise would cost +0.006
keep excess_or_imbalance_signal would cost +0.005
drop underripe_green_character CV 1.843 -> 1.840
keep unusual_or_funky_descriptor_valencewould cost +0.002
keep texture_descriptors would cost +0.001
keep generic_fruit_language would cost +0.000
-> 38 features, dev CV RMSE 1.840把它用到你自己的資料上
PROPOSER_TASK 是唯一提到葡萄酒的字串,而 featurize() 接受任何字串列表。改這份簡報就改變了提議提示詞,而提示詞是快取鍵的一部分,所以下一次執行會對每一輪重新呼叫 API。
請求數隨行數增長,而不是隨問題數增長:每輪每行一個請求,所以 100,000 行就是每輪 100,000 個請求。一次修改算作一個新問題,所以它要在每一行上多跑一遍。工作池要慢慢加。8 個就已經足夠在共享金鑰上撞到速率限制了。
這些問題看到了什麼
五條留出評論,在分數範圍的每個四分之一處各取一條,對比 38 個問題裡的 15 個:按重要程度排前八的 score 問題,加上排前七的 noul。
這十五行再按答案隨評論分移動的方向排序。答案隨分數上升的問題排在前面,答案隨分數下降的問題排在分隔線之後。於是從左到右、從最差的評論到最好的評論,分隔線以上的答案應該往上爬,分隔線以下的答案應該往下掉。
X, labels = design(accepted, answers_for, ENCODING)
column_importances = importances(X[DEV], SCORES[DEV])
# an encoding gives a feature more than one column, so add a feature's columns back up
feature_importances = importance_per_feature(accepted, labels, column_importances)
ranked = sorted(accepted, key=lambda f: -feature_importances[f["name"]])
score_questions = [f for f in ranked if f["kind"] == "intensity"][:8]
noul_questions = [f for f in ranked if f["kind"] == "presence"][:7]
# ordered by which way the answer moves with the score, so the map flips halfway down
heatmap_questions = sorted(
    score_questions + noul_questions,
    key=lambda f: -polarity(f, answers_for, split),
)
ordered_test = TEST[np.argsort(SCORES[TEST], kind="stable")]
positions = np.linspace(0, len(ordered_test) - 1, 5).round().astype(int)
review_rows = tuple(ordered_test[positions])

print("the five held-out heatmap columns:\n")
for i, row in enumerate(review_rows, 1):
    excerpt = " ".join(NOTES[row].split())
    print(f"  {i}. {SCORES[row]:.0f} points: {excerpt[:100]}...")

fig = reviews_heatmap(plt, heatmap_questions, answers_for, split, review_rows)
display(fig)
plt.close(fig)
the five held-out heatmap columns:
1. 80 points: Raw cherry and plum aromas are resiny and suggest wet cement. This is shearing and so jacked up with...
2. 86 points: A slight spritz brightens the mouthfeel of this lemony wine. Aromas are a bit musky, but flavors of ...
3. 89 points: This is a European-style Syrah, cofermented with 2% Viognier. It's soft and round, medium in body, a...
4. 91 points: From the producer's dry-farmed estate vineyard, and supported by small amounts of Merlot and Caberne...
5. 97 points: A thoroughly elegant, serious and yet immensely enjoyable wine that stays lively many days after ope...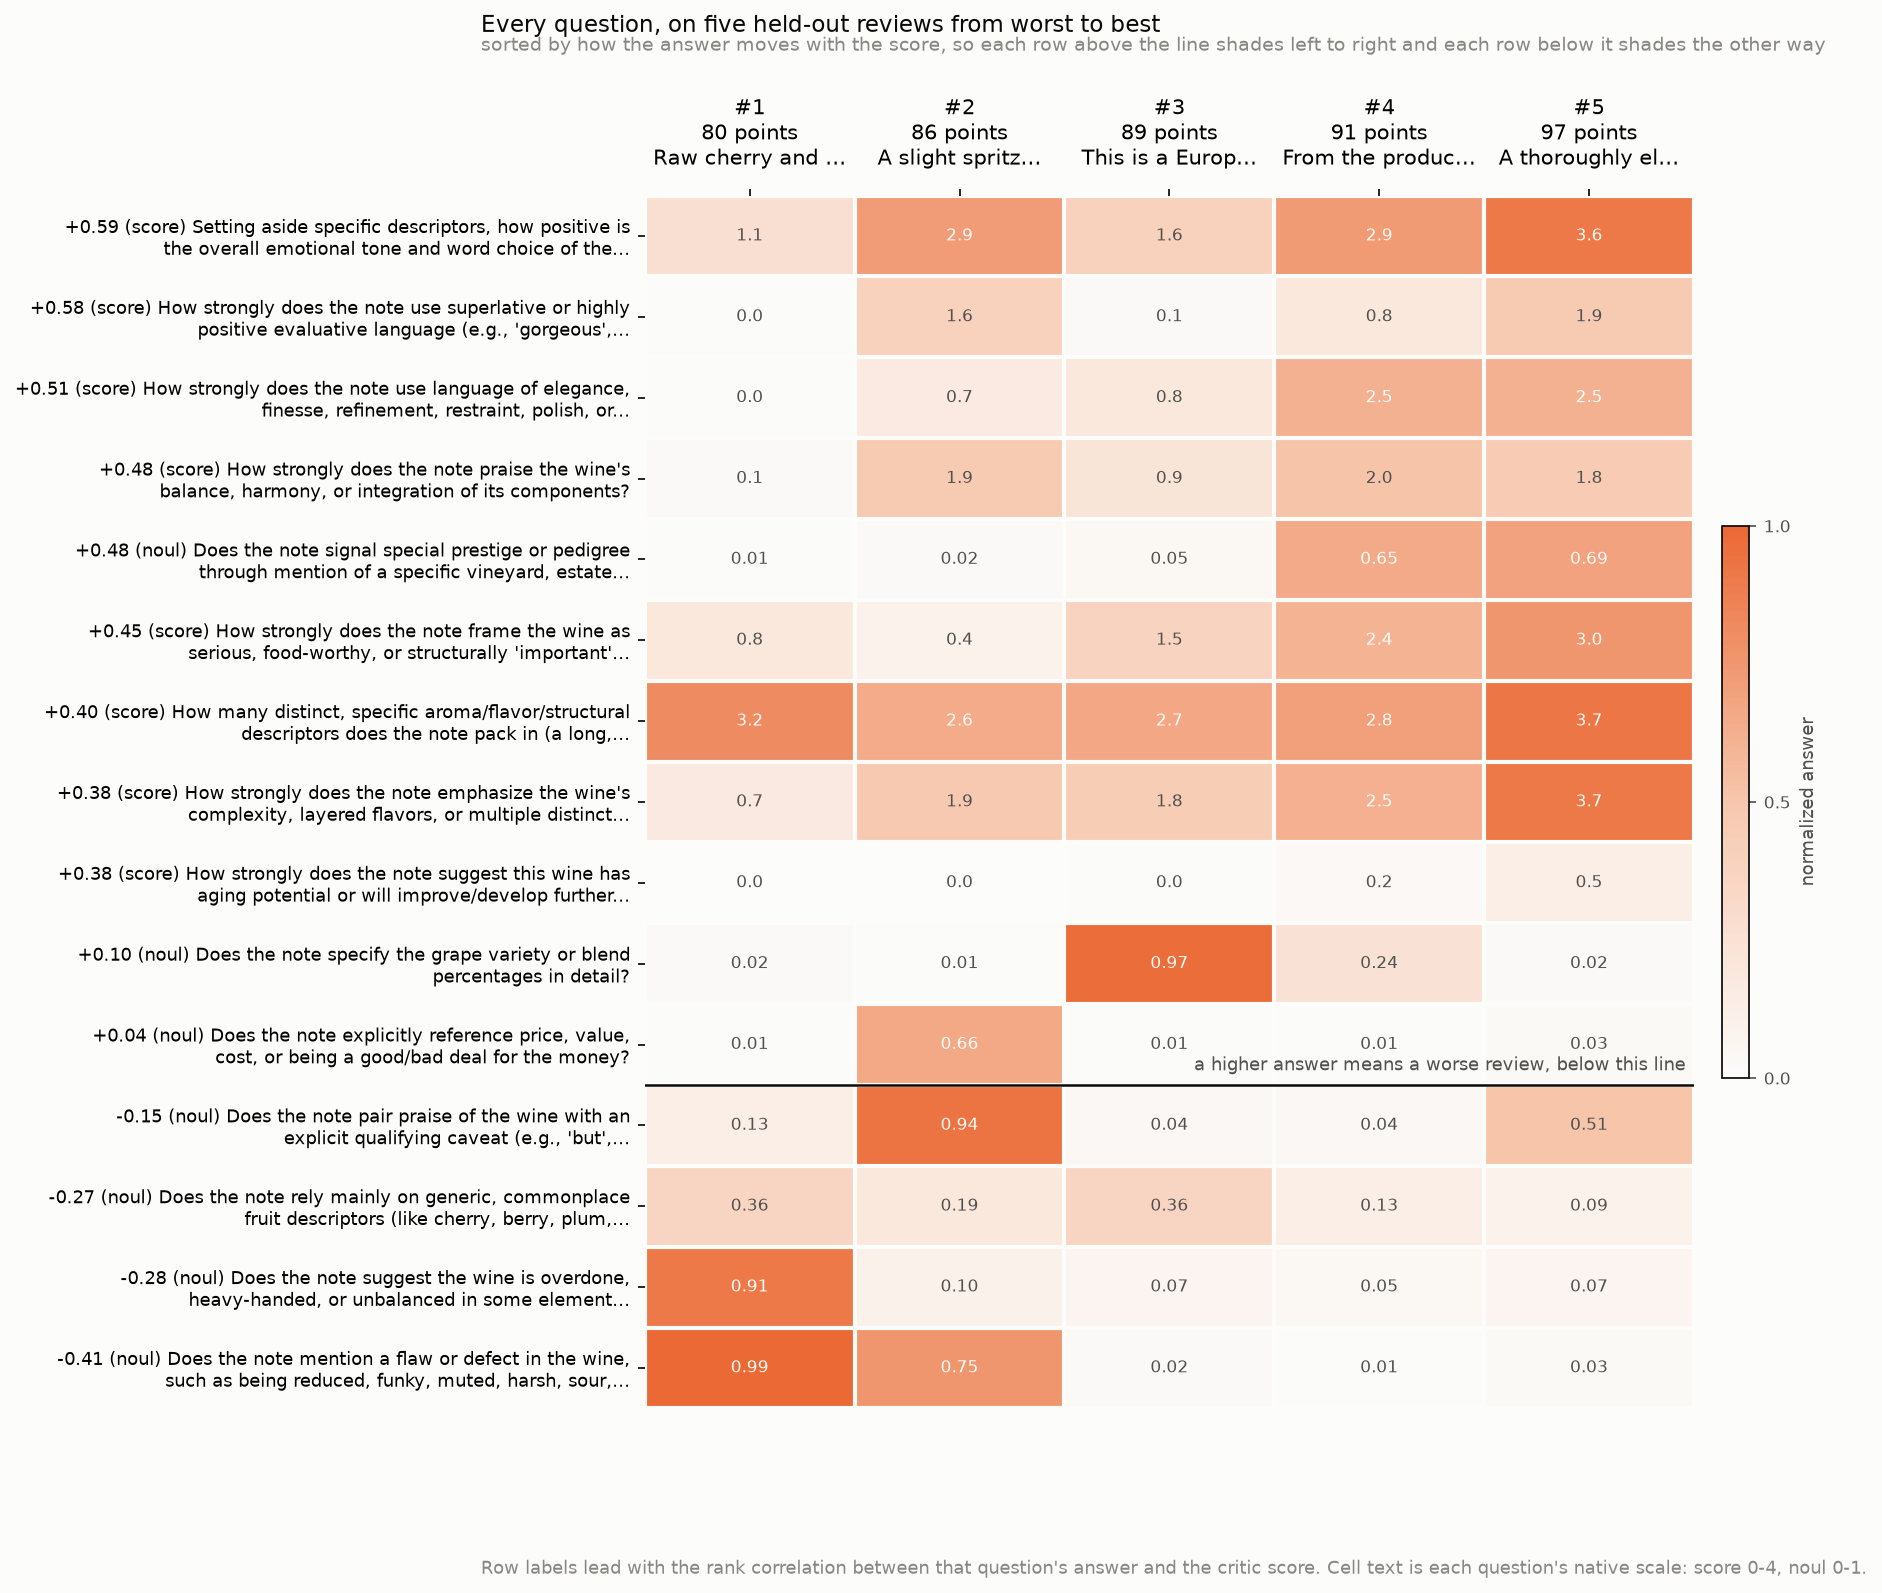
頁首那張表,這裡給出計算結果。五條臂都在同樣的 800 條留出行上評一次分,前三條跳過特徵發現。一條預測 dev 分數的均值,完全不從筆記裡讀任何東西。一條把筆記通過 text_features 處理交給同一個 CatBoost,後者把它變成詞頻。一條直接讓 TypeSafe 給出評分本身。
第三條是每行一個 Score,覆蓋十個質量檔,從「有瑕疵或令人不悅」直到「深邃」。之所以是十檔,是因為十個檔位是一個 Score 問題能接受的上限 —— 十一個會返回伺服器錯誤。檔位 0 對映到 80 分,檔位 9 對映到 100 分。這樣把檔位鋪在量表上本身還不夠,因為問題裡沒有任何東西說明這家媒體的評分實際落在量表的哪裡。所以每個答案隨後再平移一個單一的偏移量,這個偏移量在 dev 分數上測得。該偏移量列印在行標籤裡,也是這個捷徑從分數里學到的唯一東西。
Spearman 是秩相關,取 1.0 表示留出葡萄酒的排序和評論家的排序完全一致。詞頻那一行是 CatBoost 自帶的文本處理,不是一條調好的文本回歸流水線。這一切都來自一個數據集和迴圈的一次執行。
predicted = fit_predict(X, split)
text_predicted = fit_predict_text(split)

# ask TypeSafe for the score itself, one request per row
with ThreadPoolExecutor(max_workers=8) as pool:
    direct = list(pool.map(lambda note: ask_score(TYPESAFE_MODEL, note), NOTES))
asked = np.array([d["expected"] for d in direct])
shift = float(SCORES[DEV].mean() - asked[DEV].mean())  # one number, from the dev labels

# what one proposal call gets you, before any feedback: the set round 1 ended with
first_round, _ = design(snapshots[0], answers_for, ENCODING)

print(f"{'arm':<46}{'RMSE':>7}{'spearman':>10}")
for label, p in (
    ("predict the mean of the dev rows", np.full(len(TEST), SCORES[DEV].mean())),
    ("the note as word counts, same CatBoost", text_predicted),
    (f"ask for the score itself, shifted {shift:+.2f}", asked[TEST] + shift),
    (
        f"{len(snapshots[0])} questions from round 1, no loop",
        fit_predict(first_round, split),
    ),
    (f"{len(accepted)} questions after all {ROUNDS} rounds", predicted),
):
    print(f"{label:<46}{rmse(SCORES[TEST], p):>7.3f}{spearman(SCORES[TEST], p):>10.3f}")
arm RMSE spearman
predict the mean of the dev rows 3.088 -0.014
the note as word counts, same CatBoost 2.466 0.605
ask for the score itself, shifted -1.71 2.145 0.761
18 questions from round 1, no loop 1.869 0.778
38 questions after all 5 rounds 1.772 0.799自動研究的這幾輪有幫助嗎?
兩條線畫的都是每輪結束時問題集的誤差,從第一次提議開始。虛線是交叉驗證的 dev 誤差,也就是每一個接受和否決決定所依據的那個數字。實線把同樣的問題集在留出行上評分,而迴圈從不讀這些行。每個點都是這一輪結束時問題集的樣子,所以一輪哪怕只修改或刪除了一個問題,兩條線也都會動。特徵圖說明這些問題在度量什麼;誤差才告訴你第一次提議之後的幾輪有沒有讓預測變得更好。
座標軸很窄:軸上發生的一切都在五分之一個點以內,而上表裡每一個捷徑都遠遠落在軸的頂部之外。dev 線全程都在留出線之上,這是訓練規模效應。每個 dev 折訓練在 dev 行的五分之四上,而留出數字來自一個拿到了全部 1,200 行的模型。兩條線一起移動,所以迴圈用來掌舵的 dev 數字,追蹤的是它從沒見過的那個留出數字。標題下方的區間來自對留出行的重取樣,所以它說明從第 1 輪到第 5 輪的移動是否大於 800 行裡的噪聲。
curve, per_round = [], []
for features in snapshots:
    X_round, _ = design(features, answers_for, ENCODING)
    per_round.append(fit_predict(X_round, split))
    curve.append((len(features), rmse(SCORES[TEST], per_round[-1])))

# the same held-out rows resampled 2,000 times, both arms scored on each resample
gain = paired_gain(SCORES[TEST], per_round[0], per_round[-1])
print(
    f"round 1 -> round {ROUNDS} on the held-out rows: {gain[0]:+.3f} points, "
    f"95% CI [{gain[1]:+.3f}, {gain[2]:+.3f}]"
)

fig = rounds_chart(plt, curve, history, len(TEST), gain)
display(fig)
plt.close(fig)
round 1 -> round 5 on the held-out rows: -0.097 points, 95% CI [-0.147, -0.050]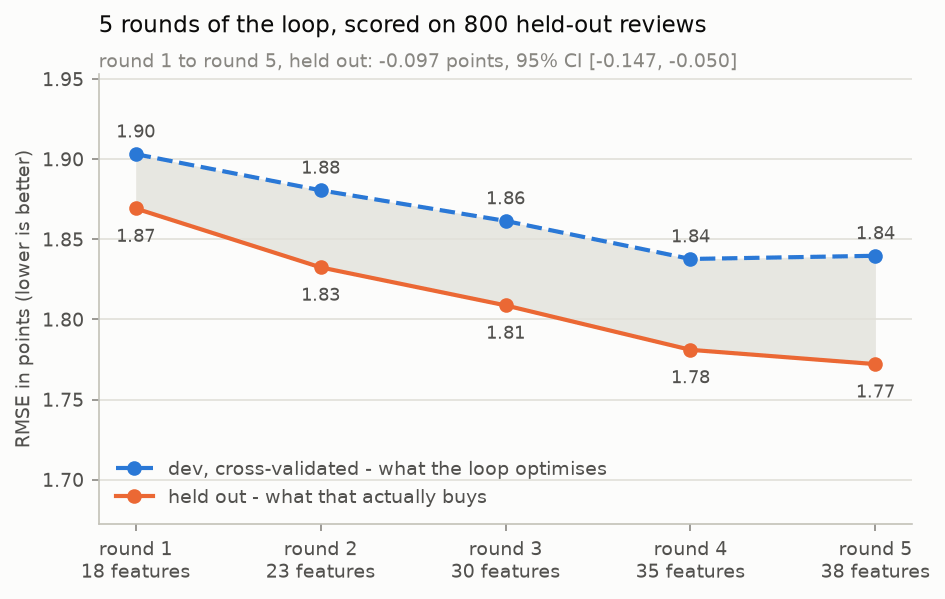
留出線下降得比 dev 線更多。第 1 輪在沒有任何反饋可依據的情況下寫出它的問題,而它之後的四輪在留出行上值 0.10 個點,95% 置信區間 [-0.147, -0.050]。
第 5 輪提出了四個新增、兩個改寫和八個刪除,給出了第一個沒有改善的 dev 數字。一條 245 字元的筆記能問的東西有限,到了第 5 輪,提議已經從「加問題」倒向了「刪問題」。
kinds = {f["name"]: f["kind"] for f in accepted}
print("feature importance share: % of total CatBoost importance across all questions")
print(f"{'feature':<38}{'asked as':<10}{'importance share':>16}")
for name, importance_share in sorted(feature_importances.items(), key=lambda p: -p[1])[
    :12
]:
    kind = "score" if kinds[name] == "intensity" else "noul"
    print(
        f"{name[:36]:<38}{kind:<10}{importance_share:>8.1f}%  "
        f"{'#' * round(importance_share)}"
    )
counts = f"{sum(1 for k in kinds.values() if k == 'intensity')} score"
counts += f", {sum(1 for k in kinds.values() if k == 'presence')} noul"
print(f"\nthe {len(accepted)} questions the loop kept: {counts}")
top = max(feature_importances, key=feature_importances.get)
print(
    f'the question behind the top row:\n  {top}: "{owner_of(top, accepted)["question"]}"'
)
feature importance share: % of total CatBoost importance across all questions
feature asked as importance share
note_overall_tone_positivity score 17.4% #################
savory_food_wine_seriousness score 8.7% #########
positive_superlative_language score 8.4% ########
single_vineyard_or_prestige_signal noul 7.2% #######
descriptive_detail_density score 5.7% ######
elegance_finesse_language score 5.0% #####
complexity score 5.0% #####
aging_potential score 5.0% #####
balance_harmony score 2.9% ###
drinkability_easiness score 2.9% ###
critic_enthusiasm_confidence score 2.7% ###
flavor_distinctiveness score 2.6% ###
the 38 questions the loop kept: 29 score, 9 noul
the question behind the top row:
note_overall_tone_positivity: "Setting aside specific descriptors, how positive is the overall emotional tone and word choice of the note taken as a whole (warm, admiring language throughout vs. flat, neutral, or lukewarm phrasing)?"importance share 是 CatBoost 的特徵重要度,做了歸一化,使全部 38 個問題加起來等於 100%。它不是行數、問題數或預測準確率的佔比。一個 score 問題佔兩列,均值和離散度各一列,所以列印百分比之前,要把它的兩列重要度加回一起。note_overall_tone_positivity 佔總量的 17.4%。第四行是一個 noul:筆記有沒有點名單一葡萄園或某種威望訊號,是一個是非事實,所以它就是這麼問的。
後續步驟
這次執行把迴圈做得很小。可以直接擴充套件的方向:
- 在花錢回答之前先篩查候選問題。把提出的問題本身當作狀態,就它問幾個 noul:它能不能從源文本里得到回答,它在自己的判定標準下是不是隻有一種含義,它適不適用於大多數行,它會不會在不同行之間變化。只發送四個都達到足夠置信度的問題。
- 修剪相關特徵。在 dev 行上度量編碼後各列之間的相關性,把近似重複的聚成一類,每一類只保留最清晰或最重要的那個問題。
- 加一些簡單基線。先單獨比較 TF-IDF、字元數和其他結構特徵,再把它們接到發現出來的列後面,度量各自貢獻了什麼。
- 混合不同的提議者家族。用 Anthropic、OpenAI、Google Gemini 和開源模型各自生成候選批次,然後在任何一個到達 TypeSafe 之前把它們合併、去重。不同家族應該比反覆呼叫同一個提議者更能拓寬搜尋。
- 比較不同的預測模型和方法。試試線性迴歸或彈性網迴歸、支援向量迴歸、隨機森林,以及在下游輸出是機率時做重校準。看看這些發現出來的特徵在 CatBoost 之外是否也有用。
- 加一個嵌入基線。嵌入把一條筆記變成幾百個數字,不附帶任何問題:
sentence-transformers/all-MiniLM-L6-v2在本地執行,OpenAI 的text-embedding-3-small是託管呼叫。把其中一個接到發現出來的列後面,度量它是否帶了這些列沒有的東西。 - 讓驗證方式匹配部署方式。預測未來時用按時間劃分,相關行必須待在一起時用分組劃分,並保留一個特徵發現和模型選擇都不碰的最終測試集。
- 在平臺期停止。當交叉驗證 RMSE 連續固定輪數不再改善,或達到問題數或請求數預算時,結束迴圈。
- 在 agent 的 Goal 模式下跑更長的搜尋。給它一個明確的指標、預算和停止規則,然後讓它提出、評估、精煉更多輪。
- 檢查穩定性。跨隨機種子或資料切片重複發現過程,保留那些一直有用的問題,而不是重要度只維繫在某一劃分上的問題。
在 playground 裡開啟
這個分享連結裝了一條品酒筆記,加上迴圈最終得到的所有問題。
playground_link = make_playground_link(
    NOTES[0], feature_questions(accepted), models=[TYPESAFE_MODEL]
)
display(
    Markdown(
        f"🔗 [Open the note + questions in the TypeSafe playground]({playground_link})"
    )
)