SDE 级联
SDE 级联
用一个两阶段的结构化数据抽取级联(mini → verify → reasoning),以一小部分成本拿到大推理模型的大部分质量。
- 概览
- 大推理模型能很好地抽取结构化数据,但慢且贵
- 小模型便宜,但会犯错
- 一个级联能以一小部分成本拿到大部分质量
- 我们用的模型及其价格($ / 每 100 万 token,输入 / 输出;标准费率,2026 年 9 月 15 日查询):
- 第 0 级(mini):
gpt-5.4-mini,$0.75 / $4.50 - 第 1 级(reasoning):
gpt-5.5,$5.00 / $30.00(约为 mini 的 7 倍) - 校验器:TypeSafe
jev-1.12,$0.042 / $0.00(输出 token 免费;见已发布的 Jev 价格)
- 第 0 级(mini):
- 算法
- 用便宜 / 小的模型抽取。
- 用 TypeSafe 原语校验:每个字段一个是非(「Noul 问题」)问题
- (例如「这个值在源文本中缺失吗?」「它是从无关文本里搬来的吗?」),各返回 P(有错)。
- 如果某个校验信号触发,就升级到昂贵的推理模型;否则保留便宜答案。
- 本 Cookbook
- 端到端走一个真实例子,然后展示跨 100 条提示词的权衡
- 注意:两个抽取级别都用文本模式的 OpenAI
- 我们不使用结构化输出、工具调用或 json 模式,因为:
- schema 遵循类的错误不是我们预期 LLM 会犯的错误(为它造合成数据很容易)
- 如果 LLM 确实没遵循 schema,它几乎总是非常困惑,所以约束解码并不能解决根本问题
- 不过我们鼓励你试试它们!
环境准备
- 安装依赖(TypeSafe 校验器客户端由 TypeSafe 的包索引提供):
pip install openai datasets jsonschema ipython 'cooksafe>=0.2.0,<0.3.0'- 然后在环境里设置
OPENAI_API_KEY和TYPESAFE_API_KEY
import json
import os
from pathlib import Path

import jsonschema
from cooksafe import JsonCache, make_playground_link
from datasets import load_dataset
from IPython.display import Markdown, display
from openai import OpenAI
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

MINI = "gpt-5.4-mini"  # rung 0: cheap + fast
REASONING = "gpt-5.5"  # rung 1: strong, run with reasoning_effort="high"
TS_MODEL = "jev-1.12"  # the TypeSafe verifier model
FIRE_T = 0.7  # escalate if any per-field P(wrong) exceeds this; also the "<== FIRES" display marker

oai = OpenAI()

ts = TypeSafeClient(api_key=os.environ["TYPESAFE_API_KEY"], timeout=30.0)
第 1 步:数据
我们选一个叫 scrapegraphai 的 HuggingFace 数据集
SCRAPEGRAPHAI_REVISION = "4bb9fba1dff9181c5acdb60a5a26fea62fa54fe9"
row = load_dataset(
    "scrapegraphai/scrapegraphai-100k",
    revision=SCRAPEGRAPHAI_REVISION,
    split="train",
)[516]
schema = json.loads(row["schema"])
prompt = row["prompt"]
content = row["content"]

print(
    f"""
PROMPT
===========
{prompt}

SCHEMA
===========
{json.dumps(schema, indent=2)}

CONTENT
===========
{content}
""".strip()
)
PROMPT
===========
Find registration open date fall semester for New York University in New York, NY for the 2024-2025 school year.
SCHEMA
===========
{
"properties": {
"registration_open_date": {
"description": "The date that registration opens for the fall semester. MUST be in the format mm/dd/yyyy. For example, for a college in the 2024-2025 school year, it might be something like 09/05/2024. Return a blank string if you are unsure.",
"title": "Registration Open Date",
"type": "string"
},
"description": {
"description": "A brief description of the registration open date. For example, 'Registration opens for the fall semester'.",
"title": "Description",
"type": "string"
}
},
"required": [
"registration_open_date",
"description"
],
"title": "RegistrationOpen",
"type": "object"
}
CONTENT
===========
Skip to content Skip to current page navigation
[ ](https://www.nyu.edu/)
Search Site
[ ](https://www.nyu.edu/)
* [ Academics](https://www.nyu.edu/academics.html)
* [ Admissions](https://www.nyu.edu/admissions.html)
* [ Research](https://www.nyu.edu/research.html)
* [ University Life](https://www.nyu.edu/life.html)
* [ About](https://www.nyu.edu/about.html)
All NYU
# Mobile Navigation
[ ](https://www.nyu.edu/)
Search Site
* [Academics](https://www.nyu.edu/academics.html)
* [Admissions](https://www.nyu.edu/admissions.html)
* [Research](https://www.nyu.edu/research.html)
* [University Life](https://www.nyu.edu/life.html)
* [About](https://www.nyu.edu/about.html)
All NYU
Info for
* Back to main menu
* Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](http://home.nyu.edu/)
Info for
* [Students](https://www.nyu.edu/students.html)
* [Faculty](https://www.nyu.edu/faculty.html)
* [Alumni](https://www.nyu.edu/alumni.html)
* [Employees](https://www.nyu.edu/employees.html)
* [Community](https://www.nyu.edu/community.html)
[Log In](https://home.nyu.edu/)
Search Site Search
# Events Calendar
Search Events
Apply Reset
* [About the Events Calendar ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar.html)
* [Events Calendar Tutorial ](https://www.nyu.edu/employees/resources-and-services/media-and-communications/digital-communications/university-events-calendar/tutorials.html)
* [Report issue or provide feedback ](https://nyu.service-now.com/sp?id=sc_cat_item&sys_id=7698dd2a98bcf4004c8c03063d84e274)
Search Filters Calendar
New York University
Equal Opportunity and Non-Discrimination at NYU - New York University is committed to maintaining an environment that encourages and fosters respect for individual values and appropriate conduct among all persons. In all University spaces--physical and digital--programming, activities, and events are carried out in accordance with applicable law as well as University policy, which includes but is not limited to its Non-Discrimination and Anti-Harassment Policy.
Unless otherwise noted, all content copyright New York University. All rights reserved.
* [Search](https://search.nyu.edu/)
* [Campus Map](https://www.nyu.edu/map.html)
* [Events](https://events.nyu.edu/)
* [Contact Us](https://www.nyu.edu/contact-us.html)
* [Give](https://www.nyu.edu/about/giving.html)
* [Copyright & Fair Use](https://www.nyu.edu/copyright-and-fair-use.html)
* [Privacy](https://www.nyu.edu/privacy.html)
* [Accessibility](https://www.nyu.edu/accessibility.html)
* [Feedback](https://www.nyu.edu/#feedback.html)
* [New York Campus](https://www.nyu.edu/)
* [Abu Dhabi Campus](https://nyuad.nyu.edu/)
* [Shanghai Campus](https://shanghai.nyu.edu/)
* [](https://facebook.com/)
* [](https://linkedin.com/)
* [](https://x.com/)
* [](https://instagram.com/)
* [](https://youtube.com/)- 这一行是一个 NYU 活动日历页面(「Fall 2024 Census Date」):
- schema 只要求两个字段:
registration_open_date和description - 抓取到的内容只有日历导航和样板文字:既没有注册日期,也没有描述
- 注意 schema 的
description字段甚至在自己的字段描述里给了一个示例值(「Registration opens for the fall semester」)
- schema 只要求两个字段:
- 所以一个规矩的抽取器应该拒绝去编造页面里没有的字段
- 我们来看看小模型会不会做对!
第 2 步:用 mini 模型抽取(文本模式)
- 注意:
gpt-5.4-mini在这个输入上非常随机——即便temperature=0,它几乎每次运行都会编造出不同的description。为了得到可复现的走查,我们硬编码了本 notebook 余下部分要讲的那一个典型编造(校验器把它标为 P(wrong) > 0.8)。真实的流水线会直接调用extract(MINI, prompt, schema, content, temperature=0)。
EXTRACT_SYSTEM = (
    "You extract structured data from documents. Return only values supported by the text. "
    "Follow any value format specified by the schema or its field descriptions."
)

# LLM and TypeSafe calls are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published results with no API spend; delete the file to re-run live.
json_cache = JsonCache(Path("json_cache.json"))

@json_cache
def extract(
    model: str,
    prompt: str,
    schema: dict,
    content: str,
    *,
    reasoning_effort: str | None = None,
    temperature: float | None = None,
) -> dict:
    user = (
        f"{prompt}\n\nReturn ONLY a JSON object matching this JSON Schema:\n"
        f"{json.dumps(schema, indent=2)}\n\nDocument:\n{content}"
    )
    kwargs = {
        "model": model,
        "messages": [
            {"role": "system", "content": EXTRACT_SYSTEM},
            {"role": "user", "content": user},
        ],
    }
    if reasoning_effort:
        kwargs["reasoning_effort"] = reasoning_effort
    if temperature is not None:
        kwargs["temperature"] = temperature
    text = oai.chat.completions.create(**kwargs).choices[0].message.content
    # The prompt asks for ONLY a JSON object, so parse the reply as-is -- no regex fishing a
    # substring out of a malformed reply. If ``json.loads`` fails, treat it as an empty extraction
    # (the record-level analog of NaN): every field reads as absent, which the verifier flags and the
    # gate escalates -- the safe direction. Schema-following errors are rare here (see the overview).
    try:
        return json.loads(text)
    except (ValueError, json.JSONDecodeError):
        return {}

# Hard-coded canonical fabrication (see note above); a real pipeline would use extract(MINI, prompt, schema, content, temperature=0).
mini_record = {
    "registration_open_date": "",
    "description": "Registration opens for the fall semester",
}
print("mini extraction:\n", json.dumps(mini_record, indent=2))

# The record is a perfect fit for the JSON Schema -- and still wrong. Schema validation is necessary
# but not sufficient: it catches structural errors, never semantic ones. That gap is the whole point.
print("\nschema-valid:", jsonschema.Draft202012Validator(schema).is_valid(mini_record))
mini extraction:
{
"registration_open_date": "",
"description": "Registration opens for the fall semester"
}
schema-valid: True- 这条记录通过了 schema 校验(上面那行打印
True),但它是错的:registration_open_date留空,这与页面一致:页面没有给出日期- 但
description是编造的:页面从未描述注册日期,于是 mini 编了一个看似合理的。它可能照搬 schema 自带的示例「Registration opens for the fall semester」,或者叙述「…was not found in the document」 - JSON-Schema 检查看不到这一点。便宜的模型会产生这种自信、满足 schema 的编造,而抓出它们是语义校验器的职责
第 3 步:用 TypeSafe 校验
- 校验器是 TypeSafe;我们为每个字段构建一个
Noul问题:- 一个狭窄的是非问题,措辞让
true= 有错(要升级)
- 一个狭窄的是非问题,措辞让
- TypeSafe 在一次 system_one 调用里为每个问题返回校准过的
noul=P(true) - 问题集:
- 一个整体性的
__overall__::judge头问题(「这条记录该升级吗?」)。我们计算并展示它,是为了把「整条记录的判断」与各字段的头问题做对比,但第 4 步的门控并不使用它——升级由逐字段的问题组驱动。 - 一个逐字段的问题组
- 非空字段拿到全部头问题
- 空字段(null / “” / [])只拿
absence_wrong这一个头问题
- (完整流水线对整体容器还有一个
spurious头问题,以及一个总体的difficultyscore;为把这次走查收敛到两个门控头问题,这里不展示)
- 一个整体性的
- TypeSafe 的方式:分解
- 注意一切都经过程序化分解,这就是 TypeSafe 的方式。
- 分解把每个提示词的智能最大化,并让算法可调、可解释。
-
# metric -> (question, NoulCriteria)
MAIN_QUESTIONS = {
    "name_desc_mismatch": (
        "Does the `extracted_field` fail to match the field at `path` or the `description` in the "
        "`field_spec`? If the `description` is empty, judge against the `path` alone.",
        NoulCriteria(
            true="the `extracted_field` does not match the field name or its `description`",
            false="the `extracted_field` matches the field name and `description`",
        ),
    ),
    "type_mismatch": (
        "Does the `extracted_field` violate the `type` declared in the `field_spec`?",
        NoulCriteria(
            true="the `extracted_field` violates the declared `type`",
            false="the `extracted_field` conforms to the declared `type`",
        ),
    ),
    "unreasonable": (
        "Is the `extracted_field` one that a reasonable person would not have extracted for this "
        "`field_spec`?",
        NoulCriteria(
            true="a reasonable person would not have extracted this value",
            false="the extraction is reasonable",
        ),
    ),
    "hallucinated": (
        "Is the `extracted_field` unsupported by, or absent from, the source text?",
        NoulCriteria(
            true="the `extracted_field` is a hallucination -- not supported by, or absent "
            "from, the source text",
            false="the `extracted_field` is supported by the source text",
        ),
    ),
    "off_target": (
        "Does the source text fail to genuinely report the thing the `field_spec` describes, so the "
        "value was pulled from incidental text?",
        NoulCriteria(
            true="the source does not genuinely provide this field -- the value was pulled "
            "from incidental text",
            false="the source genuinely reports this field",
        ),
    ),
    "incomplete": (
        "Does the `extracted_field` fail to capture a value the source supports (note whether the "
        "`field_spec` is `required`)?",
        NoulCriteria(
            true="the field is wrongly empty, null, or missing a value the source supports",
            false="the field captures the value the source supports",
        ),
    ),
    "format_violation": (
        "Does the `extracted_field` violate the format or constraints implied by the `description`, "
        "the schema `type`, and the extraction instructions (e.g. date format, units, enum membership)?",
        NoulCriteria(
            true="the `extracted_field` violates the implied format or constraints",
            false="the `extracted_field` satisfies the format and constraints",
        ),
    ),
}
ABSENCE_QUESTION = (
    "The `extracted_field` is empty, null, or an empty collection. Does the source text contain the "
    "information the `field_spec` describes, making the empty result wrong?"
)
ABSENCE_CRITERIA = NoulCriteria(
    true="a value was wrongly omitted", false="returning nothing is correct"
)

# The pipeline also asks one holistic, whole-record head: "should this be escalated?"
OVERALL_JUDGE = (
    "Is this extracted record an incorrect extraction -- some value unsupported by the source or "
    "not conforming to the schema, required information missing or wrong, or some field hallucinated -- "
    "so it should be escalated to a smarter model?"
)
OVERALL_JUDGE_CRITERIA = NoulCriteria(
    true="the record is an incorrect extraction",
    false="the record is a correct extraction",
)

def is_empty(v) -> bool:
    return v is None or (isinstance(v, (str, list, dict)) and len(v) == 0)

def field_spec(name: str) -> dict:
    """Minimal spec pulled from the schema (unwrapping anyOf/null for optional fields)."""
    p = schema["properties"][name]
    branches = p.get("anyOf") or []
    typ = p.get("type") or next(
        (b["type"] for b in branches if b.get("type") != "null"), "unknown"
    )
    return {
        "path": name,
        "type": typ,
        "description": p.get("description", ""),
        "required": name in schema.get("required", []),
    }

def build_questions(record: dict) -> dict[str, Noul]:
    """The verify question set: one holistic ``__overall__::judge`` head plus a per-field battery,
    keyed ``field::metric`` (mirrors build_verify_prompts)."""
    questions: dict[str, Noul] = {
        "__overall__::judge": Noul(
            instructions=OVERALL_JUDGE, criteria=OVERALL_JUDGE_CRITERIA
        ),
    }
    for name, value in record.items():
        spec = field_spec(name)
        if is_empty(value):
            questions[f"{name}::absence_wrong"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": ABSENCE_QUESTION,
                },
                criteria=ABSENCE_CRITERIA,
            )
            continue
        for metric, (question, criteria) in MAIN_QUESTIONS.items():
            if metric == "type_mismatch" and spec["type"] == "unknown":
                continue
            questions[f"{name}::{metric}"] = Noul(
                instructions={
                    "field_spec": spec,
                    "extracted_field": value,
                    "main_question": question,
                },
                criteria=criteria,
            )
    return questions

@json_cache
def verify(record: dict) -> dict[str, float | str]:
    """Run the whole Noul battery over a record in one TypeSafe call; return ``{field::metric: P(true)}``."""
    state = {
        "system_message": EXTRACT_SYSTEM,
        "instruction": "Extract the structured record from this document",
        "source_text": row["content"],
        "schema": schema,
        "extraction": record,
    }
    questions = build_questions(record)
    answers = ts.system_one(state=state, questions=questions, model=TS_MODEL).answers
    return {qid: ans.noul for qid, ans in answers.items()} | {
        "playground_link": make_playground_link(state, questions)
    }
对 mini 抽取结果跑完整个问题组
checks = verify(mini_record)
playground_link = checks.pop("playground_link")
display(
    Markdown(
        f"🔗 [Open this verification in the TypeSafe playground]({playground_link})"
    )
)

print(f"{'qid':<40}{'P(wrong)':>9}")
print("-" * 50)
for fld, p in sorted(checks.items(), key=lambda c: -c[-1]):
    flag = "  <== FIRES" if p > FIRE_T else ""
    print(f"{fld:<40}{p:>9.2f}{flag}")
qid P(wrong)
--------------------------------------------------
description::hallucinated 0.95 <== FIRES
description::off_target 0.85 <== FIRES
description::unreasonable 0.58
__overall__::judge 0.56
description::incomplete 0.16
registration_open_date::absence_wrong 0.14
description::format_violation 0.10
description::name_desc_mismatch 0.08
description::type_mismatch 0.02- TypeSafe 把信号集中到真正出错的字段上。
- 我们的结果是校准过的:出错的字段高,正确的字段低,看起来不对但没有明显错误的字段居中
- 这就是一个 typesafe 校验器比起一个粗糙的「整体好不好?」判断器能带给你的
第 4 步:升级门控
- 现在我们按
any_flag门控:只要有任何字段的标记超过FIRE_T(0.7,在上面设置,与第 3 步的<== FIRES标记共用)就升级 - 这是一个
max式的门控(只要任何字段触发就升级),不是均值,所以一个自信的红旗就够,而不会被平均到无声
# any_flag is a per-field gate: the holistic __overall__ head is shown above but not part of it
fired = {
    qid: p
    for qid, p in checks.items()
    if not qid.startswith("__overall__") and p > FIRE_T
}
escalate = bool(fired)

print(
    f"any_flag gate (threshold {FIRE_T}): {'ESCALATE' if escalate else 'ACCEPT cheap result'}"
)
for qid, p in sorted(fired.items(), key=lambda c: -c[1]):
    print(f"  fired: {qid}  (P={p:.2f})")
any_flag gate (threshold 0.7): ESCALATE
fired: description::hallucinated (P=0.95)
fired: description::off_target (P=0.85)第 5 步:升级到推理模型
既然有信号触发,我们就掏钱用强模型(gpt-5.5,reasoning_effort="high")
final_record = (
    extract(REASONING, prompt, schema, content, reasoning_effort="high")
    if escalate
    else mini_record
)

print("mini      :", json.dumps(mini_record))
print("reasoning :", json.dumps(final_record))
print("\nfield-level diff (mini -> final):")
for name in mini_record:
    if mini_record[name] != final_record.get(name):
        print(f"  {name}: {mini_record[name]!r}  ->  {final_record.get(name)!r}")
mini : {"registration_open_date": "", "description": "Registration opens for the fall semester"}
reasoning : {"description": "", "registration_open_date": ""}
field-level diff (mini -> final):
description: 'Registration opens for the fall semester' -> ''- 改进之处
- 推理模型丢掉了编造的
description,返回"" - 它识别出页面从未描述注册日期,于是拒绝编造一个
- 级联把一个自信、通过 schema 校验的编造,变成了一个诚实的空字段
- 而且它只在这一项上花了推理模型的钱,因为校验器让它这么做
- 推理模型丢掉了编造的
第 6 步:100 条提示词上的表现
- 这些是 TypeSafe 的内部结果,用上面那套通用方法产生:
- 同一个
extract → verify → escalate循环,gpt-5.4-mini → gpt-5.5-reasoning,对逐字段头问题做any_flag门控,在 100 条 scrapegraphai 提示词上运行 - 每一项的便宜级抽取由 TypeSafe 打分;门控阈值(「cut」)从 0 扫到 1,每个得到的配置都画在(成本,质量)空间里
- 这张图是历史快照;其中的成本没有按上面列出的当前 Jev 费率重新计算
- 同一个
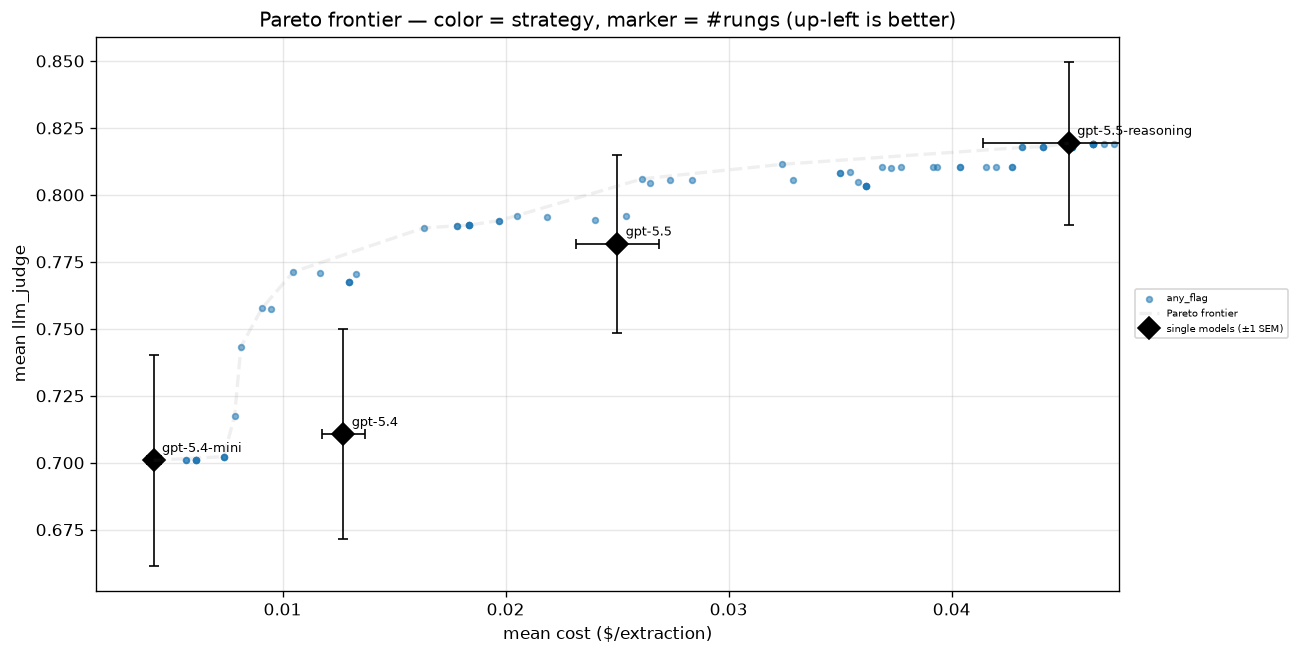
- 怎么读它:
- 黑色菱形 = 四个模型各自单独运行(成本随能力上升;最强的
gpt-5.5-reasoning位于右上角,约 0.81 质量,约 $0.10 / 次抽取) - 蓝色点 = 级联在不同门控阈值下的表现;虚线是 pareto 前沿
- 级联的前沿位于每个单独模型的左上方:扫一遍门控阈值,你就能以一小部分成本拿到最强模型的大部分质量
- 便宜那一级几乎免费地处理简单项,只有被标记的项才为推理模型付费
- 黑色菱形 = 四个模型各自单独运行(成本随能力上升;最强的
附录 A:什么构成好的校验器信号
- 级联的好坏取决于它的校验器;有用的信号与无用的信号差别在哪:
- 狭窄且有据可依。
- 针对一个字段、对照源文本的一个可检查的是非问题(例如「这个值在源文本中缺失吗?」),而不是含糊的「这次抽取好吗?」
- 含糊的问题给出糊里糊涂、未经校准的分数
- Bad = TRUE,且 criteria 明确。
- 把每个问题都设计成:升级的情形对应
true,并说明true/false的含义
- 把每个问题都设计成:升级的情形对应
- 逐字段,然后用
max聚合。- 逐字段的标记能定位错误,并保持稀疏而强
max(「任何标记触发」)保证一个自信的红旗就升级,而不是被平均到无声
- 独立且便宜。
- 一个专门的校验器(这里是 TypeSafe)来评判输出,能抓出抽取器自身的盲点
- 它必须便宜,否则就没有可省的钱了
- 有区分度 / 校准过。
- 好的信号在真实错误上高、在正确结果上低,因此单一阈值就能干净地划分「接受」与「升级」
- 正是这种区分度把 pareto 曲线推向左上方
- 狭窄且有据可依。