自洽性:choice
給稽核決策加上一個「不確定」的結果,再比較標籤一致率與自動處置的佔比。
這個 cookbook 拿一條處於邊界地帶的使用者帖子,把一份稽核量規在它上面跑 15 次,檢查每個答案在重複執行之間是否穩得住。每項檢查都是一個 Choice,所以每個答案都是固定標籤集裡的一個標籤。在稽核流水線裡,這個標籤就是路由決策:刪除還是保留、升級還是自動處理、送進威脅佇列、垃圾內容佇列還是普通佇列。一旦標籤在兩次執行之間晃動,同一條帖子就會毫無道理地路由到不同地方。
這份量規是 8 個 Choice 問題,每次執行是一次呼叫,一次答完這 8 個。每種條件重複 15 次 —— 一個條件就是「一個模型 + 一組設定」—— 然後把返回的每個標籤都畫出來。
這些條件:
- 非推理型 LLM:
claude-haiku-4-5和gpt-5.4-mini,分別在 temperature0和 API 預設值下。 - 推理型 LLM:
gpt-5.5和claude-opus-4-8,它們沒有 temperature 旋鈕。 - TypeSafe:對那 8 個
Choice問題發一次system_one呼叫,每次呼叫帶一個全新的uid欄位(一個用完即棄的唯一值),與 noul cookbook 的設定一致。
要看的是:挑中的標籤會在同一個條件內部翻轉,TypeSafe 也不例外;不同條件之間也會互相不一致。
這次執行裡,各 LLM 分佈條件下最高票標籤的重複率在 87.5% 到 100% 之間,TypeSafe 則是 90.8%。在 6 個 LLM 分佈條件裡,TypeSafe 的平均機率波動比其中 5 個都低;temperature 0 的 Haiku 波動更小。機率咬得近,依然可能讓路由發生變化:TypeSafe 在 8 個問題裡有 2 個發生了翻轉。
對於實際應用的決策,我們還要求最高機率至少達到 0.60;否則結果就是 uncertain,轉人工複核。這時 TypeSafe 的一致率升到 99.2%,74.2% 的答案給出了自動標籤。我們展示原始輸出,並對各 LLM 機率條件施加同一個閾值,讓棄權和變化都保持可見。
準備工作
pip install anthropic openai matplotlib ipython 'cooksafe>=0.2.0,<0.3.0'然後設定 TYPESAFE_API_KEY、ANTHROPIC_API_KEY 和 OPENAI_API_KEY。這次執行用的是生產 API 上的 jev-latest,取樣於 2026-09-11。
import hashlib
import json
import os
import textwrap
from collections import Counter
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from secrets import token_hex
from statistics import mean

from time import perf_counter

import anthropic
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from matplotlib.colors import ListedColormap
from openai import OpenAI
from typesafe_sdk import Choice, TypeSafeClient

matplotlib.use("Agg")  # headless render

BASE_MODELS = [
    "claude-haiku-4-5",
    "gpt-5.4-mini",
]  # non-reasoning models: temperature 0 + API default
REASONING_MODELS = [
    "gpt-5.5",
    "claude-opus-4-8",
]  # reasoning models: think first, no temperature
TYPESAFE_MODEL = "jev-latest"  # the TypeSafe model
NUM_SAMPLES = 15  # repeated post+rubric calls per condition
MIN_CHOICE_PROBABILITY = 0.60  # illustrative automatic-action threshold

LLM_PRICES = {  # $ per 1M tokens (input, output); prices + model ids as of 2026-07, see README
    "claude-haiku-4-5": (1.00, 5.00),
    "gpt-5.4-mini": (0.75, 4.50),
    "gpt-5.5": (5.00, 30.00),
    "claude-opus-4-8": (5.00, 25.00),
}
TYPESAFE_PRICE = (0.042, 0.00)  # Historical TypeSafe rate, as of 2026-08

anthropic_client = anthropic.Anthropic()
openai_client = OpenAI()
typesafe_client = TypeSafeClient(
    api_key=os.environ["TYPESAFE_API_KEY"],
    base_url="https://api.typesafe.ai",
    timeout=30.0,
)
狀態:一條處於邊界地帶的使用者帖子,以 JSON 表示
下面這條帖子是刻意造成模稜兩可的。措辭激烈且帶侮辱性,一部分衝著某個人,一部分衝著那個論點以及整個社群。它帶一個站外邀請(一個把人拉去別處的連結)、該賬號此前的一次違規記錄,以及 4 條使用者舉報,而且那些像威脅的措辭始終說得不明不白。
這裡沒有一個顯而易見的答案,而這正是重點:措辭上的一點小差別,不該讓同一條帖子在處置路徑之間隨機跳來跳去。
LLM 在提示詞裡拿到的是 json.dumps(POST)。TypeSafe 直接拿到 Python dict。
POST = {
    "post_id": "P-88213",
    "author": {
        "user_id": "u/4471",
        "account_age_days": 38,
        "prior_strikes": 1,
        "followers": 210,
    },
    "context": {
        "surface": "public reply",
        "in_reply_to": "another user defending a game patch",
        "community": "r/gamedebates",
    },
    "content": {
        "text": (
            "Are you seriously this dense? Anyone who defends that patch is a complete clown and "
            "should be embarrassed to even post here. People like you are what's ruining this "
            "community and honestly you need to be dealt with. Come say it to my face, invite's "
            "right here. Keep it up and I'll end your whole channel."
        ),
        "has_link": True,
        "link_domain": "discord.gg",
        "language": "en",
    },
    "reports": {"user_reports": 4, "report_reasons": ["harassment", "spam", "threat"]},
}
量規:8 個 Choice 問題
每個問題有一個 key、一行指令和一個固定的標籤集。同一個問題內部的標籤互斥(恰好一個適用),每個標籤還帶一句簡短描述。TypeSafe 返回一個挑中的 choice,以及一個覆蓋各標籤的 probabilities 分佈。LLM 也被要求使用同一批標籤集,這樣每一行都可比較。
QUESTIONS = {
    "category": (
        "What is the single most applicable content-policy category for this post?",
        {
            "None": "No policy violation of any kind.",
            "Harass": "Insults or demeans a person, with no threat of harm and no protected-class attack.",
            "Hate": "Attacks a person or group over a protected characteristic (race, religion, gender, ...).",
            "Violence": "Makes a credible threat of harm or incites violence against someone.",
            "Spam": "Unsolicited promotion or link spam, with no personal attack.",
            "Sexual": "Sexual or adult content.",
        },
    ),
    "primary_risk": (
        "What is the primary moderation risk that should drive triage for this post?",
        {
            "Harassment": "Personal attack or targeted abuse is the main risk.",
            "Violence": "A threat of harm or intimidation is the main risk.",
            "LinkAbuse": "External-link or off-platform coordination risk is the main risk.",
            "AccountHistory": "Prior account history or repeat behavior is the main risk.",
            "LowRisk": "No meaningful moderation risk is present.",
        },
    ),
    "target": (
        "Who or what is the content primarily directed at?",
        {
            "None": "Not directed at anyone in particular.",
            "Person": "Directed at one specific individual.",
            "Group": "Directed at a protected group or class.",
            "Platform": "Directed at the community or platform itself, not a person.",
        },
    ),
    "action": (
        "What enforcement action should be taken on this post?",
        {
            "Allow": "Leave the post up with no action.",
            "Warn": "Leave the post up but attach a warning label.",
            "Remove": "Remove the post, but do not penalize the account.",
            "Strike": "Remove the post and add a strike to the account.",
            "Escalate": "Take no automated action; hold for a human decision.",
        },
    ),
    "queue": (
        "Which single moderation queue should own this post?",
        {
            "Auto": "Auto-resolve; no human queue needed.",
            "General": "General moderation queue.",
            "Threat": "Threat / violence response queue.",
            "Spam": "Spam and platform-abuse queue.",
            "TSLead": "Trust-and-safety lead / senior queue.",
        },
    ),
    "link_handling": (
        "How should any external link or off-platform invite in the post be handled?",
        {
            "Allow": "Leave the link in place.",
            "RmLink": "Strip or disable the link but keep the post.",
            "Brigade": "Treat the link as coordinated brigading and action it as abuse.",
            "Escalate": "Send the link to a specialist to assess before acting.",
        },
    ),
    "review_path": (
        "Who should make the final call on this post?",
        {
            "Auto": "Automated action; no human review.",
            "Human": "A frontline human moderator makes the call.",
            "Senior": "A senior or specialist reviewer is required.",
            "Legal": "Route to legal or law-enforcement escalation.",
        },
    ),
    "severity": (
        "What is the overall severity of this post?",
        {
            "None": "No violation.",
            "Low": "Rude or dismissive, but essentially harmless.",
            "Medium": "Personal harassment with no clearly credible threat.",
            "High": "Harassment together with a threat that could be read as credible.",
        },
    ),
}
我們怎麼問
每次 LLM 呼叫是一個提示詞,裝著 json.dumps(POST)、全部 8 個問題,以及每一個允許的標籤。有兩種作答格式。分佈模式下,模型對每個問題返回一個 JSON 物件,給每個標籤一個機率。單選模式下,它每個問題只返回一個裸標籤,我們的分析則把全部機率質量都壓在那個標籤上。
TypeSafe 呼叫是對同一條帖子和同樣這 8 個 Choice 問題發一次 system_one 請求,每個問題返回一個分佈。
每次查詢還會帶一個全新的 uid —— 一個用完即棄、每次執行都變、而帖子和量規保持不變的唯一值。它出現在 LLM 的提示詞裡,也作為 TypeSafe 狀態裡的一個額外欄位。這套設定無法區分「對無關欄位的敏感性」和「同樣的請求本來就會產生的波動」。
每個輔助函式都返回答案、一個估算成本和往返延遲。
def argmax_label(values: list, labels: list[str]) -> str | None:
    """The label with the most probability mass, or ``None`` if any value is missing or
    non-numeric -- a partially parsed distribution never yields a confident-looking pick."""
    numeric = [_numeric_value(value) for value in values]
    if any(value is None for value in numeric):
        return None
    return labels[int(np.argmax(numeric))]

def choice_decision_with_uncertainty(values: list, labels: list[str]) -> str | None:
    """Abstain below the action threshold; retain invalid results as parse failures."""
    label = argmax_label(values, labels)
    if label is None:
        return None
    probabilities = [float(value) for value in values]
    if any(value < 0 or value > 1 for value in probabilities):
        return None
    return label if max(probabilities) >= MIN_CHOICE_PROBABILITY else "uncertain"

def choice_decision_annotation(values: list, labels: list[str]) -> str:
    """Show the application decision and top probability in a heatmap cell."""
    decision = choice_decision_with_uncertainty(values, labels)
    if decision is None:
        return ""
    probability = max(float(value) for value in values)
    probability_text = f"{probability:.2f}".removeprefix("0")
    return f"{decision} {probability_text}"

def _numeric_value(value: object) -> float | None:
    """A finite numeric value, or ``None`` if the model emitted something unusable."""
    try:
        numeric = float(value)
    except (TypeError, ValueError):
        return None
    return numeric if np.isfinite(numeric) else None

def parse_distribution(raw: object, labels: list[str]) -> list[float]:
    """Map a model's already-parsed per-question reply to per-label probabilities, in label order
    (distribution-mode answers left un-normalized).

    A single-pick reply is a single label string -> all the mass on that exact label; a
    distribution-mode reply is a dict read label by label. Anything that doesn't match a known label
    or isn't a finite number is left NaN -- we report the gap rather than massaging the reply (e.g.
    stripping an echoed description) to make it fit."""
    if isinstance(raw, str):  # single-pick mode: a single chosen label
        if raw in labels:
            return [1.0 if label == raw else 0.0 for label in labels]
        return [float("nan")] * len(labels)
    if not isinstance(raw, dict):
        return [float("nan")] * len(labels)
    return [
        value if (value := _numeric_value(raw.get(label))) is not None else float("nan")
        for label in labels
    ]

def rubric_prompt(mode: str, sample_index: int, rubric_hash: str) -> str:
    """The post + all questions (with their label sets) in one prompt; ``mode`` picks the format.

    ``mode="dist"`` asks for a probability distribution over each question's labels; the single-pick
    mode (``mode="single"``) asks for a single label per question. The uid line combines
    ``rubric_hash`` (which rubric version) with ``sample_index`` and a random token, so every repeat
    is a distinct, independent draw and two different rubrics never share a nonce."""
    lines = []
    for key, (instructions, choices) in QUESTIONS.items():
        labels = "\n".join(f"     {label}: {desc}" for label, desc in choices.items())
        lines.append(f"- {key}: {instructions}\n   labels:\n{labels}")
    exclusivity = (
        "\n\nEach question's labels are mutually exclusive: exactly one applies. If a post could "
        "arguably fit more than one, pick the single most severe / most specific label per the "
        "label descriptions."
    )
    if mode == "single":
        answer_format = (
            "\n\nFor each question, pick exactly ONE label.\nRespond with ONLY a JSON object "
            "mapping each question's key to one of that question's bare labels (the label only, "
            "not its description), with one entry per question."
        )
    else:
        answer_format = (
            "\n\nFor each question, give a probability distribution over that question's labels "
            "(values 0.00-1.00 that sum to 1).\nRespond with ONLY a JSON object mapping each "
            "question's key to an object mapping that question's bare labels (the label only, "
            "not its description) to probabilities, with one entry per question."
        )
    return (
        f"uid: {rubric_hash}:{sample_index}:{token_hex(4)}\n\n"
        f"Document (a reported user post):\n{json.dumps(POST, indent=2)}\n\nQuestions:\n"
        + "\n".join(lines)
        + exclusivity
        + answer_format
    )

def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
    return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]

def _call_llm(model: str, prompt: str, temperature: float | None):
    """One LLM call -> (text, cost_usd, latency_s), routed by model name."""
    reasoning = model in REASONING_MODELS
    started = perf_counter()
    if model.startswith("claude"):
        kwargs = {
            "model": model,
            "max_tokens": 4096,
            "messages": [{"role": "user", "content": prompt}],
        }
        if reasoning:
            kwargs["thinking"] = {"type": "adaptive"}
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = anthropic_client.messages.create(**kwargs)
        text = next((b.text for b in response.content if b.type == "text"), "")
        usage = (response.usage.input_tokens, response.usage.output_tokens)
    else:
        kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
        if reasoning:
            kwargs["reasoning_effort"] = "high"
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = openai_client.chat.completions.create(**kwargs)
        text = response.choices[0].message.content
        usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
    return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started

# All samples (LLM and TypeSafe) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering is instant and reproduces the published numbers with no API spend. ``sample_index``
# seeds the uid buster and is part of the cache key, so each of the NUM_SAMPLES repeats is its own
# entry and its own independent draw, not one draw replayed. Delete ``json_cache.json`` to re-sample
# everything live.
json_cache = JsonCache(Path("json_cache.json"))

def _rubric_fingerprint() -> str:
    """Short digest of everything that shapes the prompt/rubric: the state and every question's
    text and label set. Passed into the cached calls below so that editing the post or any question
    changes the cache key and forces a fresh sample, instead of silently serving a stale answer that
    was generated for the old wording."""
    payload = json.dumps([POST, QUESTIONS], sort_keys=True, default=str)
    return hashlib.sha256(payload.encode()).hexdigest()[:12]

RUBRIC_HASH = _rubric_fingerprint()

@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
    """Return distributions, token usage, latency, and model metadata for one call.

    ``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
    Preserve the returned model because an alias can resolve to a different version later.
    """
    questions = {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    }
    started = perf_counter()
    response = typesafe_client.system_one(
        model=model,
        state={"uid": f"{rubric_hash}:{sample_index}:{token_hex(4)}", "post": POST},
        questions=questions,
    )
    distributions = {}
    for key, (_instructions, choices) in QUESTIONS.items():
        probabilities = dict(response.answers[key].probabilities)
        distributions[key] = [
            probabilities.get(label, float("nan")) for label in choices
        ]
    return (
        distributions,
        response.usage.input_tokens,
        response.usage.output_tokens,
        perf_counter() - started,
        {"requested_model": model, "response_model": response.model},
    )

@json_cache
def ask_llm_rubric(
    model: str,
    mode: str,
    temperature: float | None,
    sample_index: int,
    rubric_hash: str,
):
    """One LLM rubric query -> (per-question label distributions keyed by question key, cost_usd,
    latency_s); NaNs if the reply doesn't parse.

    ``mode="dist"`` parses 8 label distributions; the single-pick mode (``mode="single"``) parses 8
    single labels and puts all the mass on each. ``rubric_hash`` goes into the prompt's uid nonce
    (and so the cache key), so an edited state/rubric busts the cache instead of serving a stale
    answer."""
    prompt = rubric_prompt(mode, sample_index, rubric_hash)
    text, cost, latency = _call_llm(model, prompt, temperature)
    # Peel a single ```json ... ``` fence (claude-haiku-4-5 sometimes adds one despite "ONLY a JSON
    # object").
    stripped = text.strip()
    if stripped.startswith("```"):
        stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
        if stripped.rstrip().endswith("```"):
            stripped = stripped.rstrip()[: -len("```")]
    try:
        raw = json.loads(stripped)
    except (ValueError, json.JSONDecodeError):
        raw = {}
    if not isinstance(raw, dict):
        raw = {}
    distributions = {
        key: parse_distribution(raw.get(key), list(choices))
        for key, (_instructions, choices) in QUESTIONS.items()
    }
    return distributions, cost, latency
實驗條件
實驗網格
| 模型組 | 模型 | 分佈(t=0) | 分佈(預設) | 單選(t=0) |
|---|---|---|---|---|
| 非推理型模型 | claude-haiku-4-5 |
✓ | ✓ | ✓ |
| 非推理型模型 | gpt-5.4-mini |
✓ | ✓ | ✓ |
| 推理型模型 | gpt-5.5 |
— | ✓ | — |
| 推理型模型 | claude-opus-4-8 |
— | ✓ | — |
| TypeSafe | jev-latest(typesafe_choice) |
— | ✓ | — |
✓表示該條件做了 15 次重複;—表示這個組合沒有測。- 「預設」那一列不傳 temperature 參數:非推理型模型用 API 預設值,推理型模型和 TypeSafe 則在沒有任何 temperature 設定的情況下執行。
- 單選條件每個問題返回一個標籤。
- 為了可重複性,大家常建議把 temperature 設為
0,所以這裡拿它和 API 預設值做個對比。
每個條件我們抽 NUM_SAMPLES = 15 次重複。每次重複有自己的快取鍵,算作一次獨立的抽取;快取(json_cache.json)隨 cookbook 一起提供,所以重新渲染會複用它,不花任何 API 呼叫。刪掉快取就能重新即時取樣。
CONDITIONS = []
for (
    model
) in BASE_MODELS:  # non-reasoning models: dist at t=0 / default, then a single-pick variant
    for temp_value, temp_label in ((0, "0"), (None, "default")):
        CONDITIONS.append(
            {
                "label": f"{model} t={temp_label}",
                "model": model,
                "temp": temp_value,
                "mode": "dist",
            }
        )
    CONDITIONS.append(
        {
            "label": f"{model} single-pick t=0",
            "model": model,
            "temp": 0,
            "mode": "single",
        }
    )
CONDITIONS += [  # reasoning models: one distribution condition each
    {
        "label": f"{model}-reasoning",
        "model": model,
        "temp": None,
        "mode": "dist",
    }
    for model in REASONING_MODELS
]
LABELS = [condition["label"] for condition in CONDITIONS]
TYPESAFE_LABEL = "typesafe_choice"
ALL_LABELS = [*LABELS, TYPESAFE_LABEL]

runs: dict[
    str, list
] = {}  # label -> NUM_SAMPLES samples of {question key: distribution}
stats: dict[str, list] = {}  # label -> NUM_SAMPLES (cost_usd, latency_s) pairs
with ThreadPoolExecutor(max_workers=16) as pool:
    futures = {
        condition["label"]: [
            pool.submit(
                ask_llm_rubric,
                condition["model"],
                condition["mode"],
                condition["temp"],
                sample_index,
                RUBRIC_HASH,
            )
            for sample_index in range(NUM_SAMPLES)
        ]
        for condition in CONDITIONS
    }
    for label, sample_futures in futures.items():
        results = [future.result() for future in sample_futures]
        runs[label] = [result[0] for result in results]
        stats[label] = [(result[1], result[2]) for result in results]

# TypeSafe samples are drawn sequentially, after the LLM pool has closed, so each call's latency is a
# clean round trip rather than one measured under the 16-way LLM thread contention.
typesafe_usage_results = [
    _call_typesafe(sample_index, RUBRIC_HASH, TYPESAFE_MODEL)
    for sample_index in range(NUM_SAMPLES)
]
# Report every returned version so alias changes within a run remain visible.
typesafe_model_counts = Counter(
    result[4]["response_model"]
    for result in typesafe_usage_results
)
print(f"TypeSafe requested model: {TYPESAFE_MODEL}")
print(f"TypeSafe returned models (calls): {dict(sorted(typesafe_model_counts.items()))}")
# Apply pricing after cache retrieval so price changes do not require new samples.
typesafe_results = [
    (distributions, _cost(TYPESAFE_PRICE, input_tokens, output_tokens), latency)
    for distributions, input_tokens, output_tokens, latency, _metadata in typesafe_usage_results
]
typesafe_runs = [result[0] for result in typesafe_results]
stats[TYPESAFE_LABEL] = [(result[1], result[2]) for result in typesafe_results]
TypeSafe requested model: jev-latest
TypeSafe returned models (calls): {'jev-1.13.0': 15}成本 + 速度(每次量規查詢)
下面的成本用的是準備工作裡那套當時的價格假設,TypeSafe 用的是 speed_latest 費率。它們不是經過核實的 jev-latest 價格,也不是當前的賬單金額。
一行就是一次完整的 8 問題量規呼叫。time/call 和 cost/call 是 15 次呼叫的平均,vs ts_choice 兩列則除以 TypeSafe 的數值。各 LLM 跑在一個 16 路併發池裡。
typesafe_cost = mean([cost for cost, _latency in stats["typesafe_choice"]])
typesafe_latency = mean([latency for _cost, latency in stats["typesafe_choice"]])
name_w = max(len(name) for name in ALL_LABELS) + 2  # fit the longest condition label
# Stack comparison headers so the relative speed and cost columns can stay narrow.
print(
    f"{'':<{name_w + 31}}{'speed vs':>11}{'cost vs':>11}\n"
    f"{'condition':<{name_w}}{'calls':>7}{'time/call':>11}{'cost/call':>13}"
    f"{'ts_choice':>11}{'ts_choice':>11}"
)
for name in ALL_LABELS:
    costs, latencies = zip(*stats[name])
    cost = mean(costs)
    latency = mean(latencies)
    print(
        f"{name:<{name_w}}{len(costs):>7}{latency * 1000:>9.0f}ms"
        f"{'$' + format(cost, '.6f'):>13}"
        f"{format(latency / typesafe_latency, '.1f') + 'x':>11}"
        f"{format(cost / typesafe_cost, '.1f') + 'x':>11}"
    )
speed vs cost vs
condition calls time/call cost/call ts_choice ts_choice
claude-haiku-4-5 t=0 15 3853ms $0.003498 33.8x 76.1x
claude-haiku-4-5 t=default 15 3860ms $0.003494 33.8x 76.0x
claude-haiku-4-5 single-pick t=0 15 992ms $0.001527 8.7x 33.2x
gpt-5.4-mini t=0 15 2293ms $0.002299 20.1x 50.0x
gpt-5.4-mini t=default 15 1986ms $0.002164 17.4x 47.1x
gpt-5.4-mini single-pick t=0 15 826ms $0.000936 7.2x 20.3x
gpt-5.5-reasoning 15 12978ms $0.041255 113.7x 897.4x
claude-opus-4-8-reasoning 15 10376ms $0.028375 90.9x 617.2x
typesafe_choice 15 114ms $0.000046 1.0x 1.0x這次執行裡,typesafe_choice 的平均往返延遲是 114ms。在上面的併發設定下,各 LLM 條件每次呼叫的耗時從 826ms 到 13.0 秒不等。
圖:把每次取樣的決策畫成熱力圖
怎麼讀這張圖:
- 外層行分組:問題。
- 內層行:條件。
- 列:一次完整的量規呼叫。
- 單元格文字:應用層決策,加上最高標籤上的機率。
- 單元格顏色:該標籤在這個問題裡的位置,所以一整行顏色始終相同,就意味著每次都做出同樣的決策。
- 灰色
uncertain:最高機率低於0.60,這個案例轉人工複核。 - 斜線填充的
n/a:返回內容沒能解析成可用的標籤(一次解析失敗)。 - 空行只是分隔用的。
單選條件保留它們返回的標籤:它們不提供不確定性估計。
GAP = 1  # blank spacer row(s) between question blocks
HEAT_LABELS = ALL_LABELS
rows_per_block = len(HEAT_LABELS)  # rows per question block
pooled_runs = {
    **runs,
    TYPESAFE_LABEL: typesafe_runs,
}

row_index_values, row_text, row_labels, blocks = [], [], [], []
for question_index, (question_key, (question_text, choices)) in enumerate(
    QUESTIONS.items()
):
    labels = list(choices)
    if question_index:  # blank spacer rows (NaN -> rendered white) separate the blocks
        row_index_values.extend([np.nan] * NUM_SAMPLES for _ in range(GAP))
        row_text.extend([[""] * NUM_SAMPLES for _ in range(GAP)])
        row_labels.extend([""] * GAP)
    blocks.append((len(row_index_values), question_key, question_text))
    for label in HEAT_LABELS:
        values_by_sample = [
            pooled_runs[label][sample][question_key] for sample in range(NUM_SAMPLES)
        ]
        picks = [
            choice_decision_with_uncertainty(values, labels) for values in values_by_sample
        ]
        row_index_values.append(
            [
                10 if pick == "uncertain" else labels.index(pick) if pick in labels else np.nan
                for pick in picks
            ]
        )
        row_text.append(
            [choice_decision_annotation(values, labels) for values in values_by_sample]
        )
        row_labels.append(label)

heatmap_matrix = np.array(row_index_values, dtype=float)
# Reserve gray for abstentions while concrete-label colors remain local to each question.
cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
cmap.set_bad(
    "white"
)  # NaN cells (spacer rows AND unparseable replies) render white here...

fig, ax = plt.subplots(figsize=(15, 0.33 * len(row_index_values) + 1))
ax.imshow(heatmap_matrix, cmap=cmap, vmin=0, vmax=10, aspect="auto")
for row in range(heatmap_matrix.shape[0]):
    is_spacer_row = row_labels[row] == ""  # blank separator between question blocks
    for col in range(heatmap_matrix.shape[1]):
        label_text = row_text[row][col]
        if label_text:
            ax.text(
                col,
                row,
                label_text,
                ha="center",
                va="center",
                fontsize=5.7,
                family="monospace",
                color="black",
            )
        elif (
            not is_spacer_row
        ):  # ...but an unparseable reply gets a hatched "n/a", not blank white
            ax.add_patch(
                plt.Rectangle(
                    (col - 0.5, row - 0.5),
                    1,
                    1,
                    facecolor="#e8e8e8",
                    edgecolor="#b0b0b0",
                    hatch="////",
                    linewidth=0,
                )
            )
            ax.text(
                col,
                row,
                "n/a",
                ha="center",
                va="center",
                fontsize=5,
                family="monospace",
                color="#b30000",
            )

ax.set_xticks(range(NUM_SAMPLES))
ax.set_xticklabels(range(1, NUM_SAMPLES + 1), fontsize=7)
ax.set_xlabel("rubric query")
ax.set_yticks(range(len(row_labels)))
ax.set_yticklabels(row_labels, fontsize=7)
ax.tick_params(length=0)
for edge in ("top", "right", "left", "bottom"):
    ax.spines[edge].set_visible(False)

# outer level of the multi-index: the question key, printed once per block and centered, with the
# question text wrapped right under it
y_axis_transform = ax.get_yaxis_transform()
for start, question_key, question_text in blocks:
    center = start + (rows_per_block - 1) / 2
    ax.text(
        -0.2,
        center - 0.7,
        question_key,
        transform=y_axis_transform,
        ha="right",
        va="center",
        fontsize=8,
        fontweight="bold",
    )
    ax.text(
        -0.2,
        center + 0.1,
        textwrap.fill(question_text, 34),
        transform=y_axis_transform,
        ha="right",
        va="top",
        fontsize=6,
        style="italic",
        color="gray",
    )

ax.set_title(
    f"Every sample's decision + top probability; gray = uncertain (< {MIN_CHOICE_PROBABILITY:.2f})\n"
    f"(rows = question x condition, {NUM_SAMPLES} columns)",
    pad=12,
)
fig.tight_layout()
display(fig)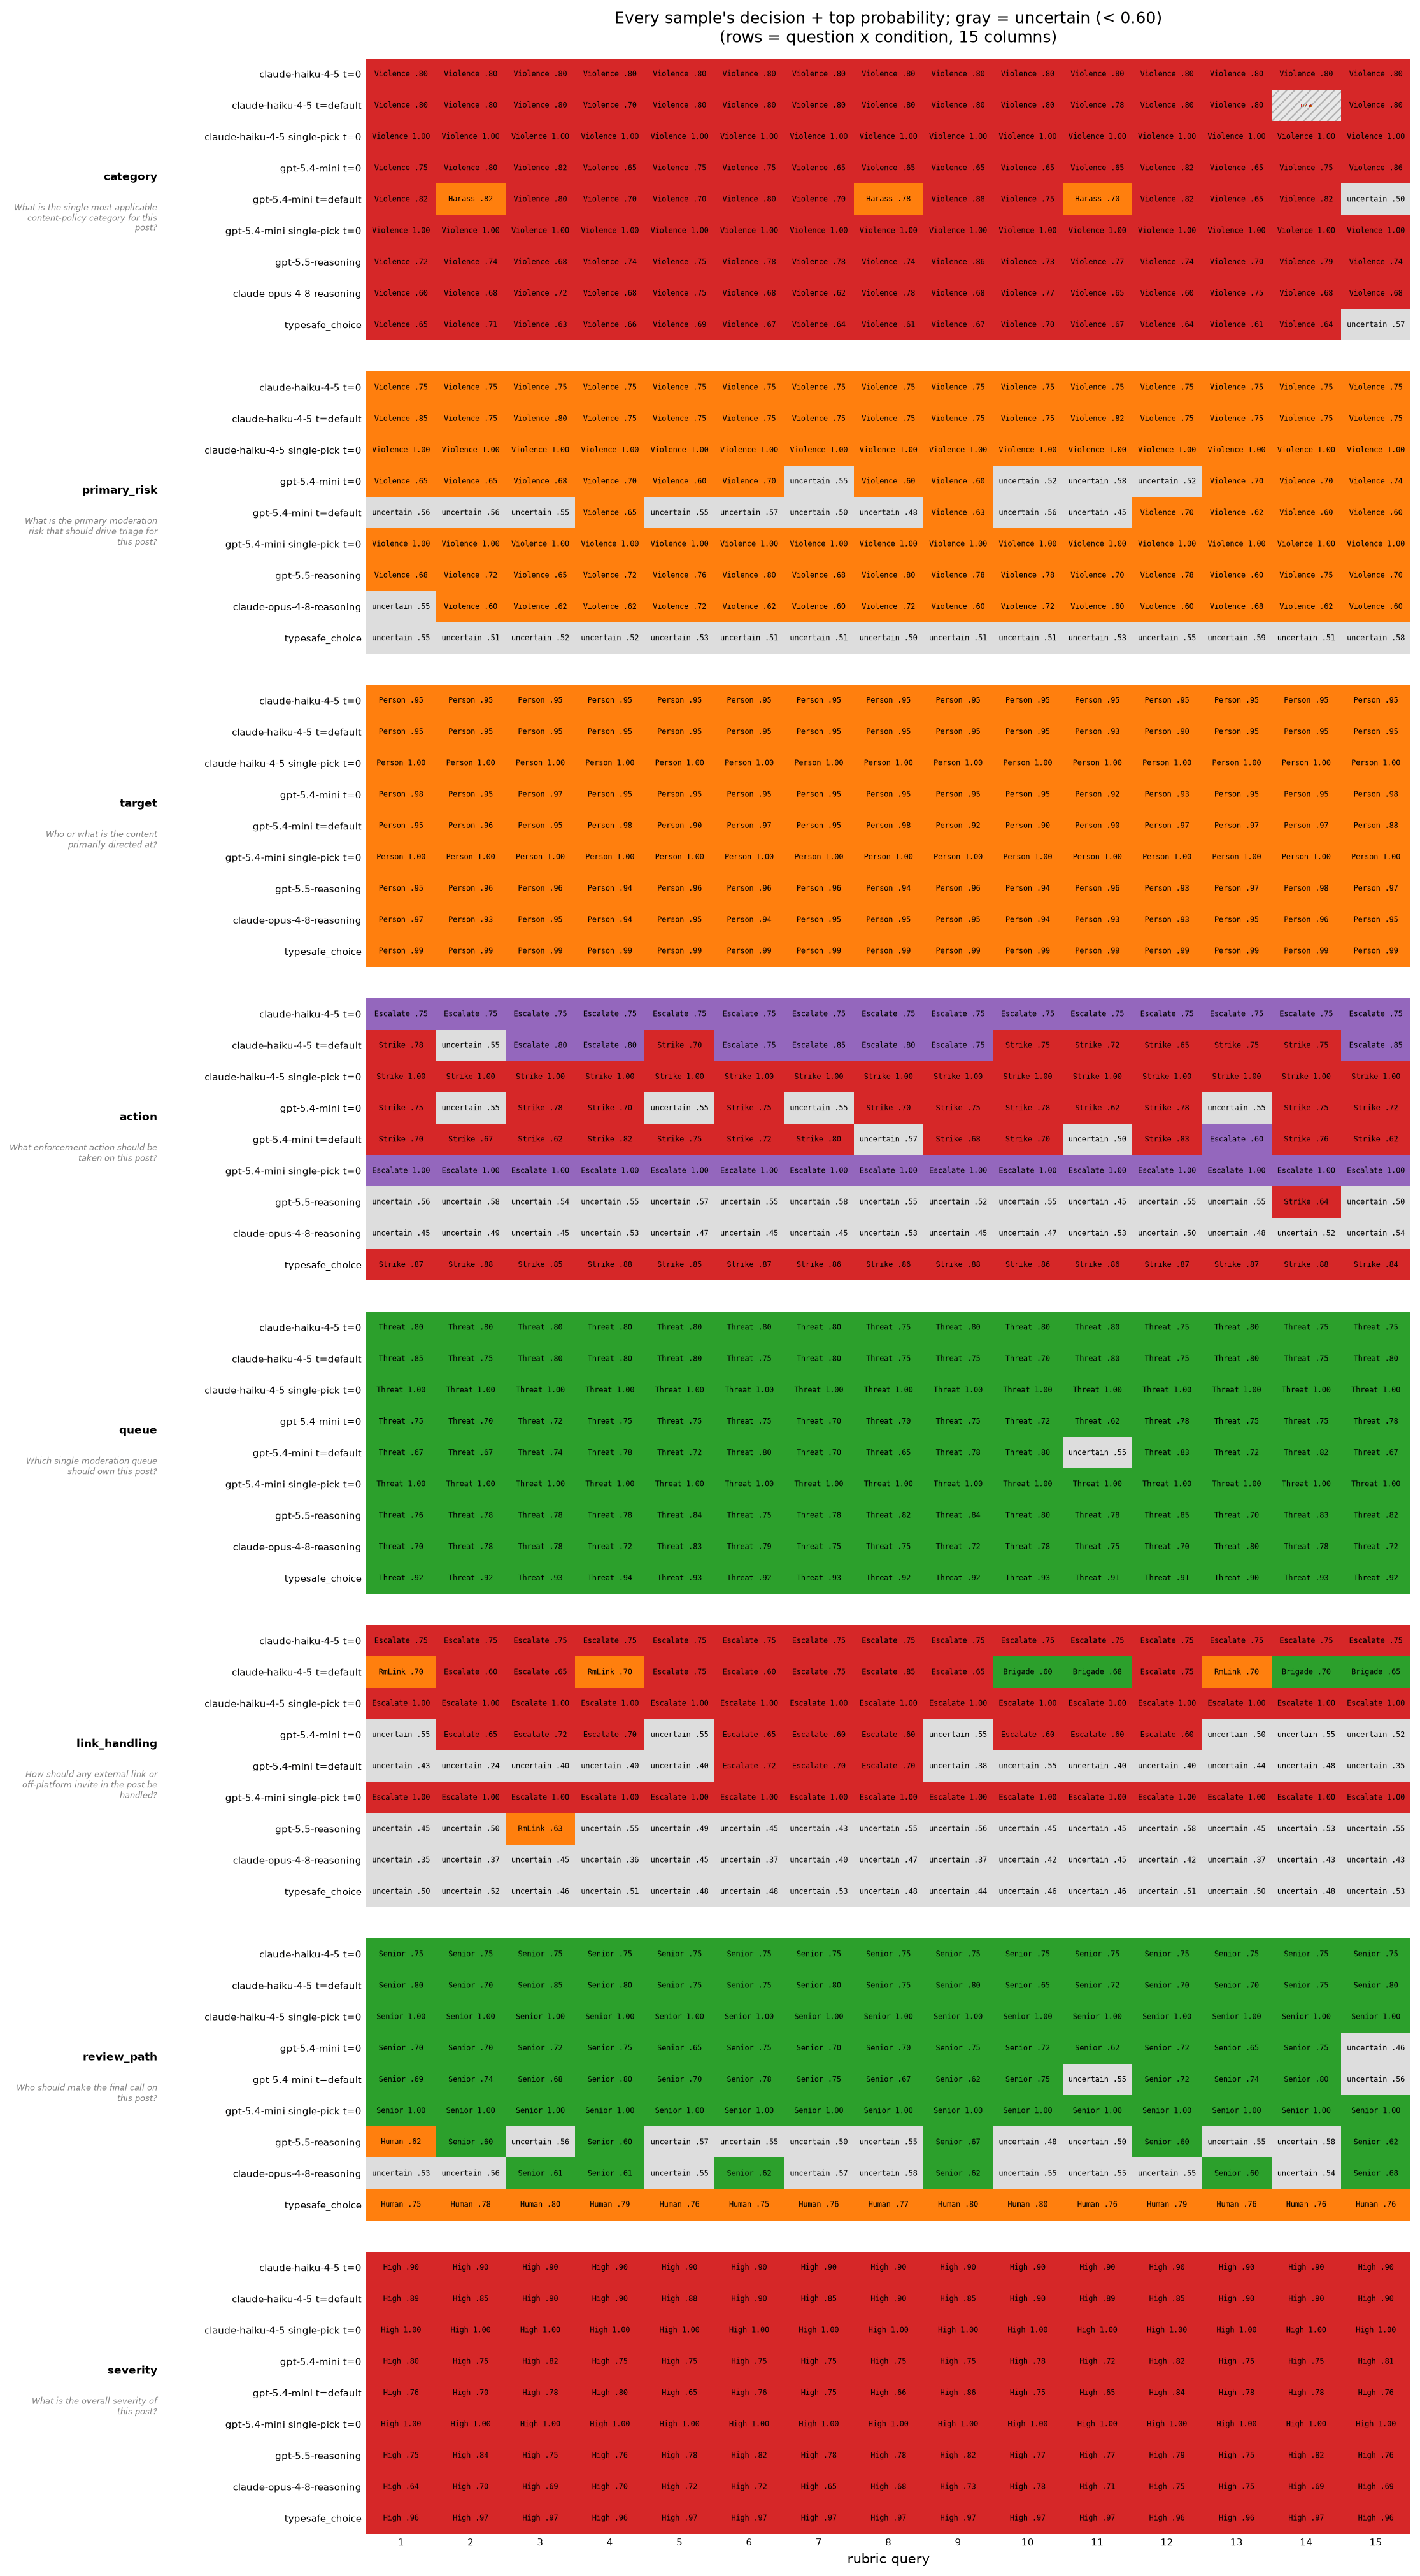
更清晰的問題很穩:target 一致讀作 Person,severity 一致讀作 High。邊界上的那些則在不同條件間分裂:category、primary_risk、action、review_path 和 link_handling。有些條件在自己那 15 次重複內部也會翻轉。在啟用棄權之前,TypeSafe 在 primary_risk(Harassment 11 次,Violence 4 次)和 link_handling(RmLink 8 次,Brigade 7 次)上會改變最高標籤。現在這兩行整行都顯示 uncertain,因為它們的最高機率低於 0.60。
機率標準差
這裡看的是完整的機率向量,不只是挑中的那個標籤。對每個條件,我們把每個問題的全部 15 個分佈收集起來,計算每個標籤的機率在多次重複之間的標準差(也就是它每次執行移動多少),再把這些標準差在所有標籤和所有問題上求平均。我們還報告最大的單個標籤標準差,並單獨統計解析失敗。
這張表把每個輸出機率的 LLM 條件都拿來和 TypeSafe 比。單選那幾行被略去,因為它們給出的是硬標籤,而不是機率分佈。
def probability_std_stats(samples: list) -> tuple[float, float, float]:
    """Mean label std dev, max label std dev, parse-failure rate."""
    label_stds = []
    parse_failures = []
    for question_key in QUESTIONS:
        arr = np.array(
            [sample[question_key] for sample in samples],
            dtype=float,
        )
        parse_failures.extend(np.isnan(arr).any(axis=1).tolist())
        label_stds.extend(np.nanstd(arr, axis=0).tolist())
    return (
        float(np.nanmean(label_stds)),
        float(np.nanmax(label_stds)),
        float(np.mean(parse_failures)),
    )

PROBABILITY_OUTPUT_LABELS = [
    condition["label"] for condition in CONDITIONS if condition["mode"] == "dist"
] + [TYPESAFE_LABEL]
probability_std_by_label = {
    label: probability_std_stats(pooled_runs[label])
    for label in PROBABILITY_OUTPUT_LABELS
}
typesafe_mean_std = probability_std_by_label[TYPESAFE_LABEL][0]

print(
    f"{'condition':<{name_w}}{'mean prob std':>15}{'max prob std':>14}"
    f"{'parse fail':>12}{'x TypeSafe':>12}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    mean_std, max_std, parse_failure_rate = probability_std_by_label[label]
    relative_std = mean_std / typesafe_mean_std
    print(
        f"{label:<{name_w}}{mean_std:>15.4f}{max_std:>14.4f}"
        f"{parse_failure_rate:>11.0%}{relative_std:>12.2f}x"
    )
condition mean prob std max prob std parse fail x TypeSafe
claude-haiku-4-5 t=0 0.0012 0.0221 0% 0.12x
claude-haiku-4-5 t=default 0.0516 0.3150 1% 5.29x
gpt-5.4-mini t=0 0.0312 0.0905 0% 3.20x
gpt-5.4-mini t=default 0.0543 0.2303 0% 5.56x
gpt-5.5-reasoning 0.0305 0.1047 0% 3.12x
claude-opus-4-8-reasoning 0.0245 0.0693 0% 2.52x
typesafe_choice 0.0098 0.0515 0% 1.00x這次執行裡,TypeSafe 的平均機率標準差是 0.0098,單個標籤的最大標準差是 0.0515。temperature 0 的 Haiku 平均標準差更低,為 0.0012。其餘 5 個 LLM 機率條件在 0.0245 到 0.0543 之間,約為 TypeSafe 均值的 2.5x 到 5.6x。當兩個標籤咬得很近時,微小的變化依然可能讓最高標籤換人。
圖:把「不確定」算作一種結果後的決策一致率
當最高機率低於 0.60 時返回 uncertain。對每個輸出機率的條件和每個問題,統計最常見的應用層決策(把 uncertain 也算進去),再除以全部 15 次抽取。解析失敗計入一致率的分母。每根柱子是在全部 8 個問題上對該得分取平均,一致率最高的排在最前。
單選 LLM 條件被排除在外,因為它們不提供不確定性估計。
# Compute policy decisions and agreement once for both this chart and the comparison table.
decisions_by_condition = {}
policy_agreement_by_condition = {}
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = [
        [
            choice_decision_with_uncertainty(sample[key], list(choices))
            for sample in pooled_runs[label]
        ]
        for key, (_instructions, choices) in QUESTIONS.items()
    ]
    decisions_by_condition[label] = decisions
    shares = [
        max(Counter(value for value in row if value is not None).values(), default=0)
        / NUM_SAMPLES
        for row in decisions
    ]
    policy_agreement_by_condition[label] = mean(shares)

# Sort by the measured agreement, keeping TypeSafe's color independent of its rank.
bar_labels = sorted(
    PROBABILITY_OUTPUT_LABELS, key=policy_agreement_by_condition.__getitem__, reverse=True
)
rates = [policy_agreement_by_condition[label] for label in bar_labels]

fig_bar, bar_ax = plt.subplots(figsize=(7, 0.45 * len(bar_labels) + 1))
positions = range(len(bar_labels))
bar_ax.barh(
    list(positions),
    rates,
    color=["#2b8cbe" if label == TYPESAFE_LABEL else "#fe9929" for label in bar_labels],
    alpha=0.85,
)
for label, position, rate in zip(bar_labels, positions, rates):
    marker = "*" if label == "claude-haiku-4-5 t=0" else ""
    bar_ax.text(
        rate + 0.01, position, f"{rate:.1%}{marker}", va="center", fontsize=8, color="gray"
    )
bar_ax.set_yticks(list(positions))
bar_ax.set_yticklabels(bar_labels, fontsize=8)
bar_ax.invert_yaxis()  # first condition on top
bar_ax.set_xlim(0, 1.08)
bar_ax.set_xticks(np.linspace(0, 1, 6))
bar_ax.set_xlabel("decision agreement across 15 re-runs (mean over 8 questions)")
for edge in ("top", "right", "left"):
    bar_ax.spines[edge].set_visible(False)
bar_ax.tick_params(length=0)
fig_bar.suptitle("Decision agreement including uncertain outcomes", y=1.0)
# Keep the caveat inside the exported chart so it travels with the 100% annotation.
fig_bar.text(
    0.01,
    0.01,
    "* Haiku t=0: 100% repeatability does not imply correctness.\n"
    "  This experiment does not measure accuracy.",
    fontsize=8,
)
fig_bar.tight_layout(rect=(0, 0.11, 1, 1))
display(fig_bar)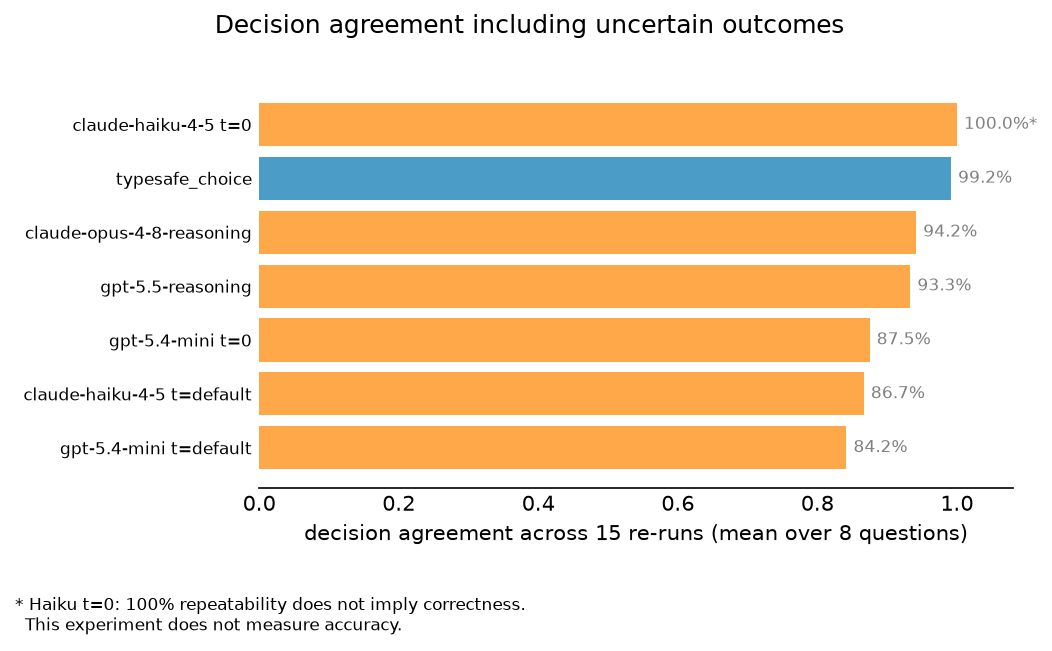
在同樣 0.60 的規則下,temperature 0 的 Haiku 拿到 100%。TypeSafe 是 99.2%,其餘 LLM 條件落在 84.2% 到 94.2% 之間。TypeSafe 在 25.8% 的答案上返回 uncertain,對另外 74.2% 自動處置;temperature 0 的 Haiku 從不棄權。這些百分比衡量的只是可重複性。下面的表把原始一致率和棄權率,與這張圖裡的策略一致率並排放在一起。
讓不確定的機率產生一個「不確定」的決策
機率的一點小變化就可能讓兩個咬得很近的標籤互換。應用不必非要按勝出者行動:當最高機率低於 0.60 時返回 uncertain,把這個案例交給人。恰好等於 0.60 時,就選最高標籤。這裡用的是返回的機率,而不是 API 那個獨立的 confidence 欄位,也不增加任何模型呼叫。
這個閾值是一種示例性的應用策略,既不是經過校準的保證,也不是為了最大化本次執行一致率而挑出來的閾值。生產環境的閾值應當用帶標註的樣本來定,並權衡錯誤處置和人工複核各自的代價。
我們對每個輸出機率的條件都施加同一條規則。單選式 LLM 回答沒有機率估計;它們合成的 one-hot 向量量不出不確定性,所以被排除在一致率圖和表之外。
def agreement_rate(samples: list) -> float:
    """Mean over questions of the raw plurality label's share across all NUM_SAMPLES draws.

    Parse failures count against agreement because a failed route is not a repeated decision.
    """
    shares = []
    for question_key, (_instructions, choices) in QUESTIONS.items():
        labels = list(choices)
        picks = [
            argmax_label(samples[sample][question_key], labels)
            for sample in range(NUM_SAMPLES)
        ]
        picks = [pick for pick in picks if pick is not None]
        if not picks:
            shares.append(0.0)
            continue
        top = Counter(picks).most_common(1)[0][1]
        shares.append(top / NUM_SAMPLES)
    return mean(shares) if shares else float("nan")

# Keep failures separate from abstentions and count conflicting concrete actions per question.
print(
    f"{'condition':<{name_w}}{'raw agree':>12}{'policy agree':>14}"
    f"{'uncertain':>12}{'automatic':>12}{'conflicts':>11}"
)
for label in PROBABILITY_OUTPUT_LABELS:
    decisions = decisions_by_condition[label]
    flat = [value for row in decisions for value in row]
    uncertain_rate = mean(value == "uncertain" for value in flat)
    automatic_rate = mean(value not in (None, "uncertain") for value in flat)
    conflicts = sum(
        len({value for value in row if value not in (None, "uncertain")}) > 1
        for row in decisions
    )
    print(
        f"{label:<{name_w}}{agreement_rate(pooled_runs[label]):>11.1%}"
        f"{policy_agreement_by_condition[label]:>13.1%}{uncertain_rate:>11.1%}"
        f"{automatic_rate:>11.1%}{conflicts:>11}"
    )
condition raw agree policy agree uncertain automatic conflicts
claude-haiku-4-5 t=0 100.0% 100.0% 0.0% 100.0% 0
claude-haiku-4-5 t=default 87.5% 86.7% 0.8% 98.3% 2
gpt-5.4-mini t=0 99.2% 87.5% 12.5% 87.5% 0
gpt-5.4-mini t=default 90.8% 84.2% 22.5% 77.5% 2
gpt-5.5-reasoning 90.0% 93.3% 30.8% 69.2% 1
claude-opus-4-8-reasoning 92.5% 94.2% 33.3% 66.7% 0
typesafe_choice 90.8% 99.2% 25.8% 74.2% 0policy agree 把 uncertain 也算作一種決策;解析失敗計入一致率的分母。automatic 是全部答案中選中了某個標籤的佔比。conflicts 統計的是在多次重複中出現過一個以上具體標籤的問題數,棄權不計。這些指標描述的是可重複性以及應用有多經常行動,而不是它的行動對不對。
TypeSafe 的一致率從 90.8% 升到了 99.2%。答案裡 25.8% 是不確定,74.2% 是自動。primary_risk 和 link_handling 每次重複都返回不確定;category 在 Violence 和 uncertain 之間來回,有些重複越過了行動閾值,有些沒有。沒有任何一個問題給出過兩個不同的具體 TypeSafe 標籤。這些都不說明準確率或誰更優:temperature 0 的 Haiku 在這裡一致率是 100%,且從不棄權。
# Show every TypeSafe decision while retaining the top probability behind it.
policy_decisions = decisions_by_condition[TYPESAFE_LABEL]
policy_values = []
for row, (_key, (_instructions, choices)) in zip(policy_decisions, QUESTIONS.items()):
    labels = list(choices)
    policy_values.append([
        10 if value == "uncertain" else labels.index(value) if value is not None else np.nan
        for value in row
    ])
policy_cmap = ListedColormap([*plt.get_cmap("tab10").colors, "#dddddd"])
policy_cmap.set_bad("white")
fig_policy, ax_policy = plt.subplots(figsize=(13, 4))
ax_policy.imshow(policy_values, cmap=policy_cmap, vmin=0, vmax=10, aspect="auto")
for row_index, key in enumerate(QUESTIONS):
    for sample_index in range(NUM_SAMPLES):
        decision = policy_decisions[row_index][sample_index]
        probability = max(typesafe_runs[sample_index][key])
        ax_policy.text(sample_index, row_index, f"{decision or 'n/a'}\n{probability:.2f}",
                       ha="center", va="center", fontsize=6)
ax_policy.set_yticks(range(len(QUESTIONS)), list(QUESTIONS))
ax_policy.set_xticks(range(NUM_SAMPLES), range(1, NUM_SAMPLES + 1))
ax_policy.set_xlabel("rubric query")
ax_policy.set_title(
    "TypeSafe application decisions: gray means uncertain "
    f"(top probability < {MIN_CHOICE_PROBABILITY:.2f})"
)
fig_policy.tight_layout()
display(fig_policy)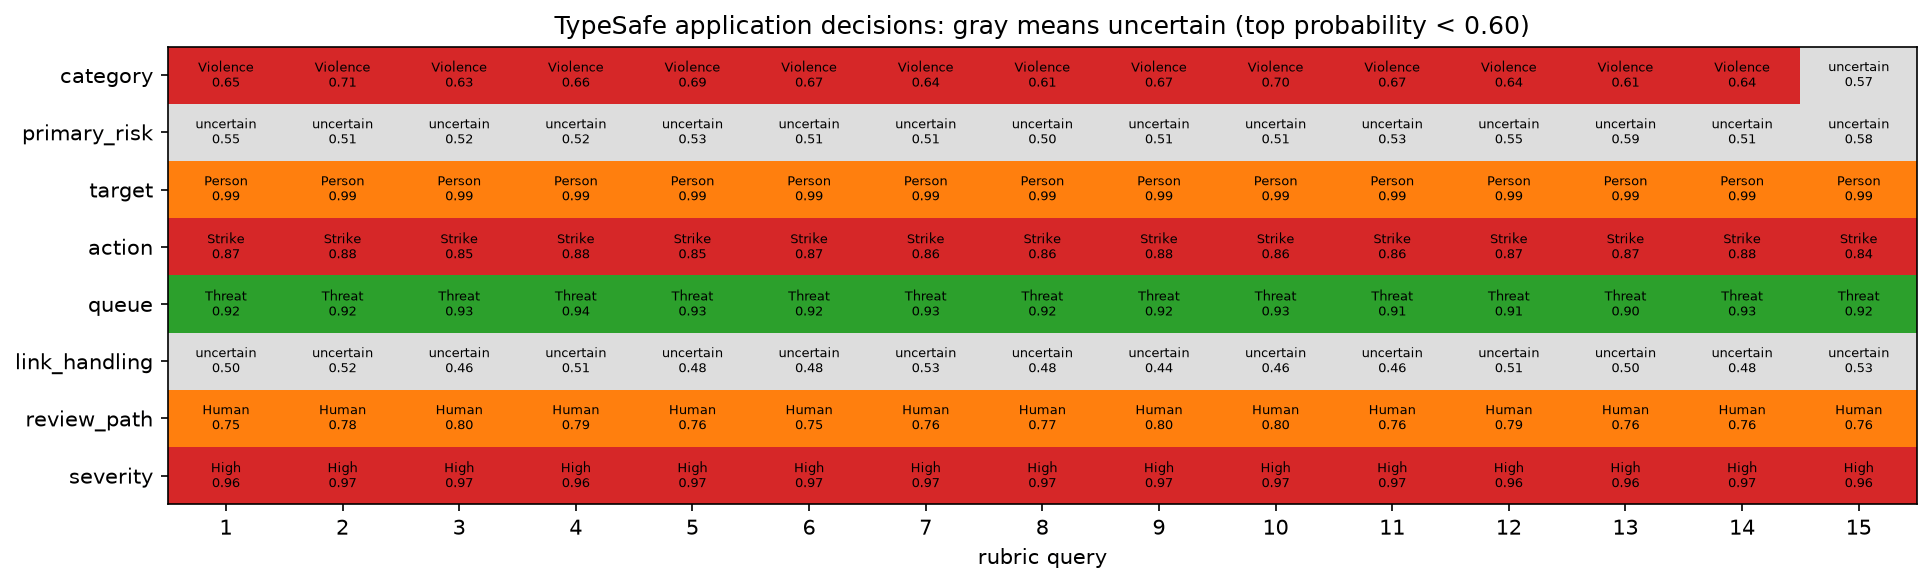
這條策略並不會讓模型變得確定。棄權可以把互相競爭的標籤歸併到同一個「轉人工」結果上,但一個接近 0.60 的機率依然會在某個具體標籤和 uncertain 之間移動。機率統計和表裡的 raw agree 列報告的仍是模型的原始輸出。
在 TypeSafe Playground 裡開啟
下面的連結在 Playground 裡開啟這條同樣的帖子與量規:一條帖子、同樣的 8 個 Choice,以及 TypeSafe 的 jev-latest。
playground_link = make_playground_link(
    {"post": POST},
    {
        key: Choice(instructions=instructions, criteria=choices)
        for key, (instructions, choices) in QUESTIONS.items()
    },
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this post + rubric in the TypeSafe playground]({playground_link})"
    )
)