重排序
重排序
为 40 条 CLERC 法律查询各构建 30 个段落的 BM25 候选列表,然后为每个查询-候选对提一个 TypeSafe 问题,把 top-1 准确率从 5% 提升到 18%,top-10 从 38% 提升到 62%。
你有成千上万份文档,需要找到能回答某个具体问题的那一份。那该怎么找?
首先,用一种快速的方法,比如关键词匹配,把成千上万的候选缩小成一份看起来靠谱的候选列表。我们称之为快速搜索。
快速搜索擅长这件事,但它无法告诉你候选列表里哪一个才是对的。这正是重排序的用武之地。它把候选列表上的每个候选直接对照查询打分,把最好的排到最前面。
下面两步都会在 CLERC 数据集的 3,565 个法院意见段落上运行:BM25 为 40 条查询各构建一份 30 个候选的快速搜索列表,然后 TypeSafe 对每份列表重排序。经过重排序,正确的段落在 18% 的查询上排到第一,而只用快速搜索时是 5%。
沿途你会学到:
- 快速搜索做什么,以及它为什么不是全部答案
- 重排序是什么,以及它如何接在快速搜索之后
- TypeSafe 如何把某个候选用查询来打分,以及这能把结果提升多少
自己试试
在 TypeSafe Playground 中打开一条查询、一个候选和重排序问题
如何在成千上万份文档里找到那一份?
你有一堆文档,还有一个查询——一段描述你要找什么的文字。这堆文档里的某处,就有能回答它的那一份。
逐个把每份文档和查询比对是可行的,但每份文档要一次比对:几百万份文档就意味着每条查询几百万次比对。你可以用一个两步走的方法来提升性能:
- 用一种快到能跑遍整堆文档的方法,把这堆缩小成一份可能候选的短列表。
- 对这份短列表施加一个更精确的步骤,找出确切正确的答案。

这个 cookbook 用一批法院意见数据集测试了这套设置,见下面的一个重排序示例。
什么是快速搜索?
快速搜索是任何能把查询和大型语料库中的每份文档比对、并快速返回一份排好序的短列表的方法。常见方法包括关键词搜索(如 BM25)和按含义比较段落的稠密嵌入。系统常常把两者结合起来。
这里第一步只用 BM25,别的都不用。BM25 按共有的词给段落排序。让这一步保持简单,是为了把注意力留在重排序上,这正是本 cookbook 的重点。快速搜索方法的选择是次要问题:重排序只能看到进入短列表的那些段落。
什么是重排序?
重排序拿到快速搜索已经产出的短列表,把它排成更好的顺序。它不是一次性把查询和整个语料库比对,而是把查询逐个对照短列表上的每个候选,再按这个分数给短列表排序。
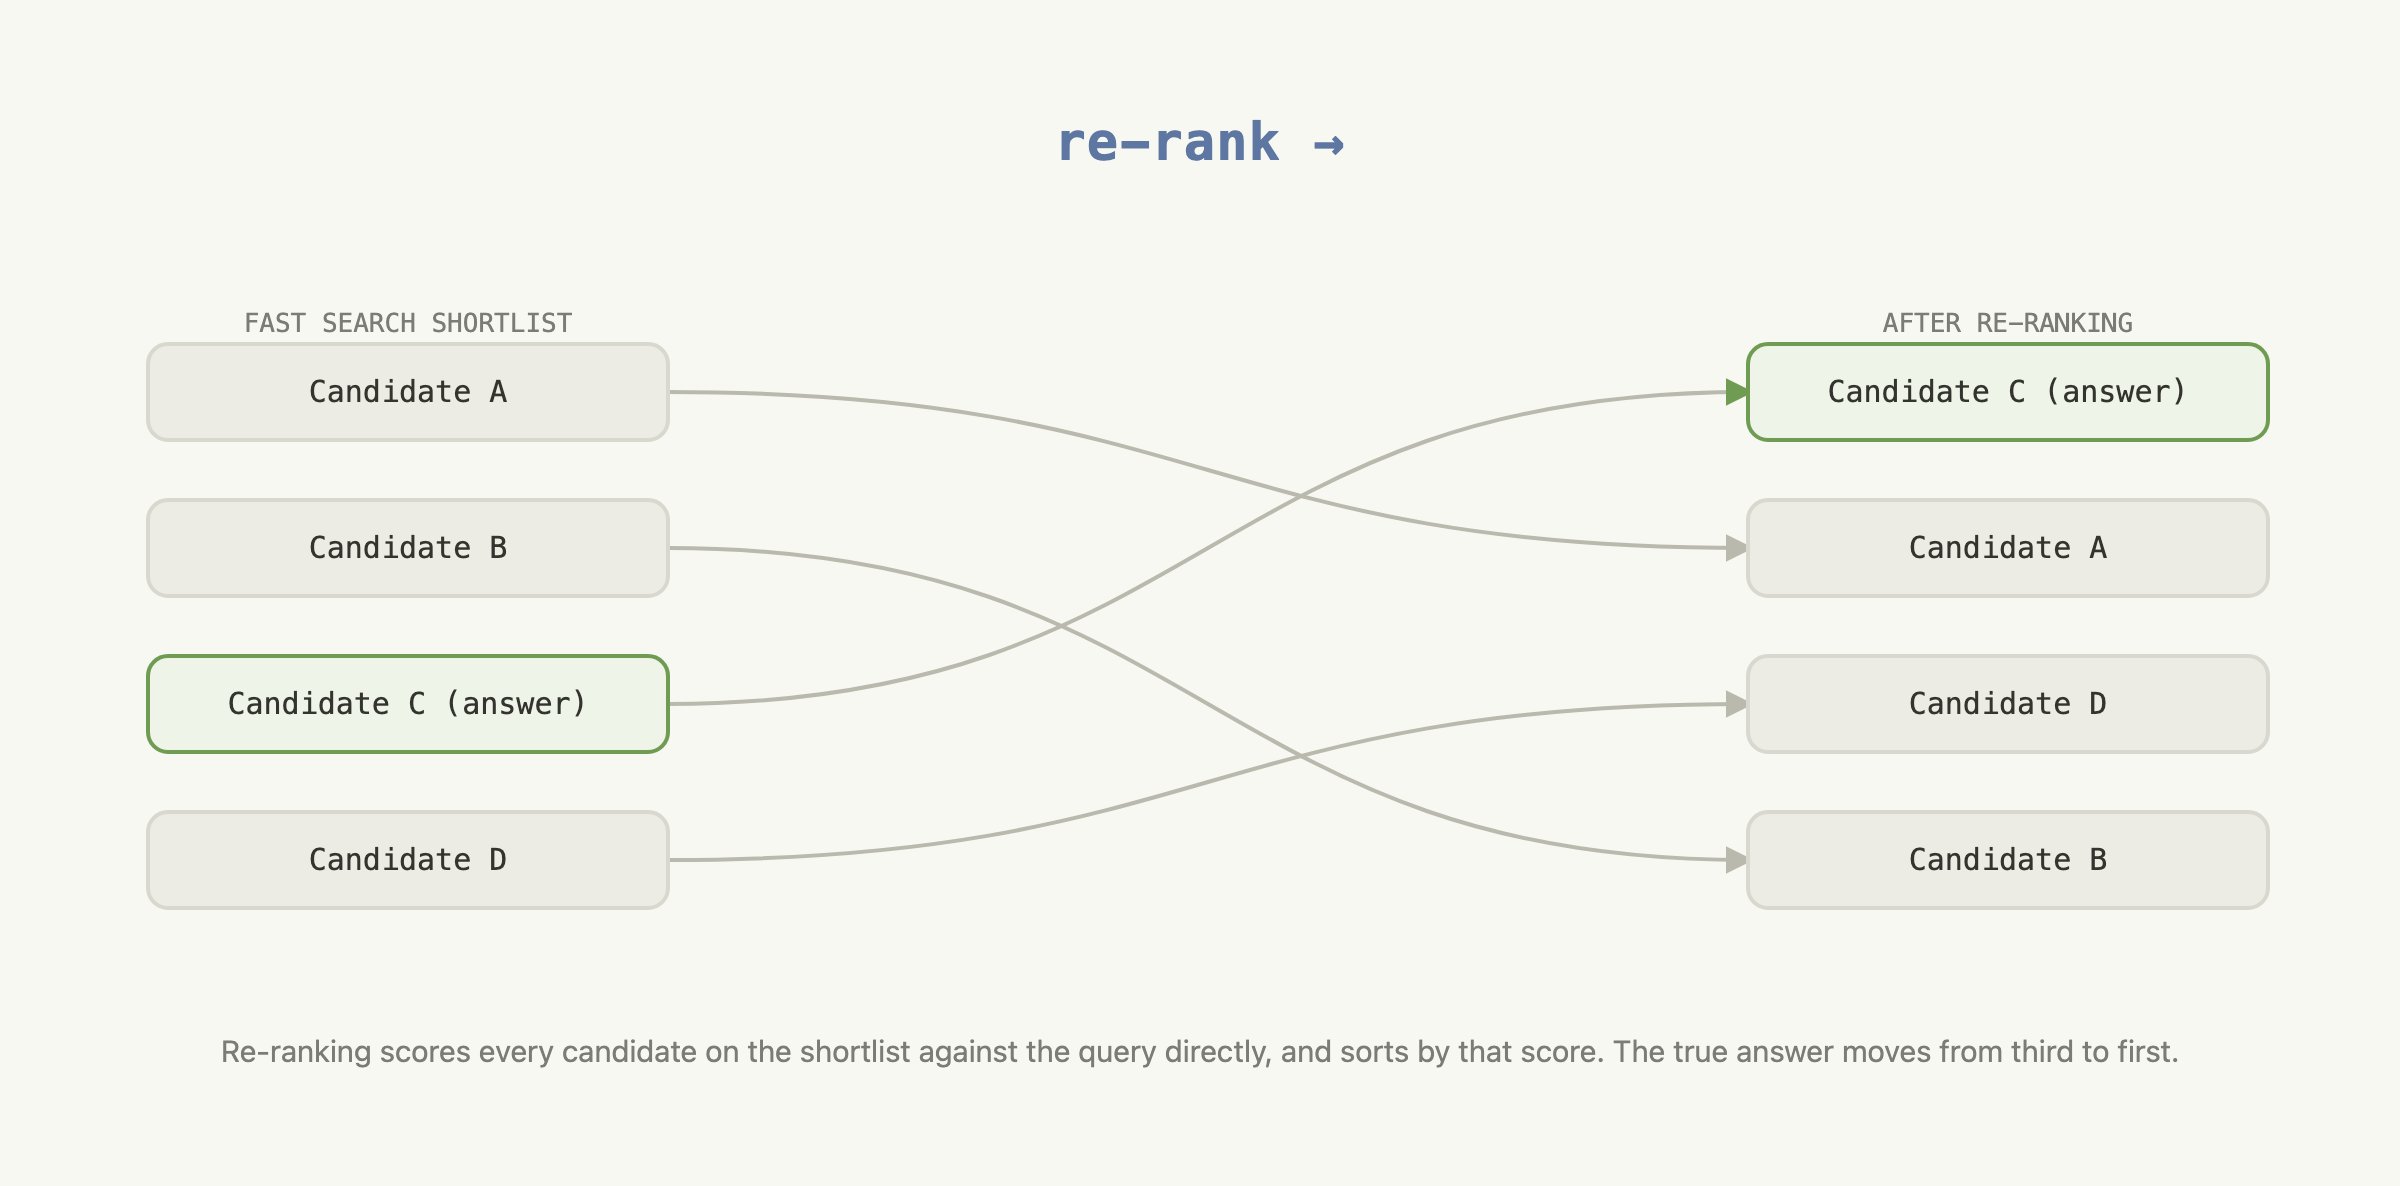
分数可以来自语言模型。把查询和一个候选一起给它,问这个候选对查询的回答有多好。这样,即使候选的措辞和查询不同,重排序也能在短列表上找到最佳匹配。
用 TypeSafe 重排序
重排序器需要为每个查询-候选对给出可比较的分数。通用语言模型可以产生这些分数,也可以直接给整份短列表排序。但对于独立的成对打分,你需要定义一个打分尺度,并提示模型对每个候选应用同一标准。重复调用对同一个对仍可能给出不同的分数,而通用生成会给一个只需要一个数字的任务增加时间和成本。
TypeSafe 返回什么
用 TypeSafe,打分请求可以保持是一个是/否问题:
Could this candidate passage be from the cited precedent?光是一个是或否,不足以给 30 个候选排序。Noul 会返回一个 0 到 1 之间的数字,叫作 noul。noul 是 TypeSafe 对“答案有多可能是是”的估计。
问题的 criteria 定义了什么算真、什么算假。TypeSafe 把它们应用到每个查询-候选对上,直接返回 noul。这个 noul 就是应用用来排序的分数。不必再为通用模型发明一套打分尺度,而 TypeSafe 正是为更快、更省、更一致地做这种重复打分而构建的。
简化成伪代码,一次 TypeSafe 打分调用大致是这样:
question = Noul(
    instructions="Is this candidate the cited case?",
    criteria=NoulCriteria(
        true="The candidate states the specific rule the query cites.",
        false="The candidate is only on a similar topic.",
    ),
)
response = client.system_one(state={...}, questions={"is_cited_source": question})
response.answers["is_cited_source"].noul  # -> 0.87
TypeSafe 把查询和一个候选放在一起对照那个问题来读,返回一个 noul。
你可以用它重排序一份短列表:对列表上的每个候选跑同一个问题,然后按每次调用返回的 noul 给短列表排序,最高的在前。
nouls = {candidate: ask_typesafe(query, candidate) for candidate in shortlist}
reranked = sorted(shortlist, key=lambda c: nouls[c], reverse=True)  # highest noul first
下图展示了每个候选一个请求如何产生用来重排短列表的分数。
flowchart LR
    q["query excerpt<br/><i>one opinion passage,<br/>citation removed</i>"]
    sl["shortlist from fast search<br/><i>30 candidate passages</i>"]
    quest["<b>one Noul</b><br/>could this candidate be<br/>from the cited precedent?<br/><i>criteria fix true and false</i>"]

    %% direction LR inside an LR chart keeps each state beside its noul, two columns,
    %% so the fan-out is four rows tall instead of eight
    subgraph fan["one request per candidate · no request sees another"]
        direction LR
        d1["state<br/>{query, candidate 1}"] --> n1["noul<br/>0.87"]
        d2["state<br/>{query, candidate 2}"] --> n2["noul<br/>0.41"]
        dx["⋮"] --> nx["⋮"]
        d30["state<br/>{query, candidate 30}"] --> n30["noul<br/>0.12"]
    end

    sort["sort by noul,<br/>highest first"]
    out["re-ranked shortlist<br/><i>same 30, better order</i>"]

    q --> fan
    sl --> fan
    quest --> fan
    fan --> sort --> out

    %% the elision is not a node - drop its box so it reads as "and so on"
    classDef elide fill:none,stroke:none
    class dx,nx elide
    linkStyle 2 stroke:none
一个重排序示例
快速搜索和重排序现在跑在 CLERC 上,这是一个法律检索数据集。本例使用 3,565 个法院意见段落和 40 条查询。
环境准备
第一步安装本演示依赖的包。
bm25s和datasets构建快速搜索的短列表。typesafe-sdk和cooksafe负责重排序和 API 缓存。matplotlib绘制结果图表。
pip install bm25s datasets matplotlib 'cooksafe>=0.2.0,<0.3.0'下一个代码块设置 TypeSafe 客户端,以及本演示其余部分用到的常量,比如调用哪个 TypeSafe 模型、快速搜索交给重排序器的短列表有多大。调用 TypeSafe 需要一个 TYPESAFE_API_KEY。
import hashlib
import json
import os
import random
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path

from cooksafe import JsonCache
from IPython.display import display
from typesafe_sdk import Noul, NoulCriteria, TypeSafeClient

TYPESAFE_MODEL = "jev-1.12"
PRICE = (
    0.042,
    0.00,
)  # $ per 1M tokens (input, output); TypeSafe jev-1.12 as of 2026-08
N_ROWS = 170  # CLERC rows pooled into the shared corpus
N_QUERIES = 40  # rows we evaluate
TOP_K = 30  # candidates the shortlist hands to the re-ranker, per query

client = TypeSafeClient(
    api_key=os.environ.get(
        "TYPESAFE_API_KEY", "cache-only"
    ),  # keyless kernels replay the cache
    base_url=os.environ.get("TYPESAFE_ENDPOINT"),
    timeout=120.0,
)
json_cache = JsonCache(Path("json_cache.json"))
用快速搜索给段落排序
这里用的数据集是美国法院意见的语料库,共汇总了 170 行。每一行拆开来看是这样:
- 查询:一段去掉了引用的意见摘录。
- 金标准:被去掉的那条引用所指向的段落,也就是查询的唯一正确答案。
- 候选:语料库中所有其它段落,每一个都是查询可能被误匹配的对象。
170 行里有 40 行被选出来作为查询评估。其余 130 行只作为候选出现。
下一个单元格用上面描述的方法构建短列表:
- 加载语料库。
- 用 BM25 把语料库对每条查询排序。
这里还没有 TypeSafe,这仅仅是快速搜索这一步。
CLERC_FILE = (
    "https://huggingface.co/datasets/jhu-clsp/CLERC/resolve/main/"
    "teva_train_dir/train_data.jsonl.gz"
)

def cid(text: str) -> str:
    """Corpus id: a content hash, so passages shared across queries dedupe."""
    return hashlib.sha1(text.encode("utf-8")).hexdigest()[:16]

@json_cache
def build_slice(n_rows: int, n_queries: int, seed: int) -> dict:
    """Stream CLERC rows, pool ``n_rows`` of them into a corpus, pick ``n_queries`` to evaluate."""
    from datasets import load_dataset  # heavy import, keep local

    stream = load_dataset("json", data_files=CLERC_FILE, streaming=True, split="train")
    rows = []
    for row in stream:
        if (
            row.get("positive_passages")
            and len(row.get("negative_passages") or []) == 20
        ):
            rows.append(row)
        if len(rows) >= 1000:
            break

    rng = random.Random(seed)
    picked = rng.sample(rows, n_rows)
    corpus, pool = {}, []
    for row in picked:
        gold = row["positive_passages"][0]["text"]
        corpus[cid(gold)] = gold
        for neg in row["negative_passages"]:
            corpus[cid(neg["text"])] = neg["text"]
        pool.append(
            {"qid": str(row["query_id"]), "query": row["query"], "gold": cid(gold)}
        )
    # hold out the first 20 pooled rows; evaluate on the rest
    queries = rng.sample(pool[20:], n_queries)
    # sort the corpus by id so every run — live or cache replay — iterates it identically
    return {"queries": queries, "corpus": dict(sorted(corpus.items()))}

def bm25_rankings(corpus: dict[str, str], queries: dict[str, str], k: int = 100):
    """Rank every passage in the corpus by word overlap with each query."""
    import bm25s

    cids = list(corpus)
    retriever = bm25s.BM25()
    retriever.index(bm25s.tokenize([corpus[c] for c in cids], stopwords="en"))
    qids = list(queries)
    idxs, _ = retriever.retrieve(
        bm25s.tokenize([queries[q] for q in qids], stopwords="en"), k=min(k, len(cids))
    )
    return {q: [cids[i] for i in idxs[row]] for row, q in enumerate(qids)}

def gold_rank(ranked: list[str], gold: str) -> int | None:
    """1-based rank of the gold id, or None if it isn't in the list."""
    return ranked.index(gold) + 1 if gold in ranked else None

SURFACE, INK, INK2, MUTED = "#f8f8f2", "#34342f", "#34342f", "#7c7c77"
GRID, AXIS, BLUE, GREEN = "#d8d8cf", "#d8d8cf", "#5d76a2", "#6f9b52"

def bar_chart(labels: list[str], shares: list[float], title: str) -> None:
    """A small single-series bar chart of shares (0-1, shown as percentages)."""
    import matplotlib.pyplot as plt

    fig, ax = plt.subplots(figsize=(5, 3.2), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    bars = ax.bar(labels, shares, width=0.55, color=[BLUE, GREEN][: len(labels)])
    ax.bar_label(
        bars,
        labels=[f"{s * 100:.0f}%" for s in shares],
        padding=4,
        color=INK,
        fontsize=11,
    )
    ax.set_ylim(0, 1.1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(title, loc="left", color=INK, fontsize=11)
    plt.tight_layout()
    display(fig)
    plt.close(fig)

ds = build_slice(N_ROWS, N_QUERIES, seed=0)
corpus: dict[str, str] = ds["corpus"]
queries = {q["qid"]: q["query"] for q in ds["queries"]}
golds = {q["qid"]: q["gold"] for q in ds["queries"]}

candidates = {q: ranked[:TOP_K] for q, ranked in bm25_rankings(corpus, queries).items()}

in_top_k = sum(golds[q] in candidates[q] for q in queries)
at_rank_1 = sum(candidates[q][0] == golds[q] for q in queries)

bar_chart(
    [f"In top {TOP_K}", "At rank 1"],
    [in_top_k / len(queries), at_rank_1 / len(queries)],
    f"Where the correct passage lands, {len(queries)} queries against {len(corpus):,} candidates",
)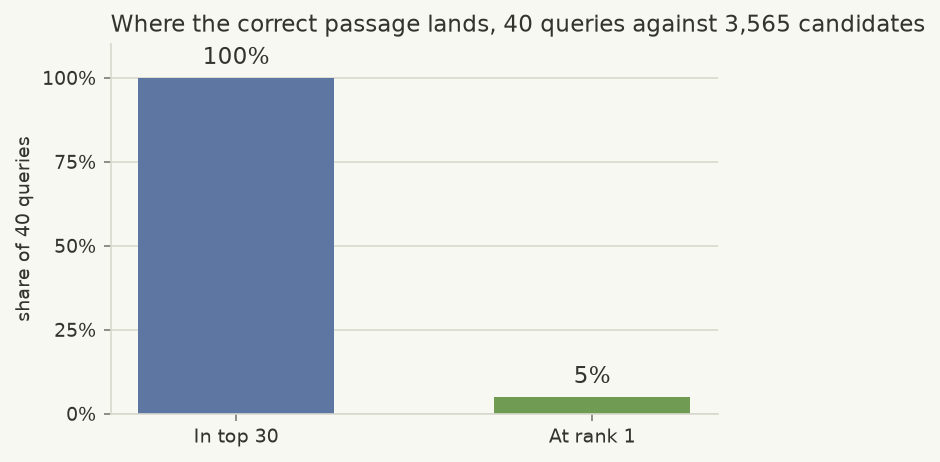
快速搜索不太可能把正确的段落排在第一
这张图显示在 3,565 个候选中,快速搜索把正确段落放在哪里。
快速搜索能可靠地把语料库缩小到一份包含正确答案的短列表。对于 40 条查询,它 100% 都包含正确答案。但那个段落很少是短列表上排第一的,只有 5% 的时候是。
下面的重排序只重新排列短列表上已有的前 30 个候选。它无法加入快速搜索没有选中的段落。在这里,短列表对全部 40 条查询都包含正确的段落,所以重排序可以专注于把每一个放到更好的位置。
用 TypeSafe 重排序
重排序把短列表上每个候选对照它的查询打分,再按这个分数排序。TypeSafe 对每一对问的问题是:这个候选有没有可能是查询那条被去掉的引用所指向的段落。
下一个单元格做以下事情:
- 定义那个问题。
- 对每份短列表上的每个候选各问一次,40 条查询乘以 30 个候选,共 1,200 次调用,并发运行而不是一个接一个。
- 按 TypeSafe 返回的分数给每份短列表排序,得到重排序后的结果。
is_cited_source = Noul(
    instructions=(
        "The query excerpt comes from a US federal court opinion and was written "
        "immediately around a citation to a precedent; the citation itself has been "
        "removed. Could the candidate passage be from that cited precedent — does it "
        "establish the specific legal proposition the query excerpt invokes at its "
        "citation point?"
    ),
    criteria=NoulCriteria(
        true=(
            "The candidate passage states or establishes the specific rule, standard, "
            "holding, or fact pattern that the query excerpt attributes to its removed "
            "citation."
        ),
        false=(
            "The candidate passage is merely on a similar topic or doctrine; it does not "
            "supply the specific proposition the query excerpt relies on."
        ),
    ),
)

@json_cache
def score_candidate(model: str, query: str, candidate: str, question_json: str) -> dict:
    """One TypeSafe call about one (query, candidate) pair: a noul, plus token usage."""
    # the SDK takes a question as its JSON dict, so the cached string decodes straight in
    question = json.loads(question_json)
    response = client.system_one(
        state={"query_excerpt": query, "candidate_passage": candidate},
        questions={"is_cited_source": question},
        model=model,
    )
    return {
        "noul": response.answers["is_cited_source"].noul,
        "input_tokens": response.usage.input_tokens or 0,
        "output_tokens": response.usage.output_tokens or 0,
    }

# Each of the 40 queries has 30 candidates, so re-ranking every shortlist means 1,200 independent
# calls — cheap enough to fire all at once with a thread pool instead of one after another.
pair_list = [(q, c) for q in queries for c in candidates[q]]
question_json = is_cited_source.model_dump_json(exclude_none=True)
with ThreadPoolExecutor(max_workers=12) as pool:
    results = pool.map(
        lambda p: score_candidate(
            TYPESAFE_MODEL, queries[p[0]], corpus[p[1]], question_json
        ),
        pair_list,
    )
pair_scores = {q: {} for q in queries}
for (q, c), result in zip(pair_list, results):
    pair_scores[q][c] = result

reranked = {
    q: sorted(candidates[q], key=lambda c: -pair_scores[q][c]["noul"]) for q in queries
}

def chart_before_after(
    runs: dict[str, dict[str, list[str]]], thresholds: list[int]
) -> None:
    """Grouped bar chart: how often the correct passage lands in the top N, for each run."""
    import numpy as np
    import matplotlib.pyplot as plt

    labels = list(runs)
    colors = [BLUE, GREEN]

    def share_in_top(rankings, k):
        return sum(
            gold_rank(rankings[q], golds[q]) in range(1, k + 1) for q in queries
        ) / len(queries)

    fig, ax = plt.subplots(figsize=(6.5, 3.6), facecolor=SURFACE)
    ax.set_facecolor(SURFACE)
    for side in ("top", "right"):
        ax.spines[side].set_visible(False)
    for side in ("left", "bottom"):
        ax.spines[side].set_color(AXIS)
    ax.tick_params(colors=MUTED, labelcolor=INK2, labelsize=9)
    ax.set_axisbelow(True)
    ax.grid(axis="y", color=GRID, linewidth=0.8)

    x = np.arange(len(thresholds))
    width = 0.35
    for i, (label, rankings) in enumerate(runs.items()):
        shares = [share_in_top(rankings, k) for k in thresholds]
        offset = (i - (len(labels) - 1) / 2) * width
        bars = ax.bar(x + offset, shares, width * 0.92, color=colors[i], label=label)
        ax.bar_label(
            bars,
            labels=[f"{s * 100:.0f}%" for s in shares],
            padding=3,
            color=INK2,
            fontsize=8.5,
        )

    ax.set_xticks(x, [f"top {k}" for k in thresholds])
    ax.set_ylim(0, 1)
    ax.set_yticks([0, 0.25, 0.5, 0.75, 1.0])
    ax.set_yticklabels(["0%", "25%", "50%", "75%", "100%"])
    ax.set_ylabel(f"share of {len(queries)} queries", color=INK2, fontsize=9)
    ax.set_title(
        "How often the correct passage lands near the top",
        loc="left",
        color=INK,
        fontsize=11,
    )
    ax.legend(frameon=False, labelcolor=INK2, fontsize=9, loc="upper left")
    plt.tight_layout()
    display(fig)
    plt.close(fig)

chart_before_after(
    {"Fast search": candidates, "+ TypeSafe re-rank": reranked}, [1, 5, 10]
)

calls = [pair_scores[q][c] for q in queries for c in pair_scores[q]]
input_tokens = sum(call["input_tokens"] for call in calls)
output_tokens = sum(call["output_tokens"] for call in calls)
cost = input_tokens / 1_000_000 * PRICE[0] + output_tokens / 1_000_000 * PRICE[1]
print(
    f"{len(calls)} TypeSafe calls used {input_tokens:,} input and "
    f"{output_tokens:,} output tokens, costing ${cost:.4f}."
)
1200 TypeSafe calls used 1,536,002 input and 25,200 output tokens, costing $0.0645.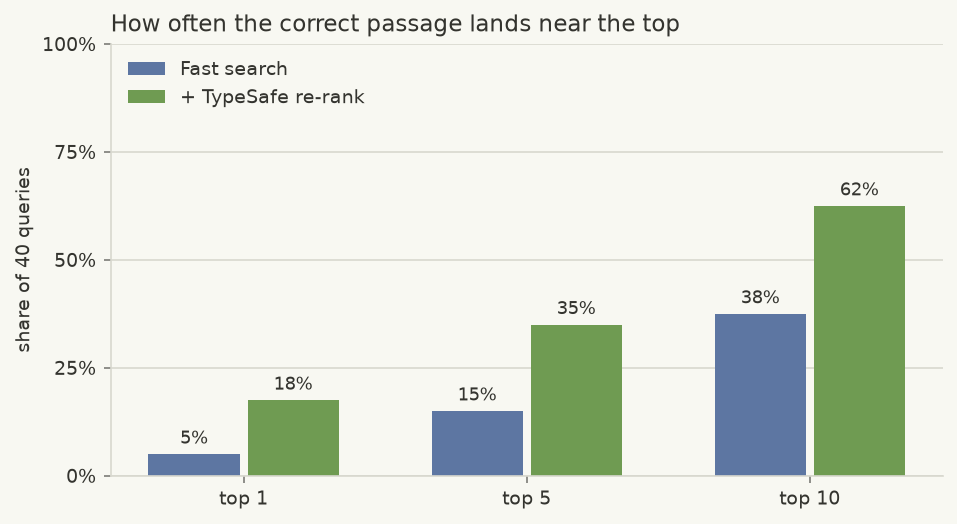
重排序把正确答案移向最前面
这张图在三个阈值上比较快速搜索和快速搜索加重排序。在每一个阈值上,重排序都把正确的段落移得更靠近最前面:
- Top 1 — 5% → 18%
- Top 5 — 15% → 35%
- Top 10 — 38% → 62%
报告的 token 数和成本涵盖用于重排序这 40 份短列表的全部 1,200 次 TypeSafe 调用。
每一行 CLERC 数据包含一个正确段落和 20 个负例段落。本演示把 170 行的段落汇总进一个共享语料库。对 40 条评估查询中的每一条,BM25 从整个语料库中选出 30 个候选,而不只是该行附带的 20 个负例。随后 TypeSafe 把查询对照每个选中的候选来读,并重排序那 30 个段落。
为了清晰,本演示对每一对只问了一个问题。真实应用会在一次调用中对同一对问好几个问题。做法见并行问题 cookbook和投机式扇出模式。
接下来
同样的积木也出现在 TypeSafe 文档的其它地方: