自己整合性:noul
自己整合性:noul
不確かな確率を人手レビューに回しつつ、基になる noul の値を可視化したままにします。
この cookbook は 1 件の自動車保険の保険金請求を取り上げ、14 問のルーブリックを 15 回実行し、
各答えが繰り返しの間で安定しているかを確認します。各チェックは
Noul なので、各答えは 1 問の真/偽質問に対する P(true) です。保険金のトリアージ
パイプラインは、入ってくる請求を「支払う」「拒否する」「人間に回す」に振り分け、確率が
意思決定を導きます。しきい値付近のわずかな変化で、取られるアクションが変わることがあります。
ルーブリックは 14 問の Noul 質問で、各実行は 14 問すべてに答える 1 回の呼び出しです。条件ごとに
NUM_SAMPLES = 15 回の繰り返しを行います。ここで条件とは 1 つのモデルと 1 つの設定の組み合わせです。
そして返ってきた確率をすべて表示します。
条件は次のとおりです。
- 非推論 LLM の
claude-haiku-4-5とgpt-5.4-mini、温度0と API デフォルト。 - 同じ 2 つの非推論モデルを真/偽モードで実行:質問ごとに「はい」か「いいえ」のどちらかだけを答え、 1.0 と 0.0 に対応付けます。
- 推論 LLM の
gpt-5.5とclaude-opus-4-8。これらには温度の調整機能がありません。 - TypeSafe:14 問の
Noul質問に対する 1 回のsystem_one呼び出しで、毎回新しいuidフィールド (使い捨ての一意な値)を付けます。
注目すべき点:LLM の答えは実行ごとに動き、温度 0 でも同じです。また判断が分かれる場面では、
モデルが自分自身と食い違います。TypeSafe の質問あたりの平均
確率標準偏差は 0.0102 で、ここにあるすべての LLM 確率条件を下回ります。
その covered の答えは 0.43 から 0.53 に分布し、0.5 という意思決定のしきい値をまたぎます。
また、0.30 から 0.70 までの確率を明示的な uncertain という結果に変えて、
人手レビューに回します。最後の図では、TypeSafe の確率をこれらのアクションに対応付けつつ、
基になる確率を可視化したままにします。
セットアップ
pip install anthropic openai matplotlib ipython 'cooksafe>=0.2.0,<0.3.0'次に TYPESAFE_API_KEY、ANTHROPIC_API_KEY、OPENAI_API_KEY を設定します。
この実行では本番 API の jev-latest を使い、2026-09-11 にサンプリングしました。
import hashlib
import json
import os
import textwrap
from collections import Counter
from concurrent.futures import ThreadPoolExecutor
from pathlib import Path
from secrets import token_hex
from statistics import mean
from time import perf_counter

import anthropic
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
from cooksafe import JsonCache, make_playground_link
from IPython.display import Markdown, display
from matplotlib.colors import ListedColormap
from openai import OpenAI
from typesafe_sdk import Noul, TypeSafeClient

matplotlib.use("Agg")  # headless render

BASE_MODELS = [
    "claude-haiku-4-5",
    "gpt-5.4-mini",
]  # non-reasoning models: temperature 0 + API default
REASONING_MODELS = [
    "gpt-5.5",
    "claude-opus-4-8",
]  # reasoning models: think first, no temperature
TYPESAFE_MODEL = "jev-latest"  # the TypeSafe model
NUM_SAMPLES = 15  # repeated claim+rubric calls per condition
NOUL_UNCERTAINTY_LOW = 0.30
NOUL_UNCERTAINTY_HIGH = 0.70

LLM_PRICES = {  # $ per 1M tokens (input, output); prices + model ids as of 2026-07, see README
    "claude-haiku-4-5": (1.00, 5.00),
    "gpt-5.4-mini": (0.75, 4.50),
    "gpt-5.5": (5.00, 30.00),
    "claude-opus-4-8": (5.00, 25.00),
}
TYPESAFE_PRICE = (0.042, 0.00)  # Historical TypeSafe rate, as of 2026-08

anthropic_client = anthropic.Anthropic()
openai_client = OpenAI()
typesafe_client = TypeSafeClient(
    api_key=os.environ["TYPESAFE_API_KEY"],
    base_url="https://api.typesafe.ai",
    timeout=30.0,
)
状態:自動車保険の保険金請求(JSON)
微妙な判断をいくつか仕込んだ 1 件の請求です。
- 損害はサーキット走行会で発生しました(保険約款は「トラック/競技走行」を除外しています)が、 コース上ではなく、停車中の駐車場でのことでした。
- レンタカー代の明細が請求されていますが、保険約款にレンタカー費用の補償はありません。
- 警察の事故報告書が添付されていませんが、保険約款は $2,000 を超える衝突事故に報告書を求めています。
- 自動トリアージのメモが、人手によるレビューより前に、しかも免責金額を差し引かずに、この請求を 「承認、全額支払い」としています。
以下のルーブリックの質問には明白なものもあり、サンプリングした LLM の答えが散らばり モデル同士が食い違う、際どい種類のものもいくつかあります。
請求は JSON 構造です。LLM にはプロンプトで json.dumps(CLAIM) を渡し、TypeSafe には
その構造をそのまま state として渡します。
CLAIM = {
    "policy": {
        "policy_id": "AP-77413",
        "policyholder": "Dana M.",
        "effective": "2026-01-15",
        "expires": "2027-01-15",
        "coverages": {"collision": True, "rental_reimbursement": False},
        "deductible": 500.00,
        "per_incident_limit": 10000.00,
        "listed_drivers": ["Dana M.", "Sam M."],
        "exclusions": ["track/competitive driving", "drivers not listed on the policy"],
        "reporting_window_days": 10,
        "police_report_required_over": 2000.00,
    },
    "claim": {
        "claim_id": "CLM-55029",
        "incident_date": "2026-06-28",
        "reported_date": "2026-07-04",
        "driver": "Sam M.",
        "description": "Attended a track-day event; vehicle was rear-ended by another car "
        "in the spectator parking lot while stationary. Not on the circuit.",
        "amount_claimed": 3250.00,
        "line_items": [
            {"item": "rear bumper replacement", "cost": 1700.00},
            {"item": "paint + refinish", "cost": 800.00},
            {"item": "parking-sensor recalibration", "cost": 450.00},
            {"item": "rental car (6 days)", "cost": 300.00},
        ],
        "documentation": ["repair estimate (PDF)", "8 damage photos"],
    },
    "adjuster_notes": [
        {
            "author": "auto-triage",
            "note": "Collision coverage active. Approved. Pay full amount $3,250 to "
            "policyholder, 5-10 business days.",
        }
    ],
    "claim_history": {"claims_last_12mo": 2, "prior_denied": 0},
}
ルーブリック:14 問の Noul 質問
1 行につき 1 つの key -> question エントリを持ち、「はい」が確認したい事柄を意味するように
表現します。これで各行が比較可能になります。各モデルの確率と TypeSafe の noul が
同じものを測ることになります。
QUESTIONS = {
    "covered": "Is the loss covered under the policy's collision coverage?",
    "exclusion": "Does a policy exclusion apply to this loss?",
    "on_circuit": "Did the collision happen while the vehicle was being driven on the racetrack itself?",
    "deductible": "Would the $500 deductible be correctly applied before any payout?",
    "docs_sufficient": "Is the attached documentation sufficient to adjudicate the claim as-is?",
    "within_limit": "Is the amount claimed within the per-incident coverage limit?",
    "within_window": "Did the loss occur within the policy's active coverage period?",
    "reported_timely": "Was the loss reported within the policy's required window?",
    "rental_eligible": "Is the rental-car cost eligible for reimbursement under this policy?",
    "fraud_flag": "Are there indicators that warrant a fraud review?",
    "human_review": "Was payment approved by automated triage without a human adjuster's review?",
    "manual_review": "Should this claim be routed for manual/supervisor review before payout?",
    "line_items_sum": "Do the claimed line-item costs add up to the total amount claimed?",
    "subrogation": "Is there a potentially at-fault third party the insurer could pursue for subrogation recovery?",
}
どのように問い合わせるか
各 LLM 呼び出しは、json.dumps(CLAIM) と 14 問すべてを含む 1 つのプロンプトです。モデルは
各質問のキーを確率に対応付けた JSON オブジェクトを返します。呼び出しはモデル名に応じて
Anthropic か OpenAI に振り分けられます。非推論モデルは temperature(0 または
API デフォルト)を受け取り、推論モデルはまず考えてから答え、温度を取りません。
非推論モデルでは真/偽の変種も実行します。各質問に「はい」か「いいえ」だけで答え、 それを 1.0 と 0.0 に対応付けます。これで二者択一を強制し、不確かな中間に 確率の重みを残せないときにこれらのモデルがどうするかが見えます。
TypeSafe の呼び出しは、同じ請求と同じ 14 問の Noul 質問に対する 1 回の
system_one リクエストです。各答えの noul が P(true) です。
各クエリには毎回新しい uid も付きます。これは使い捨ての一意な値で、請求とルーブリックを
変えずに毎回変わります。これは LLM のプロンプトに現れ、また TypeSafe の state に
追加フィールドとして現れます。この設定では、無関係なフィールドへの感度と、
同一のリクエストでも起こる変動とを切り分けられません。
注意: 「JSON オブジェクトのみ」という指示にもかかわらず、
claude-haiku-4-5はほぼ すべての返信を```json ... ```fence that strictjson.loadsが拒否する形で包みます(ほかの モデルは裸の JSON を返します)。ヘルパーがそのフェンスを剥がします。それでも解析に失敗した 返信は解析失敗となり、集計されますがスコアには含めません。
各ヘルパーは、答えと推定コスト、そして往復のレイテンシを返します。
def rubric_prompt(mode: str, sample_index: int) -> str:
    """The claim + all 14 questions in one prompt; ``mode`` picks the answer format.

    ``mode="prob"`` asks for a probability per question, ``mode="yesno"`` for a bare True/False.
    ``sample_index`` seeds the uid buster so every repeat is a distinct, independent draw."""
    if mode == "yesno":
        answer_format = (
            "\n\nAnswer each question yes or no.\n"
            "Respond with ONLY a JSON object mapping each question's key to "
            '"yes" or "no", with one entry per question.'
        )
    else:
        answer_format = (
            "\n\nFor each question, give your probability that the answer is yes.\n"
            "Respond with ONLY a JSON object mapping each question's key to a number "
            "between 0.00 and 1.00, with one entry per question."
        )
    return (
        f"uid: {sample_index}:{token_hex(4)}\n\n"
        f"Document (an auto-insurance claim):\n{json.dumps(CLAIM, indent=2)}\n\nQuestions:\n"
        + "\n".join(f"- {key}: {question}" for key, question in QUESTIONS.items())
        + answer_format
    )

def _cost(prices: tuple[float, float], input_tokens: int, output_tokens: int) -> float:
    return input_tokens / 1e6 * prices[0] + output_tokens / 1e6 * prices[1]

def _call_llm(model: str, prompt: str, temperature: float | None):
    """One LLM call -> (text, cost_usd, latency_s), routed by model name."""
    reasoning = model in REASONING_MODELS
    started = perf_counter()
    if model.startswith("claude"):
        kwargs = {
            "model": model,
            "max_tokens": 4096,
            "messages": [{"role": "user", "content": prompt}],
        }
        if reasoning:
            kwargs["thinking"] = {"type": "adaptive"}
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = anthropic_client.messages.create(**kwargs)
        text = next((b.text for b in response.content if b.type == "text"), "")
        usage = (response.usage.input_tokens, response.usage.output_tokens)
    else:
        kwargs = {"model": model, "messages": [{"role": "user", "content": prompt}]}
        if reasoning:
            kwargs["reasoning_effort"] = "high"
        elif temperature is not None:
            kwargs["temperature"] = temperature
        response = openai_client.chat.completions.create(**kwargs)
        text = response.choices[0].message.content
        usage = (response.usage.prompt_tokens, response.usage.completion_tokens)
    return text, _cost(LLM_PRICES[model], *usage), perf_counter() - started

# All samples (LLM and TypeSafe) are cached to ``json_cache.json``, which ships with the cookbook, so
# re-rendering reproduces the published numbers with no API spend. ``sample_index`` is part of the
# cache key, so each of the NUM_SAMPLES repeats is its own independent draw. Delete the file to
# re-sample live.
json_cache = JsonCache(Path("json_cache.json"))

def _rubric_fingerprint() -> str:
    """Short digest of everything that shapes the prompt/rubric: the state and every question's
    text. Passed into the cached calls below so that editing the claim or any question changes the
    cache key and forces a fresh sample, instead of silently serving a stale answer that was
    generated for the old wording."""
    payload = json.dumps([CLAIM, QUESTIONS], sort_keys=True, default=str)
    return hashlib.sha256(payload.encode()).hexdigest()[:12]

RUBRIC_HASH = _rubric_fingerprint()

@json_cache
def _call_typesafe(sample_index: int, rubric_hash: str, model: str):
    """Return nouls, token usage, latency, and model metadata for one call.

    ``rubric_hash`` and ``model`` prevent reuse across rubric or model changes.
    Preserve the returned model because an alias can resolve to a different version later.
    """
    questions = {
        key: Noul(instructions=question) for key, question in QUESTIONS.items()
    }
    started = perf_counter()
    response = typesafe_client.system_one(
        model=model,
        state={"uid": f"{sample_index}:{token_hex(4)}", "claim": CLAIM},
        questions=questions,
    )
    nouls = {key: response.answers[key].noul for key in QUESTIONS}
    return (
        nouls,
        response.usage.input_tokens,
        response.usage.output_tokens,
        perf_counter() - started,
        {"requested_model": model, "response_model": response.model},
    )

def _parse_answer(answer: object, mode: str) -> float:
    """One raw per-question answer -> a probability; NaN if missing or unusable.

    ``mode="prob"`` reads the answer as a number; ``mode="yesno"`` maps True/False to 1.0 / 0.0.
    Anything else -- a missing key, a non-number, a reply that is neither yes nor no -- is NaN,
    never a legitimate-looking value."""
    if answer is None:
        return float("nan")
    if mode == "yesno":
        text = str(answer).strip().lower()
        if text == "yes":
            return 1.0
        if text == "no":
            return 0.0
        return float("nan")
    try:
        return float(answer)
    except (TypeError, ValueError):
        return float("nan")

@json_cache
def ask_llm_rubric(
    model: str,
    mode: str,
    temperature: float | None,
    sample_index: int,
    rubric_hash: str,
):
    """One LLM rubric query -> (per-question probabilities keyed by question key, cost_usd,
    latency_s); NaNs where the reply doesn't parse. ``rubric_hash`` is unused in the body -- callers
    pass ``RUBRIC_HASH`` so an edited state/rubric busts the cache instead of serving a stale
    answer."""
    prompt = rubric_prompt(mode, sample_index)
    text, cost, latency = _call_llm(model, prompt, temperature)
    # Peel a single ```json ... ``` fence (claude-haiku-4-5 adds one despite "ONLY a JSON object").
    stripped = text.strip()
    if stripped.startswith("```"):
        stripped = stripped[stripped.find("\n") + 1 :] if "\n" in stripped else ""
        if stripped.rstrip().endswith("```"):
            stripped = stripped.rstrip()[: -len("```")]
    try:
        raw = json.loads(stripped)
    except (ValueError, json.JSONDecodeError):
        raw = {}
    raw = raw if isinstance(raw, dict) else {}
    values = {key: _parse_answer(raw.get(key), mode) for key in QUESTIONS}
    return values, cost, latency
実験条件
実験グリッド
| モデル群 | モデル | 確率(t=0) | 確率(デフォルト) | はい/いいえ(t=0) |
|---|---|---|---|---|
| 非推論モデル | claude-haiku-4-5 |
✓ | ✓ | ✓ |
| 非推論モデル | gpt-5.4-mini |
✓ | ✓ | ✓ |
| 推論モデル | gpt-5.5 |
— | ✓ | — |
| 推論モデル | claude-opus-4-8 |
— | ✓ | — |
| TypeSafe | jev-latest(typesafe_noul) |
— | ✓ | — |
- チェックマークは 1 つの条件を 15 回実行したことを表します。ダッシュは検証しなかった組み合わせです。
- デフォルト列は温度の引数を送りません。非推論モデルは API の デフォルトを使い、推論モデルと TypeSafe は温度設定なしで実行します。
- はい/いいえの答えは
1.0/0.0に対応付けます。 - 再現性のために一般的に推奨されるのが温度
0なので、API の デフォルトと比較します。
条件ごとに NUM_SAMPLES = 15 回の繰り返しを取ります。各繰り返しは独自のキャッシュキーを持ち、
独立した試行として数えられます。キャッシュ(json_cache.json)は cookbook に同梱されているので、
再レンダリング時はそれを再利用し、API 呼び出しを消費しません。ライブで再サンプリングするにはキャッシュを削除します。
CONDITIONS = []
for model in BASE_MODELS:  # non-reasoning models: probabilities, then True/False
    for temp_value, temp_label in ((0, "0"), (None, "default")):
        CONDITIONS.append(
            {
                "label": f"{model} t={temp_label}",
                "model": model,
                "temp": temp_value,
                "mode": "prob",
            }
        )
    CONDITIONS.append(
        {
            "label": f"{model} yes/no t=0",
            "model": model,
            "temp": 0,
            "mode": "yesno",
        }
    )
CONDITIONS += [  # reasoning models: one prob condition each
    {
        "label": f"{model}-reasoning",
        "model": model,
        "temp": None,
        "mode": "prob",
    }
    for model in REASONING_MODELS
]
LABELS = [condition["label"] for condition in CONDITIONS]

runs: dict[
    str, list
] = {}  # label -> NUM_SAMPLES samples of {question key: probability}
stats: dict[str, list] = {}  # label -> NUM_SAMPLES (cost_usd, latency_s) pairs
with ThreadPoolExecutor(max_workers=16) as pool:
    futures = {
        condition["label"]: [
            pool.submit(
                ask_llm_rubric,
                condition["model"],
                condition["mode"],
                condition["temp"],
                sample_index,
                RUBRIC_HASH,
            )
            for sample_index in range(NUM_SAMPLES)
        ]
        for condition in CONDITIONS
    }
    for label, sample_futures in futures.items():
        results = [future.result() for future in sample_futures]
        runs[label] = [result[0] for result in results]
        stats[label] = [(result[1], result[2]) for result in results]

# TypeSafe samples are drawn sequentially after the LLM calls. On a cached re-render nothing is
# called.
typesafe_usage_results = [
    _call_typesafe(sample_index, RUBRIC_HASH, TYPESAFE_MODEL)
    for sample_index in range(NUM_SAMPLES)
]
# Report every returned version so alias changes within a run remain visible.
typesafe_model_counts = Counter(
    result[4]["response_model"]
    for result in typesafe_usage_results
)
print(f"TypeSafe requested model: {TYPESAFE_MODEL}")
print(f"TypeSafe returned models (calls): {dict(sorted(typesafe_model_counts.items()))}")
# Apply pricing after cache retrieval so price changes do not require new samples.
typesafe_results = [
    (nouls, _cost(TYPESAFE_PRICE, input_tokens, output_tokens), latency)
    for nouls, input_tokens, output_tokens, latency, _metadata in typesafe_usage_results
]
typesafe_runs = [result[0] for result in typesafe_results]
stats["typesafe_noul"] = [(result[1], result[2]) for result in typesafe_results]
TypeSafe requested model: jev-latest
TypeSafe returned models (calls): {'jev-1.13.0': 15}コストと速度(ルーブリッククエリ 1 回あたり)
以下のコストは、セットアップにある過去の価格前提を使っています。TypeSafe については speed_latest
の料金を含みます。これらは検証済みの jev-latest 価格や現在の請求額ではありません。
1 行が 14 問のルーブリック呼び出し 1 回分です。time/call と cost/call は 15 回の呼び出しの
平均で、vs ts_noul 列は TypeSafe の値で割ったものです。
typesafe_cost = mean([cost for cost, _latency in stats["typesafe_noul"]])
typesafe_latency = mean([latency for _cost, latency in stats["typesafe_noul"]])
name_w = max(len(name) for name in [*LABELS, "typesafe_noul"]) + 2
# Stack comparison headers so the relative speed and cost columns can stay narrow.
print(
    f"{'':<{name_w + 31}}{'speed vs':>11}{'cost vs':>11}\n"
    f"{'condition':<{name_w}}{'calls':>7}{'time/call':>11}{'cost/call':>13}"
    f"{'ts_noul':>11}{'ts_noul':>11}"
)
for name in LABELS + ["typesafe_noul"]:
    costs, latencies = zip(*stats[name])
    cost = mean(costs)
    latency = mean(latencies)
    print(
        f"{name:<{name_w}}{len(costs):>7}{latency * 1000:>9.0f}ms"
        f"{'$' + format(cost, '.6f'):>13}"
        f"{format(latency / typesafe_latency, '.1f') + 'x':>11}"
        f"{format(cost / typesafe_cost, '.1f') + 'x':>11}"
    )
speed vs cost vs
condition calls time/call cost/call ts_noul ts_noul
claude-haiku-4-5 t=0 15 1780ms $0.001798 16.0x 42.2x
claude-haiku-4-5 t=default 15 1644ms $0.001798 14.8x 42.2x
claude-haiku-4-5 yes/no t=0 15 1485ms $0.001650 13.4x 38.8x
gpt-5.4-mini t=0 15 1405ms $0.001089 12.7x 25.6x
gpt-5.4-mini t=default 15 1177ms $0.001179 10.6x 27.7x
gpt-5.4-mini yes/no t=0 15 1113ms $0.000950 10.0x 22.3x
gpt-5.5-reasoning 15 11125ms $0.033157 100.2x 778.9x
claude-opus-4-8-reasoning 15 13886ms $0.034275 125.0x 805.1x
typesafe_noul 15 111ms $0.000043 1.0x 1.0xこの実行では、TypeSafe の往復レイテンシの平均は 111ms です。LLM の条件は、上記の 並行設定のもとで 1 回あたり 1.1 秒から 13.9 秒の範囲です。
プロット:すべてのサンプルをヒートマップで
読み方:
- 外側の行グループ:質問。
- 内側の行:条件。
- 列:ルーブリック呼び出し 1 回分。
- セルの色:赤は P(yes) が高いこと、緑は低いことを表します。リスクに関する質問では、赤いセルが ルーブリックが警告したものです。
typesafe_noul は covered(0.43 から 0.53)と exclusion(0.53 から
0.62)で最も変動します。一部の LLM の行は温度 0 でも変動します。判断が分かれる場面では条件間で食い違います。
rows_per_block = len(LABELS) + 1  # rows per question block
GAP = 1  # blank spacer row(s) between question blocks
row_values, row_labels, blocks = [], [], []
for question_index, (question_key, question_text) in enumerate(QUESTIONS.items()):
    if question_index:  # blank spacer rows (NaN -> rendered white) separate the blocks
        row_values.extend([np.nan] * NUM_SAMPLES for _ in range(GAP))
        row_labels.extend([""] * GAP)
    blocks.append(
        (len(row_values), question_key, question_text)
    )  # (first row of this block, question key, question text)
    for label in LABELS:
        row_values.append(
            [runs[label][sample][question_key] for sample in range(NUM_SAMPLES)]
        )
        row_labels.append(label)
    row_values.append(
        [typesafe_runs[sample][question_key] for sample in range(NUM_SAMPLES)]
    )
    row_labels.append("typesafe_noul")
heatmap_matrix = np.array(row_values)
cmap = plt.get_cmap("RdYlGn_r").copy()  # red = higher P(yes), green = lower P(yes)
cmap.set_bad("white")  # spacer (NaN) rows render as blank

fig, ax = plt.subplots(figsize=(11, 0.26 * len(row_values) + 1))
ax.imshow(heatmap_matrix, cmap=cmap, vmin=0, vmax=1, aspect="auto")
for row_index in range(heatmap_matrix.shape[0]):
    for col_index in range(heatmap_matrix.shape[1]):
        value = heatmap_matrix[row_index, col_index]
        if np.isnan(value):
            continue
        ax.text(
            col_index,
            row_index,
            f"{value:.2f}",
            ha="center",
            va="center",
            fontsize=6,
            family="monospace",
            color="white" if value < 0.22 or value > 0.78 else "black",
        )

ax.set_xticks(range(NUM_SAMPLES))
ax.set_xticklabels(range(1, NUM_SAMPLES + 1), fontsize=7)
ax.set_xlabel("rubric query")
ax.set_yticks(range(len(row_labels)))
ax.set_yticklabels(row_labels, fontsize=7)
ax.tick_params(length=0)
for edge in ("top", "right", "left", "bottom"):
    ax.spines[edge].set_visible(False)

# outer level of the multi-index: the question key, printed once per block and centered, with the
# question text wrapped right under it
y_axis_transform = ax.get_yaxis_transform()
for start, question_key, question_text in blocks:
    center = start + (rows_per_block - 1) / 2
    ax.text(
        -0.2,
        center - 0.7,
        question_key,
        transform=y_axis_transform,
        ha="right",
        va="center",
        fontsize=8,
        fontweight="bold",
    )
    ax.text(
        -0.2,
        center + 0.1,
        textwrap.fill(question_text, 34),
        transform=y_axis_transform,
        ha="right",
        va="top",
        fontsize=6,
        style="italic",
        color="gray",
    )

ax.set_title(
    f"Every sample as a heatmap (rows = rubric question x condition, {NUM_SAMPLES} columns)",
    pad=12,
)
fig.tight_layout()
display(fig)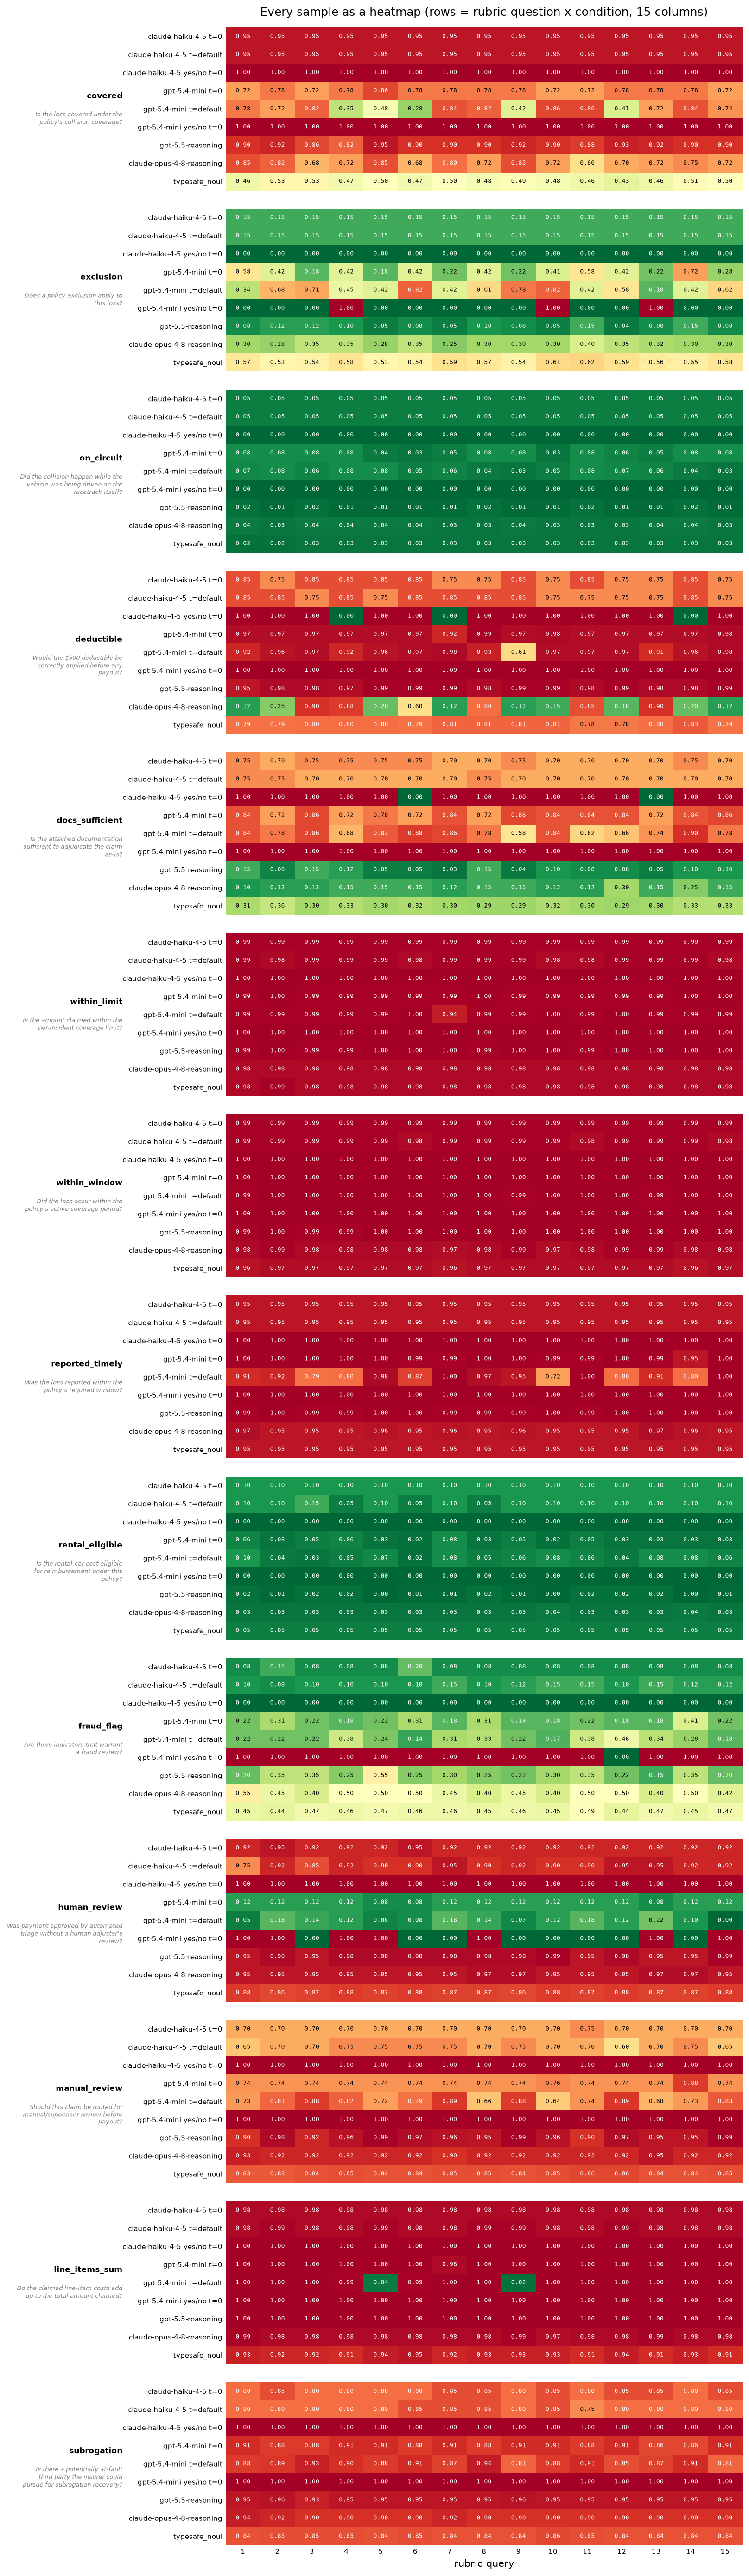
事実確認はほとんどの条件で安定しています。判断の比重が大きいものこそ、
LLM の行が動くところです:exclusion、rental_eligible、fraud_flag、manual_review は
サンプル間で変動したり、モデル間で食い違ったりします。TypeSafe の covered の行は 0.5 をまたぎ、
他の 13 問はこの実行を通じてそのしきい値の片側にとどまります。
はい/いいえを強制する代わりに、不確かな意思決定を許す
しきい値が 0.5 のとき、確率 0.49 と 0.51 は、どちらも大きな不確かさを表しているのに
反対のアクションを引き起こします。アプリケーションは代わりに次を返せます。
0.30未満はno、0.30から0.70まで(両端を含む)はuncertain、0.70より大きい場合はyes。
不確かなケースは人間に回されます。このエスカレーションは、返された確率に対する アプリケーション側のロジックです。新しい質問も 2 回目の API 呼び出しもありません。この帯は例示であり、 キャリブレーションされた保証でも最適化されたしきい値でもありません。本番の境界は、ラベル付きの 例と、誤った意思決定およびレビューのコストから決めてください。
以下の図では、この帯を記録された TypeSafe の確率に適用します。
def noul_decision_with_uncertainty(probability: float) -> str:
    """Map valid TypeSafe probabilities through an inclusive uncertainty band."""
    if probability < NOUL_UNCERTAINTY_LOW:
        return "no"
    if probability > NOUL_UNCERTAINTY_HIGH:
        return "yes"
    return "uncertain"

# Keep the probabilities visible beneath each TypeSafe application decision.
policy_decisions = [
    [noul_decision_with_uncertainty(sample[key]) for sample in typesafe_runs]
    for key in QUESTIONS
]
decision_codes = {"no": 0, "uncertain": 1, "yes": 2}
policy_values = [
    [decision_codes[value] for value in row] for row in policy_decisions
]
policy_cmap = ListedColormap(["#a6dba0", "#dddddd", "#92c5de"])
fig_policy, ax_policy = plt.subplots(figsize=(13, 6))
ax_policy.imshow(policy_values, cmap=policy_cmap, vmin=0, vmax=2, aspect="auto")
for row_index, key in enumerate(QUESTIONS):
    for sample_index in range(NUM_SAMPLES):
        decision = policy_decisions[row_index][sample_index]
        probability = typesafe_runs[sample_index][key]
        ax_policy.text(sample_index, row_index, f"{decision}\n{probability:.2f}",
                       ha="center", va="center", fontsize=6)
ax_policy.set_yticks(range(len(QUESTIONS)), list(QUESTIONS))
ax_policy.set_xticks(range(NUM_SAMPLES), range(1, NUM_SAMPLES + 1))
ax_policy.set_xlabel("rubric query")
ax_policy.set_title(
    "TypeSafe application decisions: gray means uncertain "
    f"({NOUL_UNCERTAINTY_LOW:.2f} to {NOUL_UNCERTAINTY_HIGH:.2f} inclusive)"
)
fig_policy.tight_layout()
display(fig_policy)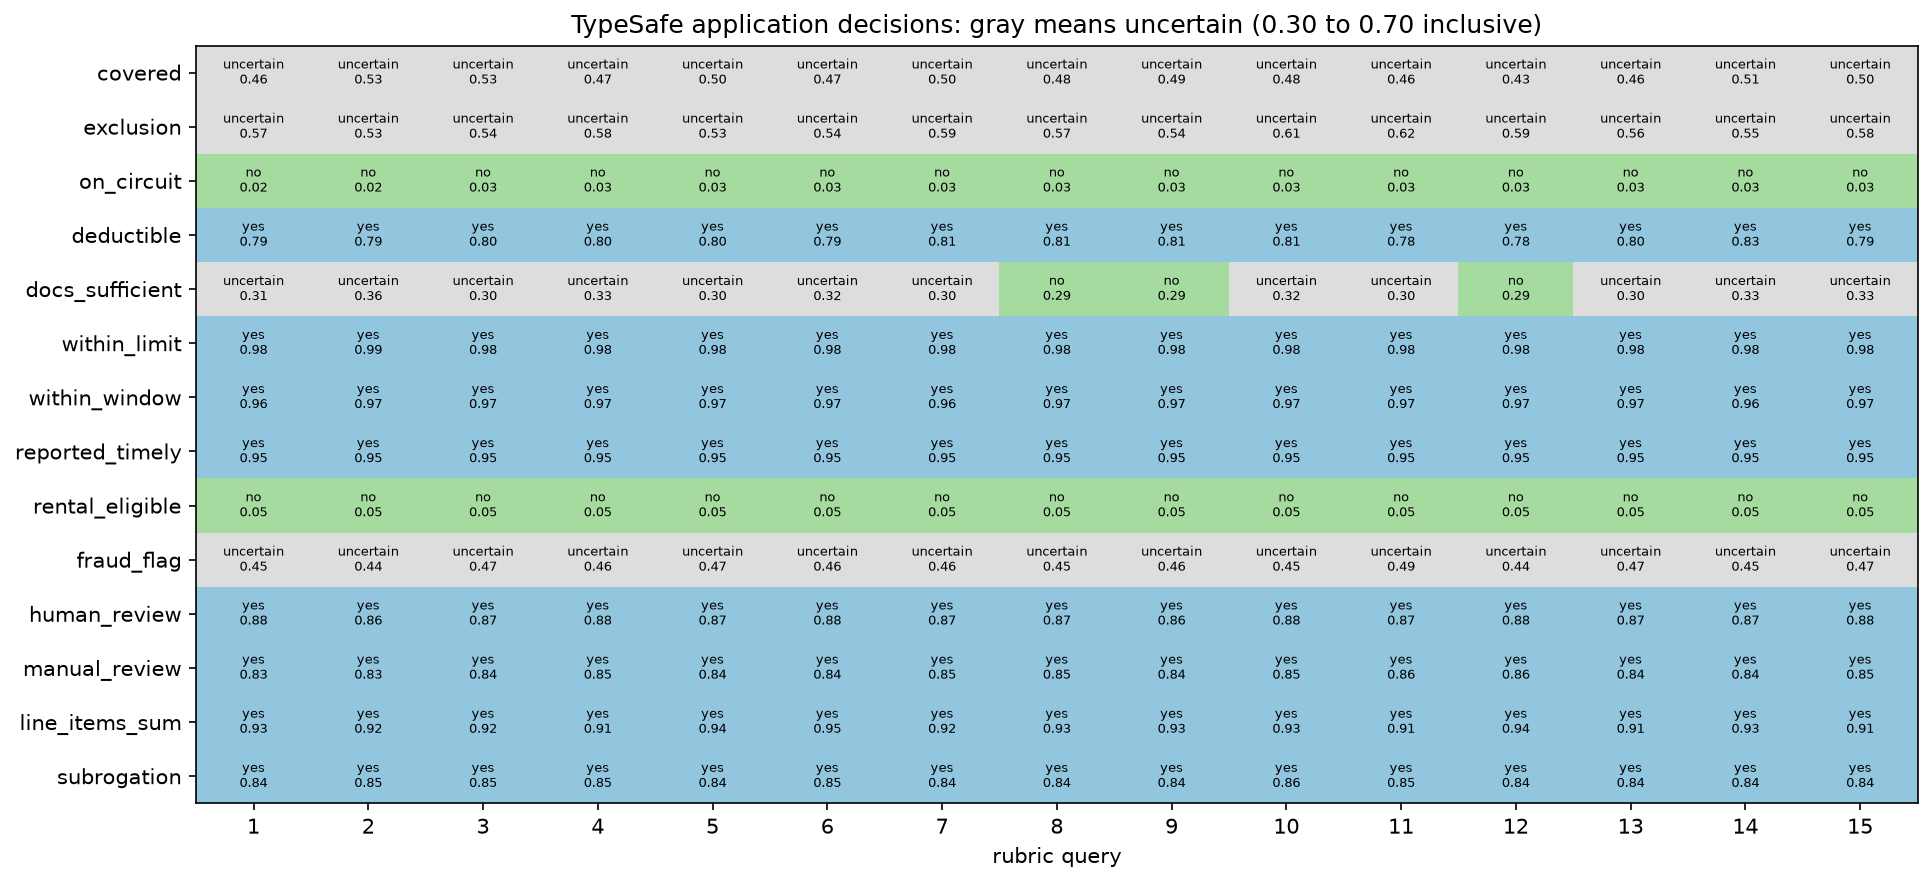
レビューの帯は、0.5 付近の変動を吸収し、反対の自動処理を出さずに済みます。
ただし、この帯にも端があります。どちらか外側の境界に近い値は、
uncertain と yes/no の間を行き来しえます。それによってモデルが決定論的になるわけではなく、
この帯を通過した自動的な意思決定が正しいと示されるわけでもありません。
TypeSafe プレイグラウンドで開く
以下のリンクは、同じ請求とルーブリックをプレイグラウンドで開きます。1 件の請求、同じ 14 問の
Noul 質問、そして TypeSafe の jev-latest です。上で使った、変化する uid フィールドは含みません。
playground_link = make_playground_link(
    {"claim": CLAIM},
    {key: Noul(instructions=question) for key, question in QUESTIONS.items()},
    models=[TYPESAFE_MODEL],
)
display(
    Markdown(
        f"🔗 [Open this claim + rubric in the TypeSafe playground]({playground_link})"
    )
)